mirror of
https://github.com/supabase/supabase.git
synced 2026-10-08 19:05:06 +03:00
Merge branch 'master' into feat/vercel-integration-v2
This commit is contained in:
 Alaister Young committed
commit
b45c4674bc
596 files changed
+37485
-53758
No files matched your search
@@ -14,11 +14,13 @@ jobs:
|
||||
uses: reviewdog/action-misspell@v1
|
||||
with:
|
||||
github_token: ${{ secrets.github_token }}
|
||||
locale: "US"
|
||||
locale: 'US'
|
||||
reporter: github-pr-review
|
||||
level: error
|
||||
exclude: |
|
||||
"*.css"
|
||||
"**/package.json"
|
||||
"**/package-lock.json"
|
||||
".git/*"
|
||||
*.css
|
||||
**/package.json
|
||||
**/package-lock.json
|
||||
./.git/*
|
||||
*.ipynb
|
||||
./i18n/README.*.md
|
||||
@@ -4,7 +4,7 @@ on:
|
||||
pull_request:
|
||||
branches: ['master']
|
||||
paths:
|
||||
- 'apps/docs/**/*.{ts,tsx}'
|
||||
- 'apps/docs/**/*.ts*'
|
||||
|
||||
jobs:
|
||||
build:
|
||||
@@ -12,7 +12,7 @@ jobs:
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
node-version: [16.x]
|
||||
node-version: [18.x]
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
|
||||
@@ -20,7 +20,7 @@ jobs:
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
node-version: [16.x]
|
||||
node-version: [18.x]
|
||||
# See supported Node.js release schedule at https://nodejs.org/en/about/releases/
|
||||
|
||||
steps:
|
||||
@@ -36,6 +36,6 @@ jobs:
|
||||
- name: Run tests
|
||||
env:
|
||||
# Default is 2 GB, increase to have less frequent OOM errors
|
||||
NODE_OPTIONS: "--max_old_space_size=3072"
|
||||
NODE_OPTIONS: '--max_old_space_size=3072'
|
||||
run: npm run test:studio
|
||||
working-directory: ./
|
||||
@@ -12,7 +12,7 @@ jobs:
|
||||
|
||||
strategy:
|
||||
matrix:
|
||||
node-version: [16.x]
|
||||
node-version: [18.x]
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
|
||||
+8
-9
@@ -17,14 +17,13 @@
|
||||
|
||||
## Getting started
|
||||
|
||||
Thanks for your interest in [Supabase](https://supabase.com) and for wanting to contribute! Before you begin, read the
|
||||
[code of conduct](https://github.com/supabase/.github/blob/main/CODE_OF_CONDUCT.md) and check out the
|
||||
[existing issues](https://github.com/supabase/supabase/issues).
|
||||
This document describes how to set up your development environment to build and test [Supabase](https://supabase.com).
|
||||
Thank you for expressing your interest in [Supabase](https://supabase.com) and your willingness to contribute!
|
||||
|
||||
To ensure a positive and inclusive environment, we kindly request you to read our [code of conduct](https://github.com/supabase/.github/blob/main/CODE_OF_CONDUCT.md). Additionally, we encourage you to explore the existing [issues](https://github.com/supabase/supabase/issues) to see how you can make a meaningful impact. This document will guide you through the process of setting up your development environment, enabling you to successfully build and test [Supabase](https://supabase.com).
|
||||
|
||||
### Install dependencies
|
||||
|
||||
You need to install and configure the following dependencies on your machine to build [Supabase](https://supabase.com):
|
||||
You will need to install and configure the following dependencies on your machine to build [Supabase](https://supabase.com):
|
||||
|
||||
- [Git](http://git-scm.com/)
|
||||
- [Node.js v16.x (LTS)](http://nodejs.org)
|
||||
@@ -48,7 +47,7 @@ To contribute code to [Supabase](https://supabase.com), you must fork the [Supab
|
||||
git clone https://github.com/<github_username>/supabase.git
|
||||
```
|
||||
|
||||
1. Go to the Supabase directory:
|
||||
2. Go to the Supabase directory:
|
||||
```sh
|
||||
cd supabase
|
||||
```
|
||||
@@ -63,7 +62,7 @@ To contribute code to [Supabase](https://supabase.com), you must fork the [Supab
|
||||
npm install # install dependencies
|
||||
```
|
||||
|
||||
2. You can then run the apps simultaneously with the following.
|
||||
2. After that you can run the apps simultaneously with the following.
|
||||
```sh
|
||||
npm run dev # start all the applications
|
||||
```
|
||||
@@ -121,7 +120,7 @@ Now when you run a local development docs server you will see the new docs site.
|
||||
|
||||
After making your changes, open a pull request (PR). Once you submit your pull request, others from the Supabase team/community will review it with you.
|
||||
|
||||
Did you have an issue, like a merge conflict, or don't know how to open a pull request? Check out [GitHub's pull request](https://docs.github.com/en/pull-requests/collaborating-with-pull-requests) tutorial on how to resolve merge conflicts and other issues. Once your PR has been merged, you will be proudly listed as a contributor in the [contributor chart](https://github.com/supabase/supabase/graphs/contributors).
|
||||
If you have an issue, like a merge conflict, or don't know how to open a pull request then check out [GitHub's pull request](https://docs.github.com/en/pull-requests/collaborating-with-pull-requests) tutorial on how to resolve merge conflicts and other issues. Once your PR has been merged, you will be proudly listed as a contributor in the [contributor chart](https://github.com/supabase/supabase/graphs/contributors).
|
||||
|
||||
---
|
||||
|
||||
@@ -135,7 +134,7 @@ Create a new entry in the [`redirects.js`](https://github.com/supabase/supabase/
|
||||
|
||||
## Community channels
|
||||
|
||||
Stuck somewhere? Have any questions? Join the [Discord Community Server](https://discord.supabase.com/) or the [Github Discussions](https://github.com/supabase/supabase/discussions). We are here to help!
|
||||
If you are stuck somewhere or have any questions, join our [Discord Community Server](https://discord.supabase.com/) or the [Github Discussions](https://github.com/supabase/supabase/discussions). We are here to help!
|
||||
|
||||
## Contributors
|
||||
|
||||
|
||||
@@ -19,6 +19,7 @@
|
||||
- [x] Database Functions. [Docs](https://supabase.com/docs/guides/database/functions)
|
||||
- [x] Edge Functions [Docs](https://supabase.com/docs/guides/functions)
|
||||
- [x] File Storage. [Docs](https://supabase.com/docs/guides/storage)
|
||||
- [x] AI + Vector/Embeddings Toolkit. [Docs](https://supabase.com/docs/guides/ai)
|
||||
- [x] Dashboard
|
||||
|
||||
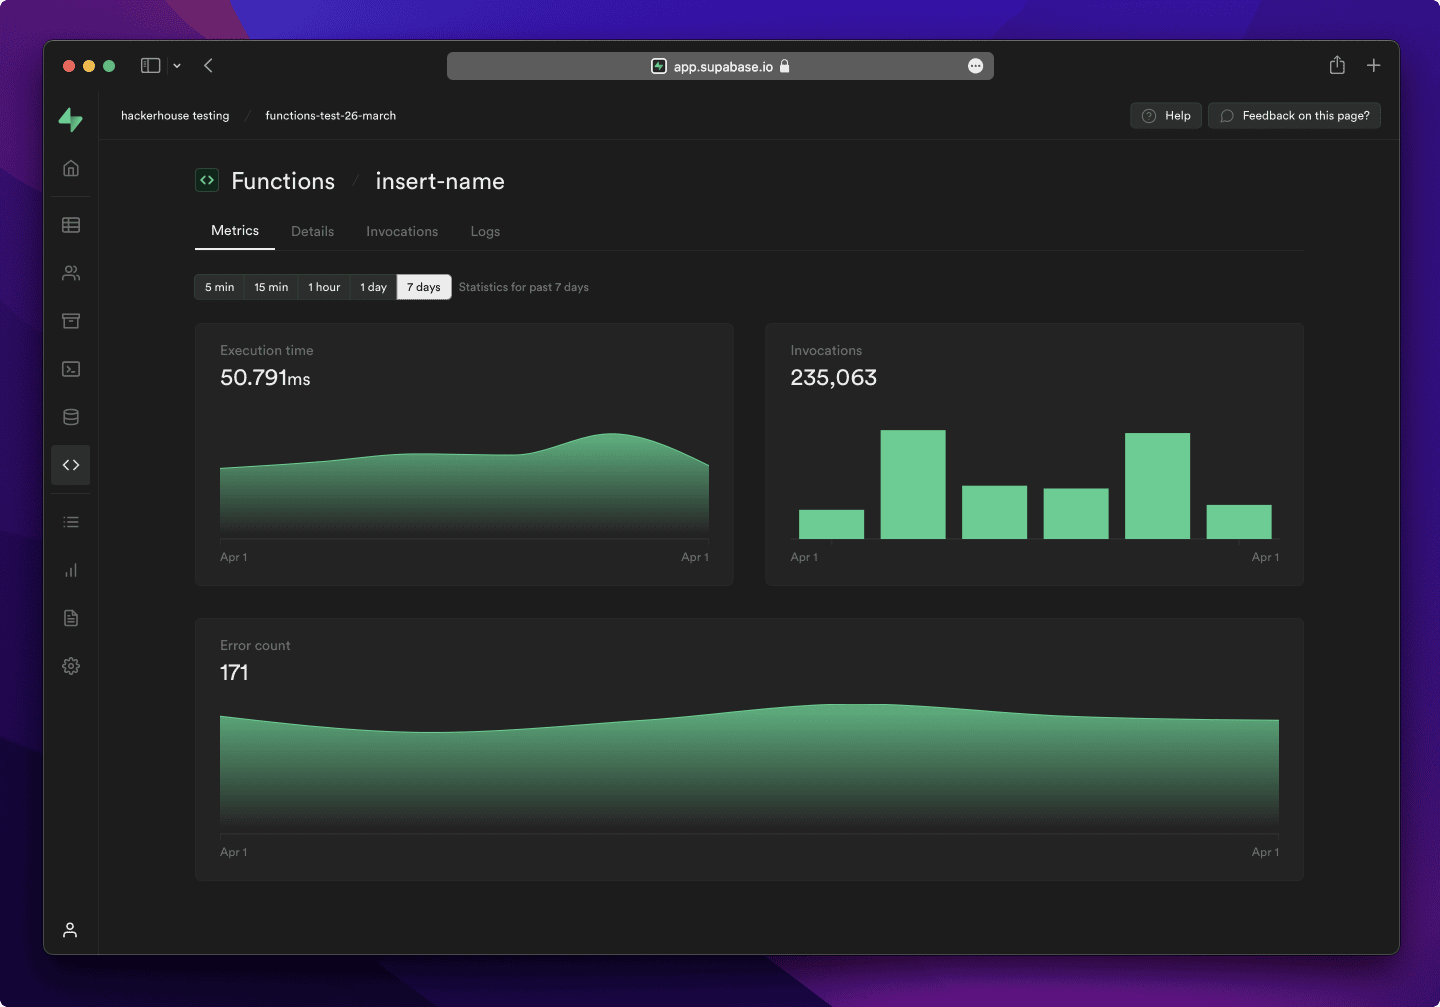
|
||||
@@ -79,6 +80,7 @@ Our approach for client libraries is modular. Each sub-library is a standalone i
|
||||
<th>Client</th>
|
||||
<th colspan="5">Feature-Clients (bundled in Supabase client)</th>
|
||||
</tr>
|
||||
<!-- notranslate -->
|
||||
<tr>
|
||||
<th></th>
|
||||
<th>Supabase</th>
|
||||
@@ -99,7 +101,9 @@ Our approach for client libraries is modular. Each sub-library is a standalone i
|
||||
<td><a href="https://github.com/supabase-community/storage-lang" target="_blank" rel="noopener noreferrer">storage-lang</a></td>
|
||||
</tr>
|
||||
END ROW -->
|
||||
<!-- /notranslate -->
|
||||
<th colspan="7">⚡️ Official ⚡️</th>
|
||||
<!-- notranslate -->
|
||||
<tr>
|
||||
<td>JavaScript (TypeScript)</td>
|
||||
<td><a href="https://github.com/supabase/supabase-js" target="_blank" rel="noopener noreferrer">supabase-js</a></td>
|
||||
@@ -118,7 +122,9 @@ Our approach for client libraries is modular. Each sub-library is a standalone i
|
||||
<td><a href="https://github.com/supabase/storage-dart" target="_blank" rel="noopener noreferrer">storage-dart</a></td>
|
||||
<td><a href="https://github.com/supabase/functions-dart" target="_blank" rel="noopener noreferrer">functions-dart</a></td>
|
||||
</tr>
|
||||
<!-- /notranslate -->
|
||||
<th colspan="7">💚 Community 💚</th>
|
||||
<!-- notranslate -->
|
||||
<tr>
|
||||
<td>C#</td>
|
||||
<td><a href="https://github.com/supabase-community/supabase-csharp" target="_blank" rel="noopener noreferrer">supabase-csharp</a></td>
|
||||
@@ -200,6 +206,7 @@ Our approach for client libraries is modular. Each sub-library is a standalone i
|
||||
<td><a href="https://github.com/supabase-community/storage-gdscript" target="_blank" rel="noopener noreferrer">storage-gdscript</a></td>
|
||||
<td><a href="https://github.com/supabase-community/functions-gdscript" target="_blank" rel="noopener noreferrer">functions-gdscript</a></td>
|
||||
</tr>
|
||||
<!-- /notranslate -->
|
||||
</table>
|
||||
|
||||
<!--- Remove this list if you're translating to another language, it's hard to keep updated across multiple files-->
|
||||
@@ -212,23 +219,28 @@ Our approach for client libraries is modular. Each sub-library is a standalone i
|
||||
- [Bangla / বাংলা](/i18n/README.bn.md)
|
||||
- [Bulgarian / Български](/i18n/README.bg.md)
|
||||
- [Catalan / Català](/i18n/README.ca.md)
|
||||
- [Czech / čeština](/i18n/README.cs.md)
|
||||
- [Danish / Dansk](/i18n/README.da.md)
|
||||
- [Dutch / Nederlands](/i18n/README.nl.md)
|
||||
- [English](https://github.com/supabase/supabase)
|
||||
- [Estonian / eesti keel](/i18n/README.et.md)
|
||||
- [Finnish / Suomalainen](/i18n/README.fi.md)
|
||||
- [French / Français](/i18n/README.fr.md)
|
||||
- [German / Deutsch](/i18n/README.de.md)
|
||||
- [Greek / Ελληνικά](/i18n/README.gr.md)
|
||||
- [Greek / Ελληνικά](/i18n/README.el.md)
|
||||
- [Gujarati / ગુજરાતી](/i18n/README.gu.md)
|
||||
- [Hebrew / עברית](/i18n/README.he.md)
|
||||
- [Hindi / हिंदी](/i18n/README.hi.md)
|
||||
- [Hungarian / Magyar](/i18n/README.hu.md)
|
||||
- [Nepali / नेपाली](/i18n/README.ne.md)
|
||||
- [Indonesian / Bahasa Indonesia](/i18n/README.id.md)
|
||||
- [Italian / Italiano](/i18n/README.it.md)
|
||||
- [Japanese / 日本語](/i18n/README.jp.md)
|
||||
- [Italiano / Italian](/i18n/README.it.md)
|
||||
- [Japanese / 日本語](/i18n/README.ja.md)
|
||||
- [Korean / 한국어](/i18n/README.ko.md)
|
||||
- [Lithuanian / lietuvių](/i18n/README.lt.md)
|
||||
- [Latvian / latviski](/i18n/README.lv.md)
|
||||
- [Malay / Bahasa Malaysia](/i18n/README.ms.md)
|
||||
- [Norwegian (Bokmål) / Norsk (Bokmål)](/i18n/README.nb-no.md)
|
||||
- [Norwegian (Bokmål) / Norsk (Bokmål)](/i18n/README.nb.md)
|
||||
- [Persian / فارسی](/i18n/README.fa.md)
|
||||
- [Polish / Polski](/i18n/README.pl.md)
|
||||
- [Portuguese / Português](/i18n/README.pt.md)
|
||||
@@ -237,6 +249,8 @@ Our approach for client libraries is modular. Each sub-library is a standalone i
|
||||
- [Russian / Pусский](/i18n/README.ru.md)
|
||||
- [Serbian / Srpski](/i18n/README.sr.md)
|
||||
- [Sinhala / සිංහල](/i18n/README.si.md)
|
||||
- [Slovak / slovenský](/i18n/README.sk.md)
|
||||
- [Slovenian / Slovenščina](/i18n/README.sl.md)
|
||||
- [Spanish / Español](/i18n/README.es.md)
|
||||
- [Simplified Chinese / 简体中文](/i18n/README.zh-cn.md)
|
||||
- [Swedish / Svenska](/i18n/README.sv.md)
|
||||
@@ -247,8 +261,3 @@ Our approach for client libraries is modular. Each sub-library is a standalone i
|
||||
- [Vietnamese / Tiếng Việt](/i18n/README.vi-vn.md)
|
||||
- [List of translations](/i18n/languages.md) <!--- Keep only this -->
|
||||
|
||||
---
|
||||
|
||||
## Sponsors
|
||||
|
||||
[](https://github.com/sponsors/supabase)
|
||||
@@ -1,372 +0,0 @@
|
||||
module.exports = {
|
||||
name: 'Stripe Docs Blue',
|
||||
type: 'dark',
|
||||
colors: {
|
||||
'editor.background': '#232323',
|
||||
'editor.foreground': '#fafafa',
|
||||
'activityBar.background': 'var(--colors-scale2)',
|
||||
'sideBar.background': 'yellow',
|
||||
'editorGroupHeader.tabsBackground': 'var(--colors-scale2)',
|
||||
'sideBarSectionHeader.background': 'var(--colors-scale2)',
|
||||
'tab.activeBackground': 'var(--colors-scale3)',
|
||||
'tab.inactiveBackground': 'var(--colors-scale2)',
|
||||
'tab.border': 'var(--colors-scale2)',
|
||||
'input.background': '#ffffff1a',
|
||||
'panel.background': '#1A2652',
|
||||
'panel.border': '#1A2652',
|
||||
'editorWidget.background': '#0d0f2b',
|
||||
'editorWidget.foreground': '#ffffff4d',
|
||||
'editorWidget.border': 'var(--colors-scale5)',
|
||||
'list.hoverBackground': '#ffffff1a',
|
||||
'list.activeSelectionBackground': '#ffffff1a',
|
||||
'list.inactiveSelectionBackground': '#ffffff1a',
|
||||
'editor.hoverHighlightBackground': '#ffffff1a',
|
||||
'editor.selectionHighlightBackground': '#ffffff1a',
|
||||
'activityBarBadge.background': 'yellow',
|
||||
'sideBarTitle.foreground': 'var(--colors-scale2)',
|
||||
'statusBar.background': 'var(--colors-scale2)',
|
||||
},
|
||||
tokenColors: [
|
||||
{
|
||||
name: 'Comment',
|
||||
scope: ['comment', 'punctuation.definition.comment'],
|
||||
settings: {
|
||||
foreground: '#a3acb9',
|
||||
fontStyle: '',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Variables',
|
||||
scope: ['source', 'variable', 'variable.other.object', 'string constant.other.placeholder'],
|
||||
settings: {
|
||||
foreground: '#f5fbff',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Colors',
|
||||
scope: ['variable.other.constant', 'constant.other.color'],
|
||||
settings: {
|
||||
foreground: '#ffffff',
|
||||
fontStyle: 'bold',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Invalid',
|
||||
scope: ['invalid', 'invalid.illegal'],
|
||||
settings: {
|
||||
foreground: '#FF5370',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Keyword, Storage',
|
||||
scope: ['keyword', 'storage.type', 'storage.modifier'],
|
||||
settings: {
|
||||
foreground: '#98C1FE',
|
||||
fontStyle: 'bold',
|
||||
},
|
||||
},
|
||||
|
||||
{
|
||||
name: 'Function',
|
||||
scope: ['entity.name.function'],
|
||||
settings: {
|
||||
foreground: '#7fd3ed',
|
||||
fontStyle: 'bold',
|
||||
},
|
||||
},
|
||||
|
||||
{
|
||||
name: 'Tag',
|
||||
scope: ['entity.name.tag', 'meta.tag.sgml', 'markup.deleted.git_gutter'],
|
||||
settings: {
|
||||
foreground: '#98C1FE',
|
||||
fontStyle: 'bold',
|
||||
},
|
||||
},
|
||||
|
||||
{
|
||||
name: 'Parameter, Property',
|
||||
scope: [
|
||||
'variable.parameter',
|
||||
'variable.other.object.property',
|
||||
'variable.other.property',
|
||||
'keyword.other.unit',
|
||||
'keyword.other',
|
||||
],
|
||||
settings: {
|
||||
foreground: '#F2AFE3',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Number, Constant, Function Argument, Tag Attribute, Embedded',
|
||||
scope: [
|
||||
'constant.numeric',
|
||||
'constant.language',
|
||||
'support.constant',
|
||||
'constant.character',
|
||||
'constant.escape',
|
||||
],
|
||||
settings: {
|
||||
foreground: '#f8b886',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'String, Symbols, Inherited Class, Markup Heading',
|
||||
scope: [
|
||||
'string',
|
||||
'constant.other.symbol',
|
||||
'constant.other.key',
|
||||
'entity.other.inherited-class',
|
||||
'markup.heading',
|
||||
'markup.inserted.git_gutter',
|
||||
'meta.group.braces.curly constant.other.object.key.js string.unquoted.label.js',
|
||||
],
|
||||
settings: {
|
||||
foreground: '#85d99e',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Entity Types',
|
||||
scope: ['support.type'],
|
||||
settings: {
|
||||
foreground: '#B2CCD6',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'CSS Class and Support',
|
||||
scope: [
|
||||
'source.css support.type.property-name',
|
||||
'source.sass support.type.property-name',
|
||||
'source.scss support.type.property-name',
|
||||
'source.less support.type.property-name',
|
||||
'source.stylus support.type.property-name',
|
||||
'source.postcss support.type.property-name',
|
||||
],
|
||||
settings: {
|
||||
foreground: '#B2CCD6',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Language methods',
|
||||
scope: ['variable.language'],
|
||||
settings: {
|
||||
fontStyle: 'italic',
|
||||
foreground: '#FF5370',
|
||||
},
|
||||
},
|
||||
|
||||
{
|
||||
name: 'Attributes',
|
||||
scope: ['entity.other.attribute-name'],
|
||||
settings: {
|
||||
foreground: '#98C1FE',
|
||||
fontStyle: 'italic',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Inserted',
|
||||
scope: ['markup.inserted'],
|
||||
settings: {
|
||||
foreground: '#C3E88D',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Deleted',
|
||||
scope: ['markup.deleted'],
|
||||
settings: {
|
||||
foreground: '#FF5370',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Changed',
|
||||
scope: ['markup.changed'],
|
||||
settings: {
|
||||
foreground: '#C792EA',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Regular Expressions',
|
||||
scope: ['string.regexp'],
|
||||
settings: {
|
||||
foreground: '#89DDFF',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Escape Characters',
|
||||
scope: ['constant.character.escape'],
|
||||
settings: {
|
||||
foreground: '#89DDFF',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'URL',
|
||||
scope: ['*url*', '*link*', '*uri*'],
|
||||
settings: {
|
||||
fontStyle: 'underline',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'ES7 Bind Operator',
|
||||
scope: ['source.js constant.other.object.key.js string.unquoted.label.js'],
|
||||
settings: {
|
||||
fontStyle: 'italic',
|
||||
foreground: '#FF5370',
|
||||
},
|
||||
},
|
||||
|
||||
{
|
||||
name: 'Markdown - Plain',
|
||||
scope: ['text.html', 'punctuation.definition.list_item'],
|
||||
settings: {
|
||||
foreground: '#f5fbff',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Markup Raw Inline',
|
||||
scope: ['text.html.markdown markup.inline.raw.markdown'],
|
||||
settings: {
|
||||
foreground: '#C792EA',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Markup Raw Inline Punctuation',
|
||||
scope: ['text.html.markdown markup.inline.raw.markdown punctuation.definition.raw.markdown'],
|
||||
settings: {
|
||||
foreground: '#65737E',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Heading',
|
||||
scope: [
|
||||
'markdown.heading',
|
||||
'markup.heading | markup.heading entity.name',
|
||||
'markup.heading.markdown punctuation.definition.heading.markdown',
|
||||
],
|
||||
settings: {
|
||||
foreground: '#C3E88D',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markup - Italic',
|
||||
scope: ['markup.italic'],
|
||||
settings: {
|
||||
fontStyle: 'italic',
|
||||
foreground: '#f07178',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markup - Bold',
|
||||
scope: ['markup.bold', 'markup.bold string'],
|
||||
settings: {
|
||||
fontStyle: 'bold',
|
||||
foreground: '#f07178',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markup - Bold-Italic',
|
||||
scope: [
|
||||
'markup.bold markup.italic',
|
||||
'markup.italic markup.bold',
|
||||
'markup.quote markup.bold',
|
||||
'markup.bold markup.italic string',
|
||||
'markup.italic markup.bold string',
|
||||
'markup.quote markup.bold string',
|
||||
],
|
||||
settings: {
|
||||
fontStyle: 'bold',
|
||||
foreground: '#f07178',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markup - Underline',
|
||||
scope: ['markup.underline'],
|
||||
settings: {
|
||||
fontStyle: 'underline',
|
||||
foreground: '#F78C6C',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Blockquote',
|
||||
scope: ['markup.quote punctuation.definition.blockquote.markdown'],
|
||||
settings: {
|
||||
foreground: '#65737E',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markup - Quote',
|
||||
scope: ['markup.quote'],
|
||||
settings: {
|
||||
fontStyle: 'italic',
|
||||
},
|
||||
},
|
||||
|
||||
{
|
||||
name: 'Markdown - Link Description',
|
||||
scope: ['string.other.link.description.title.markdown'],
|
||||
settings: {
|
||||
foreground: '#C792EA',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Link Anchor',
|
||||
scope: ['constant.other.reference.link.markdown'],
|
||||
settings: {
|
||||
foreground: '#FFCB6B',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markup - Raw Block',
|
||||
scope: ['markup.raw.block'],
|
||||
settings: {
|
||||
foreground: '#C792EA',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Raw Block Fenced',
|
||||
scope: ['markup.raw.block.fenced.markdown'],
|
||||
settings: {
|
||||
foreground: '#00000050',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Fenced Bode Block',
|
||||
scope: ['punctuation.definition.fenced.markdown'],
|
||||
settings: {
|
||||
foreground: '#00000050',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Fenced Bode Block Variable',
|
||||
scope: [
|
||||
'markup.raw.block.fenced.markdown',
|
||||
'variable.language.fenced.markdown',
|
||||
'punctuation.section.class.end',
|
||||
],
|
||||
settings: {
|
||||
foreground: '#EEFFFF',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Fenced Language',
|
||||
scope: ['variable.language.fenced.markdown'],
|
||||
settings: {
|
||||
foreground: '#65737E',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markdown - Separator',
|
||||
scope: ['meta.separator'],
|
||||
settings: {
|
||||
fontStyle: 'bold',
|
||||
foreground: '#65737E',
|
||||
},
|
||||
},
|
||||
{
|
||||
name: 'Markup - Table',
|
||||
scope: ['markup.table'],
|
||||
settings: {
|
||||
foreground: '#EEFFFF',
|
||||
},
|
||||
},
|
||||
],
|
||||
}
|
||||
@@ -1,13 +1,12 @@
|
||||
import { FC } from 'react'
|
||||
import { IconInfo, IconHelpCircle, IconAlertTriangle } from 'ui'
|
||||
import { PropsWithChildren } from 'react'
|
||||
import { IconAlertTriangle, IconHelpCircle, IconInfo } from 'ui'
|
||||
|
||||
interface Props {
|
||||
export interface AdmonitionProps {
|
||||
type: 'note' | 'tip' | 'info' | 'caution' | 'danger'
|
||||
label?: string
|
||||
children: any
|
||||
}
|
||||
|
||||
const Admonition: FC<Props> = ({ type = 'note', label, children }) => {
|
||||
const Admonition = ({ type = 'note', label, children }: PropsWithChildren<AdmonitionProps>) => {
|
||||
return (
|
||||
<div
|
||||
className={[
|
||||
|
||||
@@ -0,0 +1,193 @@
|
||||
import { useState } from 'react'
|
||||
import { Input, Button } from 'ui'
|
||||
import Admonition from '~/components/Admonition'
|
||||
|
||||
function base64URL(value: string) {
|
||||
return globalThis.btoa(value).replace(/[=]/g, '').replace(/[+]/g, '-').replace(/[\/]/g, '_')
|
||||
}
|
||||
|
||||
/*
|
||||
Convert a string into an ArrayBuffer
|
||||
from https://developers.google.com/web/updates/2012/06/How-to-convert-ArrayBuffer-to-and-from-String
|
||||
*/
|
||||
function stringToArrayBuffer(value: string) {
|
||||
const buf = new ArrayBuffer(value.length)
|
||||
const bufView = new Uint8Array(buf)
|
||||
for (let i = 0; i < value.length; i++) {
|
||||
bufView[i] = value.charCodeAt(i)
|
||||
}
|
||||
return buf
|
||||
}
|
||||
|
||||
function arrayBufferToString(buf) {
|
||||
return String.fromCharCode.apply(null, new Uint8Array(buf))
|
||||
}
|
||||
|
||||
const generateAppleSecretKey = async (
|
||||
kid: string,
|
||||
iss: string,
|
||||
sub: string,
|
||||
file: File
|
||||
): Promise<{ kid: string; jwt: string; exp: number }> => {
|
||||
if (!kid) {
|
||||
const match = file.name.match(/AuthKey_([^.]+)[.].*$/i)
|
||||
if (match && match[1]) {
|
||||
kid = match[1]
|
||||
}
|
||||
}
|
||||
|
||||
if (!kid) {
|
||||
throw new Error(
|
||||
`No Key ID provided. The file "${file.name}" does not follow the AuthKey_XXXXXXXXXX.p8 pattern. Please provide a Key ID manually.`
|
||||
)
|
||||
}
|
||||
|
||||
const contents = await file.text()
|
||||
|
||||
if (!contents.match(/^\s*-+BEGIN PRIVATE KEY-+[^-]+-+END PRIVATE KEY-+\s*$/i)) {
|
||||
throw new Error(`Chosen file does not appear to be a PEM encoded PKCS8 private key file.`)
|
||||
}
|
||||
|
||||
// remove PEM headers and spaces
|
||||
const pkcs8 = stringToArrayBuffer(
|
||||
globalThis.atob(contents.replace(/-+[^-]+-+/g, '').replace(/\s+/g, ''))
|
||||
)
|
||||
|
||||
const privateKey = await globalThis.crypto.subtle.importKey(
|
||||
'pkcs8',
|
||||
pkcs8,
|
||||
{
|
||||
name: 'ECDSA',
|
||||
namedCurve: 'P-256',
|
||||
},
|
||||
true,
|
||||
['sign']
|
||||
)
|
||||
|
||||
const iat = Math.floor(Date.now() / 1000)
|
||||
const exp = iat + 180 * 24 * 60 * 60
|
||||
|
||||
const jwt = [
|
||||
base64URL(JSON.stringify({ typ: 'JWT', kid, alg: 'ES256' })),
|
||||
base64URL(
|
||||
JSON.stringify({
|
||||
iss,
|
||||
sub,
|
||||
iat,
|
||||
exp,
|
||||
aud: 'https://appleid.apple.com',
|
||||
})
|
||||
),
|
||||
]
|
||||
|
||||
const signature = await globalThis.crypto.subtle.sign(
|
||||
{
|
||||
name: 'ECDSA',
|
||||
hash: 'SHA-256',
|
||||
},
|
||||
privateKey,
|
||||
stringToArrayBuffer(jwt.join('.'))
|
||||
)
|
||||
|
||||
jwt.push(base64URL(arrayBufferToString(signature)))
|
||||
|
||||
return { kid, jwt: jwt.join('.'), exp }
|
||||
}
|
||||
|
||||
const AppleSecretGenerator = () => {
|
||||
const [file, setFile] = useState({ file: null as File | null })
|
||||
const [teamID, setTeamID] = useState('')
|
||||
const [serviceID, setServiceID] = useState('')
|
||||
const [keyID, setKeyID] = useState('')
|
||||
const [secretKey, setSecretKey] = useState('')
|
||||
const [expiresAt, setExpiresAt] = useState('')
|
||||
const [error, setError] = useState('')
|
||||
|
||||
return (
|
||||
<>
|
||||
<Input
|
||||
label="Account ID"
|
||||
labelOptional="required"
|
||||
placeholder="Apple Developer account ID, 10 alphanumeric digits"
|
||||
descriptionText="Found in the upper-right corner of Apple Developer Center."
|
||||
value={teamID}
|
||||
onChange={(e) => setTeamID(e.target.value.trim())}
|
||||
/>
|
||||
<Input
|
||||
label="Service ID"
|
||||
labelOptional="required"
|
||||
placeholder="ID of the service, example: com.example.app.service"
|
||||
descriptionText="Found under Certificates, Identifiers & Profiles in Apple Developer Center."
|
||||
value={serviceID}
|
||||
onChange={(e) => setServiceID(e.target.value.trim())}
|
||||
/>
|
||||
<Input
|
||||
label="Key ID"
|
||||
labelOptional="(optional)"
|
||||
placeholder="Extracted from filename, AuthKey_XXXXXXXXXX.p8"
|
||||
descriptionText="If the file you select does not preserve the original name from Apple Developer Center, please enter the key ID."
|
||||
value={keyID}
|
||||
onChange={(e) => setKeyID(e.target.value.trim())}
|
||||
/>
|
||||
<div>
|
||||
<input
|
||||
type="file"
|
||||
onChange={(e) => {
|
||||
setFile({ file: e.target.files[0] })
|
||||
}}
|
||||
/>
|
||||
</div>
|
||||
<div style={{ height: '1rem' }} />
|
||||
|
||||
<Button
|
||||
size="medium"
|
||||
disabled={
|
||||
!(
|
||||
teamID.length === 10 &&
|
||||
serviceID &&
|
||||
((globalThis && globalThis.showOpenFilePicker) || file.file)
|
||||
)
|
||||
}
|
||||
onClick={async () => {
|
||||
setError('')
|
||||
|
||||
try {
|
||||
const { kid, jwt, exp } = await generateAppleSecretKey(
|
||||
keyID,
|
||||
teamID,
|
||||
serviceID,
|
||||
file.file
|
||||
)
|
||||
setKeyID(kid)
|
||||
setSecretKey(jwt)
|
||||
setExpiresAt(new Date(exp * 1000).toString())
|
||||
setError('')
|
||||
} catch (e: any) {
|
||||
setError(e.message)
|
||||
console.error(e)
|
||||
}
|
||||
}}
|
||||
>
|
||||
Generate Secret Key
|
||||
</Button>
|
||||
|
||||
{error && <Admonition type="danger">{error}</Admonition>}
|
||||
|
||||
{secretKey && (
|
||||
<>
|
||||
<div style={{ height: '1rem' }} />
|
||||
<Input
|
||||
label="Secret Key"
|
||||
value={secretKey}
|
||||
descriptionText={`Valid until: ${expiresAt}. Make sure you generate a new one before then!`}
|
||||
reveal
|
||||
copy
|
||||
size="medium"
|
||||
/>
|
||||
</>
|
||||
)}
|
||||
</>
|
||||
)
|
||||
}
|
||||
|
||||
export default AppleSecretGenerator
|
||||
File renamed without changes.
@@ -17,7 +17,7 @@ const HomePageCover = (props) => {
|
||||
p-5 md:p-8
|
||||
"
|
||||
>
|
||||
<div className="col-span-full flex flex-col md:flex-row xl:flex-col justify-between gap-1 md:gap-6">
|
||||
<div className="col-span-full flex flex-col md:flex-row xl:flex-col justify-between gap-1 md:gap-3">
|
||||
<div className="md:max-w-xs xl:max-w-none">
|
||||
<div className="flex items-center gap-3 mb-3">
|
||||
<IconBackground>
|
||||
@@ -29,7 +29,7 @@ const HomePageCover = (props) => {
|
||||
Discover how to set up a database to an app making queries in just a few minutes.
|
||||
</p>
|
||||
</div>
|
||||
<div className="flex flex-wrap md:grid md:grid-cols-4 gap-2 sm:gap-3">
|
||||
<div className="flex flex-wrap md:grid md:grid-cols-4 2xl:grid-cols-7 gap-2 sm:gap-3">
|
||||
<Link href={`/guides/getting-started/quickstarts/reactjs`} passHref>
|
||||
<a className="no-underline">
|
||||
<IconPanel
|
||||
@@ -118,7 +118,7 @@ const HomePageCover = (props) => {
|
||||
</p>
|
||||
</div>
|
||||
</div>
|
||||
<div className="w-full xl:max-w-[365px] -mb-40">
|
||||
<div className="w-full xl:max-w-[365px] 2xl:max-w-[608px] -mb-40">
|
||||
<GettingStarted />
|
||||
</div>
|
||||
</div>
|
||||
|
||||
@@ -0,0 +1,5 @@
|
||||
## Deployment
|
||||
|
||||
If you have your own infrastructure for deploying Python apps, you can continue to use `vecs` as described in this guide.
|
||||
|
||||
Alternatively if you would like to quickly deploy using Supabase, check out our guide on using the [Hugging Face Inference API](/docs/guides/ai/hugging-face) in Edge Functions using TypeScript.
|
||||
@@ -0,0 +1,18 @@
|
||||
import { Tabs } from 'ui'
|
||||
export const TabPanel = Tabs.Panel
|
||||
|
||||
## Project setup
|
||||
|
||||
Let's create a new Postgres database. This is as simple as starting a new Project in Supabase:
|
||||
|
||||
1. [Create a new project](https://database.new/) in the Supabase dashboard.
|
||||
1. Enter your project details. Remember to store your password somewhere safe.
|
||||
|
||||
Your database will be available in less than a minute.
|
||||
|
||||
**Finding your credentials:**
|
||||
|
||||
You can find your project credentials inside the project [settings](https://app.supabase.com/project/_/settings/), including:
|
||||
|
||||
- [Database credentials](https://app.supabase.com/project/_/settings/database): connection strings and connection pooler details.
|
||||
- [API credentials](https://app.supabase.com/project/_/settings/database): your serverless API URL and `anon` / `service_role` keys.
|
||||
@@ -11,7 +11,7 @@ Enable the [http extension for the `extensions` schema](https://app.supabase.com
|
||||
Then, define the following SQL functions in the SQL Editor to delete
|
||||
storage objects via the API:
|
||||
|
||||
```SQL
|
||||
```sql
|
||||
create or replace function delete_storage_object(bucket text, object text, out status int, out content text)
|
||||
returns record
|
||||
language 'plpgsql'
|
||||
@@ -52,7 +52,7 @@ $$;
|
||||
Next, add a trigger that removes any obsolete avatar whenever the
|
||||
profile is updated or deleted:
|
||||
|
||||
```SQL
|
||||
```sql
|
||||
create or replace function delete_old_avatar()
|
||||
returns trigger
|
||||
language 'plpgsql'
|
||||
@@ -89,7 +89,7 @@ Finally, delete the `public.profile` row before a user is deleted.
|
||||
If this step is omitted, you won't be able to delete users without
|
||||
first manually deleting their avatar image.
|
||||
|
||||
```SQL
|
||||
```sql
|
||||
create or replace function delete_old_profile()
|
||||
returns trigger
|
||||
language 'plpgsql'
|
||||
|
||||
@@ -21,6 +21,7 @@ import {
|
||||
IconMenuSwift,
|
||||
IconMenuStatus,
|
||||
IconMenuKotlin,
|
||||
IconMenuAI,
|
||||
} from './HomeMenuIcons'
|
||||
|
||||
function getMenuIcon(menuKey: string, width: number = 16, height: number = 16) {
|
||||
@@ -41,6 +42,8 @@ function getMenuIcon(menuKey: string, width: number = 16, height: number = 16) {
|
||||
return <IconMenuRealtime width={width} height={height} />
|
||||
case 'storage':
|
||||
return <IconMenuStorage width={width} height={height} />
|
||||
case 'ai':
|
||||
return <IconMenuAI width={width} height={height} />
|
||||
case 'platform':
|
||||
return <IconMenuPlatform width={width} height={height} />
|
||||
case 'resources':
|
||||
|
||||
@@ -356,8 +356,28 @@ export function IconMenuStorage({ width = 16, height = 16 }: HomeMenuIcon) {
|
||||
<path
|
||||
d="M13 7.616V5.6l-3.618-3.6H3v4.03m9.964-.447L9.38 2v3.584h3.584ZM1.974 6v8h12V7.509h-7.59l-1.533-1.51H1.974Z"
|
||||
stroke="currentColor"
|
||||
stroke-miterlimit="10"
|
||||
stroke-linejoin="bevel"
|
||||
/>
|
||||
</svg>
|
||||
)
|
||||
}
|
||||
|
||||
export function IconMenuAI({ width = 16, height = 16 }: HomeMenuIcon) {
|
||||
return (
|
||||
<svg
|
||||
width={width}
|
||||
height={height}
|
||||
viewBox="0 0 16 16"
|
||||
fill="none"
|
||||
xmlns="http://www.w3.org/2000/svg"
|
||||
>
|
||||
<path
|
||||
d="M7.99886 7.63216V14.4892M7.99886 7.63216L14.0488 4.11804M7.99886 7.63216L1.94922 4.11819M1.94922 4.11819V8.32332M1.94922 4.11819V4.08217L5.57319 1.97717M14.049 8.36007V4.08217L10.4251 1.97717M11.8165 12.4072L7.99913 14.6245L4.18177 12.4072"
|
||||
stroke="currentColor"
|
||||
strokeMiterlimit="10"
|
||||
strokeLinejoin="bevel"
|
||||
strokeLinecap="round"
|
||||
strokeLinejoin="round"
|
||||
/>
|
||||
</svg>
|
||||
)
|
||||
|
||||
@@ -52,6 +52,12 @@ export const HOMEPAGE_MENU_ITEMS: HomepageMenuItems = [
|
||||
href: '/guides/storage',
|
||||
level: 'storage',
|
||||
},
|
||||
{
|
||||
label: 'AI & Vectors',
|
||||
icon: 'ai',
|
||||
href: '/guides/ai',
|
||||
level: 'ai',
|
||||
},
|
||||
],
|
||||
[
|
||||
{
|
||||
@@ -280,15 +286,6 @@ export const gettingstarted: NavMenuConstant = {
|
||||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'AI & ML',
|
||||
items: [
|
||||
{
|
||||
name: 'Vector Search with OpenAI',
|
||||
url: '/guides/getting-started/openai/vector-search',
|
||||
},
|
||||
],
|
||||
},
|
||||
],
|
||||
}
|
||||
|
||||
@@ -475,6 +472,7 @@ export const auth = {
|
||||
items: [
|
||||
{ name: 'Overview', url: '/guides/auth/auth-helpers' },
|
||||
{ name: 'Auth UI', url: '/guides/auth/auth-helpers/auth-ui' },
|
||||
{ name: 'Flutter Auth UI', url: '/guides/auth/auth-helpers/flutter-auth-ui' },
|
||||
{
|
||||
name: 'Next.js',
|
||||
url: '/guides/auth/auth-helpers/nextjs',
|
||||
@@ -511,14 +509,37 @@ export const database: NavMenuConstant = {
|
||||
title: 'Database',
|
||||
url: '/guides/database',
|
||||
items: [
|
||||
{ name: 'Database Connections', url: '/guides/database/connecting-to-postgres' },
|
||||
{ name: 'Tables and Data', url: '/guides/database/tables' },
|
||||
{ name: 'Database Functions', url: '/guides/database/functions' },
|
||||
{ name: 'Database Webhooks', url: '/guides/database/webhooks' },
|
||||
{ name: 'Full Text Search', url: '/guides/database/full-text-search' },
|
||||
{ name: 'Database Testing', url: '/guides/database/testing' },
|
||||
{ name: 'Managing Secrets with Vault', url: '/guides/database/vault' },
|
||||
{ name: 'Column Encryption', url: '/guides/database/column-encryption' },
|
||||
{ name: 'Overview', url: '/guides/database' },
|
||||
{
|
||||
name: 'Fundamentals',
|
||||
url: undefined,
|
||||
items: [
|
||||
{ name: 'Connecting to your database', url: '/guides/database/connecting-to-postgres' },
|
||||
{ name: 'Managing tables, views, and data', url: '/guides/database/tables' },
|
||||
{ name: 'Managing database functions', url: '/guides/database/functions' },
|
||||
{ name: 'Managing indexes', url: '/guides/database/postgres/indexes' },
|
||||
{ name: 'Managing database webhooks', url: '/guides/database/webhooks' },
|
||||
{ name: 'Managing database replication', url: '/guides/database/replication' },
|
||||
{ name: 'Managing secrets with Vault', url: '/guides/database/vault' },
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'Postgres Guides',
|
||||
url: undefined,
|
||||
items: [
|
||||
{
|
||||
name: 'JSON and unstructured data',
|
||||
url: '/guides/database/json',
|
||||
},
|
||||
{ name: 'Implementing Full Text Search', url: '/guides/database/full-text-search' },
|
||||
{ name: 'Implementing Cascade Deletes', url: '/guides/database/postgres/cascade-deletes' },
|
||||
{ name: 'Implementing column encryption', url: '/guides/database/column-encryption' },
|
||||
{ name: 'Testing your database', url: '/guides/database/testing' },
|
||||
{ name: 'Managing Timeouts', url: '/guides/database/timeouts' },
|
||||
{ name: 'Managing Passwords', url: '/guides/database/managing-passwords' },
|
||||
{ name: 'Configuring Timezones', url: '/guides/database/managing-timezones' },
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'Extensions',
|
||||
url: undefined,
|
||||
@@ -625,17 +646,9 @@ export const database: NavMenuConstant = {
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'Postgres resources',
|
||||
name: 'Examples',
|
||||
url: undefined,
|
||||
items: [
|
||||
{
|
||||
name: 'Managing Indexes',
|
||||
url: '/guides/database/postgres/indexes',
|
||||
},
|
||||
{
|
||||
name: 'Cascade Deletes',
|
||||
url: '/guides/database/postgres/cascade-deletes',
|
||||
},
|
||||
{
|
||||
name: 'Drop All Tables in Schema',
|
||||
url: '/guides/database/postgres/dropping-all-tables-in-schema',
|
||||
@@ -650,16 +663,6 @@ export const database: NavMenuConstant = {
|
||||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'Configuration',
|
||||
url: undefined,
|
||||
items: [
|
||||
{ name: 'Timeouts', url: '/guides/database/timeouts' },
|
||||
{ name: 'Replication', url: '/guides/database/replication' },
|
||||
{ name: 'Passwords', url: '/guides/database/managing-passwords' },
|
||||
{ name: 'Timezones', url: '/guides/database/managing-timezones' },
|
||||
],
|
||||
},
|
||||
],
|
||||
}
|
||||
|
||||
@@ -729,7 +732,7 @@ export const functions: NavMenuConstant = {
|
||||
url: undefined,
|
||||
items: [
|
||||
{ name: 'Developing Functions locally', url: '/guides/functions/local-development' },
|
||||
{ name: 'Deploying with Git', url: '/guides/functions/cicd-workflow' },
|
||||
{ name: 'Deploying with GitHub', url: '/guides/functions/cicd-workflow' },
|
||||
{ name: 'Managing Secrets and Environment Variables', url: '/guides/functions/secrets' },
|
||||
{ name: 'Integrating With Supabase Auth', url: '/guides/functions/auth' },
|
||||
{
|
||||
@@ -750,8 +753,8 @@ export const functions: NavMenuConstant = {
|
||||
items: [
|
||||
{ name: 'Dart Edge on Supabase', url: '/guides/functions/dart-edge' },
|
||||
{ name: 'Browserless.io', url: '/guides/functions/examples/screenshots' },
|
||||
{ name: 'Hugging Face', url: '/guides/functions/examples/huggingface-image-captioning' },
|
||||
{ name: 'OpenAI API', url: '/guides/functions/examples/openai' },
|
||||
{ name: 'Hugging Face', url: '/guides/ai/examples/huggingface-image-captioning' },
|
||||
{ name: 'OpenAI API', url: '/guides/ai/examples/openai' },
|
||||
{ name: 'Upstash Redis', url: '/guides/functions/examples/upstash-redis' },
|
||||
{ name: 'Type-Safe SQL with Kysely', url: '/guides/functions/kysely-postgres' },
|
||||
],
|
||||
@@ -760,7 +763,7 @@ export const functions: NavMenuConstant = {
|
||||
name: 'Examples',
|
||||
url: '/guides/functions/examples',
|
||||
items: [
|
||||
{ name: 'Generating OpenAI GPT3 completions', url: '/guides/functions/examples/openai' },
|
||||
{ name: 'Generating OpenAI GPT3 completions', url: '/guides/ai/examples/openai' },
|
||||
{ name: 'Generating OG images ', url: '/guides/functions/examples/og-image' },
|
||||
{
|
||||
name: 'CAPTCHA support with Cloudflare Turnstile',
|
||||
@@ -857,6 +860,102 @@ export const storage: NavMenuConstant = {
|
||||
],
|
||||
}
|
||||
|
||||
export const ai: NavMenuConstant = {
|
||||
icon: 'ai',
|
||||
title: 'AI & Vectors',
|
||||
url: '/guides/ai',
|
||||
items: [
|
||||
{ name: 'Overview', url: '/guides/ai' },
|
||||
{ name: 'Concepts', url: '/guides/ai/concepts' },
|
||||
{
|
||||
name: 'Structured & unstructured',
|
||||
url: '/guides/ai/structured-unstructured',
|
||||
},
|
||||
{
|
||||
name: 'Quickstarts',
|
||||
url: undefined,
|
||||
items: [
|
||||
{ name: 'Developing locally with Vecs', url: '/guides/ai/vecs-python-client' },
|
||||
{ name: 'Creating and managing collections', url: '/guides/ai/quickstarts/hello-world' },
|
||||
{ name: 'Text Deduplication', url: '/guides/ai/quickstarts/text-deduplication' },
|
||||
{ name: 'Face similarity search', url: '/guides/ai/quickstarts/face-similarity' },
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'Python Client',
|
||||
url: undefined,
|
||||
items: [
|
||||
{ name: 'API', url: '/guides/ai/python/api' },
|
||||
{ name: 'Collections', url: '/guides/ai/python/collections' },
|
||||
{ name: 'Indexes', url: '/guides/ai/python/indexes' },
|
||||
{ name: 'Metadata', url: '/guides/ai/python/metadata' },
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'Guides',
|
||||
url: undefined,
|
||||
items: [
|
||||
{ name: 'Managing collections', url: '/guides/ai/managing-collections' },
|
||||
{ name: 'Managing indexes', url: '/guides/ai/managing-indexes' },
|
||||
{ name: 'Vector columns', url: '/guides/ai/vector-columns' },
|
||||
{ name: 'Engineering for scale', url: '/guides/ai/engineering-for-scale' },
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'Examples',
|
||||
url: undefined,
|
||||
items: [
|
||||
{
|
||||
name: 'OpenAI completions using Edge Functions',
|
||||
url: '/guides/ai/examples/openai',
|
||||
},
|
||||
{
|
||||
name: 'Image search with OpenAI CLIP',
|
||||
url: '/guides/ai/examples/image-search-openai-clip',
|
||||
},
|
||||
{
|
||||
name: 'Generate image captions using Hugging Face',
|
||||
url: '/guides/ai/examples/huggingface-image-captioning',
|
||||
},
|
||||
{
|
||||
name: 'Building ChatGPT Plugins',
|
||||
url: '/guides/ai/examples/building-chatgpt-plugins',
|
||||
},
|
||||
{
|
||||
name: 'Adding generative Q&A to your documentation',
|
||||
url: '/guides/ai/examples/headless-vector-search',
|
||||
},
|
||||
{
|
||||
name: 'Adding generative Q&A to your Next.js site',
|
||||
url: '/guides/ai/examples/nextjs-vector-search',
|
||||
},
|
||||
],
|
||||
},
|
||||
{
|
||||
name: 'Third-Party Tools',
|
||||
url: undefined,
|
||||
items: [
|
||||
{
|
||||
name: 'LangChain',
|
||||
url: '/guides/ai/langchain',
|
||||
},
|
||||
{
|
||||
name: 'Hugging Face',
|
||||
url: '/guides/ai/hugging-face',
|
||||
},
|
||||
{
|
||||
name: 'Google Colab',
|
||||
url: '/guides/ai/google-colab',
|
||||
},
|
||||
{
|
||||
name: 'LlamaIndex',
|
||||
url: '/guides/ai/integrations/llamaindex',
|
||||
},
|
||||
],
|
||||
},
|
||||
],
|
||||
}
|
||||
|
||||
export const supabase_cli: NavMenuConstant = {
|
||||
icon: 'reference-cli',
|
||||
title: 'Supabase CLI',
|
||||
@@ -1096,7 +1195,7 @@ export const integrations: NavMenuConstant = {
|
||||
items: [
|
||||
{ name: 'Cloudflare Workers', url: '/guides/integrations/cloudflare-workers' },
|
||||
{ name: 'Estuary', url: '/guides/integrations/estuary' },
|
||||
{ name: 'OpenAI', url: '/guides/functions/examples/openai' },
|
||||
{ name: 'OpenAI', url: '/guides/ai/examples/openai' },
|
||||
{ name: 'pgMustard', url: '/guides/integrations/pgmustard' },
|
||||
{ name: 'Prisma', url: '/guides/integrations/prisma' },
|
||||
{ name: 'Sequin', url: '/guides/integrations/sequin' },
|
||||
|
||||
@@ -68,6 +68,11 @@ const menus: Menu[] = [
|
||||
path: '/guides/storage',
|
||||
type: 'guide',
|
||||
},
|
||||
{
|
||||
id: 'ai',
|
||||
path: '/guides/ai',
|
||||
type: 'guide',
|
||||
},
|
||||
{
|
||||
id: 'platform',
|
||||
path: '/guides/platform',
|
||||
|
||||
@@ -16,12 +16,13 @@ import FunctionsExamples from './FunctionsExamples'
|
||||
import { Mermaid } from 'mdx-mermaid/lib/Mermaid'
|
||||
import RefSubLayout from '~/layouts/ref/RefSubLayout'
|
||||
import { Heading } from './CustomHTMLElements'
|
||||
import DatabaseSetup from './MDX/database_setup.mdx'
|
||||
import ProjectSetup from './MDX/project_setup.mdx'
|
||||
import QuickstartIntro from './MDX/quickstart_intro.mdx'
|
||||
import SocialProviderSettingsSupabase from './MDX/social_provider_settings_supabase.mdx'
|
||||
import SocialProviderSetup from './MDX/social_provider_setup.mdx'
|
||||
import StorageManagement from './MDX/storage_management.mdx'
|
||||
// import { CH } from '@code-hike/mdx/components'
|
||||
import { CH } from '@code-hike/mdx/components'
|
||||
import RefHeaderSection from './reference/RefHeaderSection'
|
||||
|
||||
// Ref version specific
|
||||
@@ -58,6 +59,7 @@ const components = {
|
||||
Admonition,
|
||||
Button,
|
||||
ButtonCard,
|
||||
CH,
|
||||
CodeBlock,
|
||||
GlassPanel,
|
||||
Link,
|
||||
@@ -66,6 +68,7 @@ const components = {
|
||||
FunctionsExamples,
|
||||
JwtGenerator,
|
||||
QuickstartIntro,
|
||||
DatabaseSetup,
|
||||
ProjectSetup,
|
||||
SocialProviderSetup,
|
||||
SocialProviderSettingsSupabase,
|
||||
|
||||
@@ -41,7 +41,7 @@ _Optionally_ if you are using custom configuration with `createClient` then foll
|
||||
>
|
||||
<TabPanel id="1.0x" label="Before">
|
||||
|
||||
```ts title=src/supabaseClient.ts
|
||||
```ts src/supabaseClient.ts
|
||||
const supabase = createClient(SUPABASE_URL, SUPABASE_ANON_KEY, {
|
||||
schema: 'custom',
|
||||
persistSession: false,
|
||||
@@ -51,7 +51,7 @@ const supabase = createClient(SUPABASE_URL, SUPABASE_ANON_KEY, {
|
||||
</TabPanel>
|
||||
<TabPanel id="2.0x" label="After">
|
||||
|
||||
```ts title=src/supabaseClient.ts
|
||||
```ts src/supabaseClient.ts
|
||||
const supabase = createClient(SUPABASE_URL, SUPABASE_ANON_KEY, {
|
||||
db: {
|
||||
schema: 'custom',
|
||||
|
||||
@@ -10,7 +10,7 @@ For `supabase-flutter`, you will be using the static `initialize()` method on `S
|
||||
|
||||
### Flutter `initialize()`
|
||||
|
||||
```dart title=main.dart
|
||||
```dart main.dart
|
||||
Future<void> main() async {
|
||||
await Supabase.initialize(url: 'https://xyzcompany.supabase.co', anonKey: 'public-anon-key');
|
||||
runApp(MyApp());
|
||||
@@ -30,7 +30,7 @@ final supabase = Supabase.instance.client;
|
||||
You can pass `headers` to initialize your Supabase client with customer headers.
|
||||
Here is an example of passing a custom auth header to Supabase client.
|
||||
|
||||
```dart title=main.dart
|
||||
```dart main.dart
|
||||
Future<void> main() async {
|
||||
await Supabase.initialize(
|
||||
url: 'https://xyzcompany.supabase.co',
|
||||
|
||||
@@ -46,6 +46,10 @@ const levelsData = {
|
||||
icon: '/docs/img/icons/menu/storage',
|
||||
name: 'Storage',
|
||||
},
|
||||
ai: {
|
||||
icon: '/docs/img/icons/menu/ai',
|
||||
name: 'AI & Vectors',
|
||||
},
|
||||
supabase_cli: {
|
||||
icon: '/docs/img/icons/menu/reference-cli',
|
||||
name: 'Supabase CLI',
|
||||
|
||||
@@ -1,7 +1,9 @@
|
||||
import fs from 'fs'
|
||||
|
||||
import { CodeHikeConfig, remarkCodeHike } from '@code-hike/mdx'
|
||||
import matter from 'gray-matter'
|
||||
import { serialize } from 'next-mdx-remote/serialize'
|
||||
import codeHikeTheme from 'config/code-hike.theme.json' assert { type: 'json' }
|
||||
import { ICommonMarkdown } from '~/components/reference/Reference.types'
|
||||
|
||||
async function generateRefMarkdown(sections: ICommonMarkdown[], slug: string) {
|
||||
@@ -31,6 +33,14 @@ async function generateRefMarkdown(sections: ICommonMarkdown[], slug: string) {
|
||||
const fileContents = markdownExists ? fs.readFileSync(pathName, 'utf8') : ''
|
||||
const { data, content } = matter(fileContents)
|
||||
|
||||
const codeHikeOptions: CodeHikeConfig = {
|
||||
theme: codeHikeTheme,
|
||||
lineNumbers: true,
|
||||
showCopyButton: true,
|
||||
skipLanguages: [],
|
||||
autoImport: false,
|
||||
}
|
||||
|
||||
markdownContent.push({
|
||||
id: section.id,
|
||||
title: section.title,
|
||||
@@ -41,8 +51,8 @@ async function generateRefMarkdown(sections: ICommonMarkdown[], slug: string) {
|
||||
// MDX's available options, see the MDX docs for more info.
|
||||
// https://mdxjs.com/packages/mdx/#compilefile-options
|
||||
mdxOptions: {
|
||||
// remarkPlugins: [[remarkCodeHike, { autoImport: false, theme }]],
|
||||
useDynamicImport: true,
|
||||
remarkPlugins: [[remarkCodeHike, codeHikeOptions]],
|
||||
},
|
||||
// Indicates whether or not to parse the frontmatter from the mdx source
|
||||
})
|
||||
|
||||
@@ -0,0 +1,31 @@
|
||||
import { Element } from 'hast'
|
||||
import { hasProperty } from 'hast-util-has-property'
|
||||
import { Node } from 'unist'
|
||||
import { visit } from 'unist-util-visit'
|
||||
|
||||
export type UrlTransformFunction = (url: string, node: Element) => string
|
||||
|
||||
function modify(node: Element, prop: string, fn?: UrlTransformFunction) {
|
||||
if (hasProperty(node, prop)) {
|
||||
const property = node.properties[prop]
|
||||
if (typeof property !== 'string') {
|
||||
return
|
||||
}
|
||||
|
||||
node.properties[prop] = fn?.(property, node) ?? property
|
||||
}
|
||||
}
|
||||
|
||||
/**
|
||||
* Transforms every HAST element that contains a `href` or `src`.
|
||||
* A `UrlTransformFunction` is called with the current URL. The
|
||||
* return value from this function will be used as the replacement.
|
||||
*/
|
||||
export function linkTransform(fn?: UrlTransformFunction) {
|
||||
return function transformer(tree: Node) {
|
||||
visit(tree, 'element', (node: Element) => {
|
||||
modify(node, 'href', fn)
|
||||
modify(node, 'src', fn)
|
||||
})
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,105 @@
|
||||
import { Content, Paragraph, Parent } from 'mdast'
|
||||
import { MdxJsxFlowElement } from 'mdast-util-mdx'
|
||||
import { Node } from 'unist'
|
||||
import { visit } from 'unist-util-visit'
|
||||
import { AdmonitionProps } from '~/components/Admonition'
|
||||
|
||||
/**
|
||||
* Transforms an `mkdocs-material` Admonition to a Supabase Admonition.
|
||||
*
|
||||
* https://squidfunk.github.io/mkdocs-material/reference/admonitions/
|
||||
*/
|
||||
const remarkMkDocsAdmonition = function () {
|
||||
return function transformer(root: Parent) {
|
||||
visit(root, 'paragraph', (paragraph: Paragraph, index: number, parent: Parent) => {
|
||||
const [firstChild] = paragraph.children
|
||||
|
||||
if (firstChild?.type === 'text') {
|
||||
const match = firstChild.value.match(/^!!! ?(.*?)\n(.*)/s)
|
||||
|
||||
if (!match) {
|
||||
return
|
||||
}
|
||||
|
||||
// Extract the admonition type along with the remaining text
|
||||
const [, type, value] = match
|
||||
|
||||
// Rewrite the node's value to remove the admonition syntax
|
||||
firstChild.value = value
|
||||
|
||||
// Extract sibling nodes that should be linked to this admonition
|
||||
const siblingsToNest = extractLinkedSiblings(parent, paragraph, index)
|
||||
|
||||
const children: any[] = [...paragraph.children, ...siblingsToNest]
|
||||
|
||||
// Generate a Supabase Admonition JSX element
|
||||
const admonitionElement: MdxJsxFlowElement = {
|
||||
type: 'mdxJsxFlowElement',
|
||||
name: 'Admonition',
|
||||
attributes: [
|
||||
{
|
||||
type: 'mdxJsxAttribute',
|
||||
name: 'type',
|
||||
value: mapAdmonitionType(type),
|
||||
},
|
||||
],
|
||||
children,
|
||||
}
|
||||
|
||||
// Overwrite original node with new element
|
||||
parent.children.splice(index, 1, admonitionElement)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
/**
|
||||
* Identifies sibling nodes that should be linked to this admonition
|
||||
* based on their indent level (ie. 4 spaces).
|
||||
*
|
||||
* Iterates through proceeding siblings until one is found that is
|
||||
* not indented relative to the original node.
|
||||
*
|
||||
* Splices the discovered siblings out of the original parent and returns them.
|
||||
*/
|
||||
function extractLinkedSiblings(parent: Parent, node: Node, index: number, indentAmount = 4) {
|
||||
const { column } = node.position.start
|
||||
|
||||
let nextSibling: Content
|
||||
let i = index
|
||||
|
||||
do {
|
||||
nextSibling = parent.children[++i]
|
||||
} while (nextSibling?.position && nextSibling.position.start.column === column + indentAmount)
|
||||
|
||||
return parent.children.splice(index + 1, i - index - 1)
|
||||
}
|
||||
|
||||
/**
|
||||
* Maps `mkdocs-material` Admonition types to Supabase Admonition types.
|
||||
*
|
||||
* https://squidfunk.github.io/mkdocs-material/reference/admonitions/#supported-types
|
||||
*/
|
||||
function mapAdmonitionType(type: string): AdmonitionProps['type'] {
|
||||
switch (type) {
|
||||
case 'quote':
|
||||
case 'example':
|
||||
case 'note':
|
||||
return 'note'
|
||||
case 'tip':
|
||||
return 'tip'
|
||||
case 'warning':
|
||||
return 'caution'
|
||||
case 'failure':
|
||||
case 'bug':
|
||||
case 'danger':
|
||||
return 'danger'
|
||||
case 'abstract':
|
||||
case 'question':
|
||||
case 'info':
|
||||
default:
|
||||
return 'info'
|
||||
}
|
||||
}
|
||||
|
||||
export default remarkMkDocsAdmonition
|
||||
@@ -0,0 +1,23 @@
|
||||
import { Parent } from 'mdast'
|
||||
|
||||
/**
|
||||
* Removes the top heading from a MD file if
|
||||
* it is the first node and it matches `title`.
|
||||
*
|
||||
* Useful when rendering title separately from MD
|
||||
* and you need to remove the duplicate.
|
||||
*/
|
||||
export function removeTitle(title: string) {
|
||||
return function transformer(root: Parent) {
|
||||
const [firstNode] = root.children
|
||||
|
||||
if (firstNode?.type === 'heading') {
|
||||
const [text] = firstNode.children
|
||||
|
||||
if (text?.type === 'text' && text.value === title) {
|
||||
// Remove this node
|
||||
root.children.splice(0, 1)
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
+22
-20
@@ -2,22 +2,18 @@
|
||||
import nextMdx from '@next/mdx'
|
||||
import remarkGfm from 'remark-gfm'
|
||||
import rehypeSlug from 'rehype-slug'
|
||||
|
||||
//import theme from 'shiki/themes/nord.json' assert { type: 'json' }
|
||||
import { remarkCodeHike } from '@code-hike/mdx'
|
||||
|
||||
import withTM from 'next-transpile-modules'
|
||||
import withYaml from 'next-plugin-yaml'
|
||||
import configureBundleAnalyzer from '@next/bundle-analyzer'
|
||||
|
||||
import codeHikeTheme from 'config/code-hike.theme.json' assert { type: 'json' }
|
||||
|
||||
const withBundleAnalyzer = configureBundleAnalyzer({
|
||||
enabled: process.env.ANALYZE === 'true',
|
||||
})
|
||||
|
||||
// import admonitions from 'remark-admonitions'
|
||||
|
||||
// import { remarkCodeHike } from '@code-hike/mdx'
|
||||
// import codeHikeTheme from './codeHikeTheme.js'
|
||||
|
||||
/**
|
||||
* Rewrites and redirects are handled by
|
||||
* apps/www nextjs config
|
||||
@@ -29,20 +25,18 @@ const withMDX = nextMdx({
|
||||
extension: /\.mdx?$/,
|
||||
options: {
|
||||
remarkPlugins: [
|
||||
// [
|
||||
// remarkCodeHike,
|
||||
// {
|
||||
// theme: codeHikeTheme,
|
||||
// autoImport: false,
|
||||
// lineNumbers: true,
|
||||
// showCopyButton: true,
|
||||
// },
|
||||
// ],
|
||||
[
|
||||
remarkCodeHike,
|
||||
{
|
||||
theme: codeHikeTheme,
|
||||
lineNumbers: true,
|
||||
showCopyButton: true,
|
||||
},
|
||||
],
|
||||
remarkGfm,
|
||||
],
|
||||
rehypePlugins: [rehypeSlug],
|
||||
// This is required for `MDXProvider` component
|
||||
// providerImportSource: '@mdx-js/react',
|
||||
providerImportSource: '@mdx-js/react',
|
||||
},
|
||||
})
|
||||
|
||||
@@ -62,7 +56,7 @@ const nextConfig = {
|
||||
'raw.githubusercontent.com',
|
||||
'weweb-changelog.ghost.io',
|
||||
'img.youtube.com',
|
||||
'archbee-image-uploads.s3.amazonaws.com'
|
||||
'archbee-image-uploads.s3.amazonaws.com',
|
||||
],
|
||||
},
|
||||
experimental: {
|
||||
@@ -109,7 +103,15 @@ const nextConfig = {
|
||||
|
||||
const configExport = () => {
|
||||
const plugins = [
|
||||
withTM(['ui', 'common', '@supabase/auth-helpers-nextjs']),
|
||||
withTM([
|
||||
'ui',
|
||||
'common',
|
||||
'@supabase/auth-helpers-nextjs',
|
||||
'mermaid',
|
||||
'mdx-mermaid',
|
||||
'dayjs',
|
||||
'shared-data',
|
||||
]),
|
||||
withMDX,
|
||||
withYaml,
|
||||
withBundleAnalyzer,
|
||||
|
||||
+23
-17
@@ -45,18 +45,19 @@
|
||||
"dependencies": {
|
||||
"@algolia/autocomplete-js": "^1.7.2",
|
||||
"@algolia/autocomplete-plugin-recent-searches": "^1.7.2",
|
||||
"@code-hike/mdx": "^0.8.3",
|
||||
"@docsearch/react": "^3.3.0",
|
||||
"@mdx-js/loader": "^1.6.22",
|
||||
"@mdx-js/react": "^1.6.22",
|
||||
"@mdx-js/loader": "^2.1.5",
|
||||
"@mdx-js/react": "^2.1.5",
|
||||
"@next/bundle-analyzer": "^13.4.0",
|
||||
"@next/mdx": "^12.0.4",
|
||||
"@next/mdx": "^12.3.2",
|
||||
"@octokit/auth-app": "^4.0.9",
|
||||
"@octokit/core": "^4.2.0",
|
||||
"@octokit/plugin-paginate-graphql": "^2.0.1",
|
||||
"@radix-ui/react-accordion": "^1.0.1",
|
||||
"@radix-ui/react-accordion": "^1.1.0",
|
||||
"@supabase/auth-helpers-nextjs": "^0.5.6",
|
||||
"@supabase/auth-helpers-react": "^0.3.1",
|
||||
"@supabase/supabase-js": "^2.13.0",
|
||||
"@supabase/supabase-js": "^2.23.0",
|
||||
"algoliasearch": "^4.14.2",
|
||||
"babel": "^6.23.0",
|
||||
"clsx": "^1.2.1",
|
||||
@@ -65,6 +66,7 @@
|
||||
"framer-motion": "^6.5.1",
|
||||
"github-slugger": "^2.0.0",
|
||||
"gray-matter": "^4.0.3",
|
||||
"hast-util-has-property": "^2.0.1",
|
||||
"isbot": "^3.6.5",
|
||||
"jsrsasign": "^10.5.26",
|
||||
"lodash": "^4.17.21",
|
||||
@@ -77,20 +79,19 @@
|
||||
"mdx-mermaid": "2.0.0-rc3",
|
||||
"mermaid": "^10.0.2",
|
||||
"micromark-extension-mdxjs": "^1.0.0",
|
||||
"next": "12.3.2",
|
||||
"next": "^12.3.2",
|
||||
"next-compose-plugins": "^2.2.1",
|
||||
"next-mdx-remote": "^4.1.0",
|
||||
"next-mdx-toc": "^0.1.3",
|
||||
"next-plugin-yaml": "^1.0.1",
|
||||
"next-seo": "^5.14.1",
|
||||
"next-transpile-modules": "^9.0.0",
|
||||
"openai": "^3.1.0",
|
||||
"react": "17.0.2",
|
||||
"react-copy-to-clipboard": "^5.0.2",
|
||||
"react-dom": "17.0.2",
|
||||
"openai": "^3.2.1",
|
||||
"react": "^17.0.2",
|
||||
"react-copy-to-clipboard": "^5.1.0",
|
||||
"react-dom": "^17.0.2",
|
||||
"react-intersection-observer": "^9.4.0",
|
||||
"react-markdown": "^8.0.3",
|
||||
"react-syntax-highlighter": "^15.3.1",
|
||||
"react-syntax-highlighter": "^15.5.0",
|
||||
"rehype-slug": "^5.1.0",
|
||||
"remark": "^14.0.2",
|
||||
"remark-admonitions": "^1.2.1",
|
||||
@@ -101,25 +102,30 @@
|
||||
"ui": "*",
|
||||
"unist-builder": "^3.0.1",
|
||||
"unist-util-filter": "^4.0.1",
|
||||
"unist-util-visit": "^4.1.2",
|
||||
"uuid": "^9.0.0",
|
||||
"valtio": "^1.7.6"
|
||||
"valtio": "^1.7.6",
|
||||
"yargs": "^17.7.2"
|
||||
},
|
||||
"devDependencies": {
|
||||
"@types/node": "^17.0.12",
|
||||
"@types/hast": "^2.3.4",
|
||||
"@types/node": "^17.0.24",
|
||||
"@types/react": "17.0.39",
|
||||
"@types/unist": "^2.0.6",
|
||||
"@types/yargs": "^17.0.24",
|
||||
"config": "*",
|
||||
"dotenv": "^16.0.3",
|
||||
"ejs": "^3.1.8",
|
||||
"eslint": "8.9.0",
|
||||
"eslint": "^8.41.0",
|
||||
"globby": "^12.0.2",
|
||||
"minimist": "^1.2.6",
|
||||
"next-transpile-modules": "9.0.0",
|
||||
"next-transpile-modules": "^9.0.0",
|
||||
"npm-run-all": "^4.1.5",
|
||||
"openapi-types": "^12.0.2",
|
||||
"sass": "^1.55.0",
|
||||
"ts-node": "^10.9.1",
|
||||
"tsconfig": "*",
|
||||
"tsx": "^3.12.2",
|
||||
"typescript": "^4.5.3"
|
||||
"typescript": "^5.0.4"
|
||||
}
|
||||
}
|
||||
@@ -1,7 +1,7 @@
|
||||
import '../../../packages/ui/build/css/themes/light.css'
|
||||
import '../../../packages/ui/build/css/themes/dark.css'
|
||||
|
||||
import '../styles/ch.scss'
|
||||
import 'config/code-hike.scss'
|
||||
import '../styles/main.scss?v=1.0.0'
|
||||
import '../styles/new-docs.scss'
|
||||
import '../styles/prism-okaidia.scss'
|
||||
|
||||
@@ -0,0 +1,149 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai',
|
||||
title: 'AI & Vectors',
|
||||
description: 'The best vector database is the database you already have.',
|
||||
subtitle: 'The best vector database is the database you already have.',
|
||||
sidebar_label: 'Overview',
|
||||
}
|
||||
|
||||
Supabase provides an open source toolkit for developing AI applications using Postgres and pgvector. Use the Supabase client libraries to store, index, and query your vector embeddings at scale.
|
||||
|
||||
The toolkit includes:
|
||||
|
||||
- A [vector store](/docs/guides/ai/vector-columns) and embeddings support using Postgres and pgvector.
|
||||
- A [Python client](/docs/guides/ai/vecs-python-client) for managing unstructured embeddings.
|
||||
- [Database migrations](/docs/guides/ai/examples/headless-vector-search#prepare-your-database) for managing structured embeddings.
|
||||
- Integrations with all popular AI providers, such as [OpenAI](/docs/guides/ai/examples/openai), [Hugging Face](/docs/guides/ai/hugging-face), [LangChain](/docs/guides/ai/langchain), and more.
|
||||
|
||||
## Examples
|
||||
|
||||
Check out all of the AI [templates and examples](https://github.com/supabase/supabase/tree/master/examples/ai) in our GitHub repository.
|
||||
|
||||
<div className="grid md:grid-cols-12 gap-4 not-prose">
|
||||
{examples.map((x) => (
|
||||
<div className="col-span-4" key={x.href}>
|
||||
<Link href={x.href} passHref>
|
||||
<a>
|
||||
<GlassPanel icon={'/docs/img/icons/github-icon'} hasLightIcon={true} title={x.name}>
|
||||
{x.description}
|
||||
</GlassPanel>
|
||||
</a>
|
||||
</Link>
|
||||
</div>
|
||||
))}
|
||||
</div>
|
||||
|
||||
export const examples = [
|
||||
{
|
||||
name: 'Headless Vector Search',
|
||||
description: 'A toolkit to perform vector similarity search on your knowledge base embeddings.',
|
||||
href: '/guides/ai/examples/headless-vector-search',
|
||||
},
|
||||
{
|
||||
name: 'Image Search with OpenAI CLIP',
|
||||
description: 'Implement image search with the OpenAI CLIP Model and Supabase Vector.',
|
||||
href: '/guides/ai/examples/image-search-openai-clip',
|
||||
},
|
||||
{
|
||||
name: 'Hugging Face inference',
|
||||
description: 'Generate image captions using Hugging Face.',
|
||||
href: '/guides/ai/examples/huggingface-image-captioning',
|
||||
},
|
||||
{
|
||||
name: 'OpenAI completions',
|
||||
description: 'Generate GPT text completions using OpenAI in Edge Functions.',
|
||||
href: '/guides/ai/examples/openai',
|
||||
},
|
||||
{
|
||||
name: 'Building ChatGPT Plugins',
|
||||
description: 'Use Supabase as a Retrieval Store for your ChatGPT plugin.',
|
||||
href: '/guides/ai/examples/building-chatgpt-plugins',
|
||||
},
|
||||
{
|
||||
name: 'Vector search with Next.js and OpenAI',
|
||||
description:
|
||||
'Learn how to build a ChatGPT-style doc search powered by Next.js, OpenAI, and Supabase.',
|
||||
href: '/guides/ai/examples/nextjs-vector-search',
|
||||
},
|
||||
]
|
||||
|
||||
## Integrations
|
||||
|
||||
<div className="grid md:grid-cols-12 gap-4 not-prose">
|
||||
{integrations.map((x) => (
|
||||
<div className="col-span-4" key={x.href}>
|
||||
<Link href={x.href} passHref>
|
||||
<a>
|
||||
<GlassPanel title={x.name}>{x.description}</GlassPanel>
|
||||
</a>
|
||||
</Link>
|
||||
</div>
|
||||
))}
|
||||
</div>
|
||||
|
||||
export const integrations = [
|
||||
{
|
||||
name: 'OpenAI',
|
||||
description:
|
||||
'OpenAI is an AI research and deployment company. Supabase provides a simple way to use OpenAI in your applications.',
|
||||
href: '/guides/ai/examples/building-chatgpt-plugins',
|
||||
},
|
||||
{
|
||||
name: 'Hugging Face',
|
||||
description:
|
||||
"Hugging Face is an open-source provider of NLP technologies. Supabase provides a simple way to use Hugging Face's models in your applications.",
|
||||
href: '/guides/ai/hugging-face',
|
||||
},
|
||||
{
|
||||
name: 'LangChain',
|
||||
description:
|
||||
'LangChain is a language-agnostic, open-source, and self-hosted API for text translation, summarization, and sentiment analysis.',
|
||||
href: '/guides/ai/langchain',
|
||||
},
|
||||
{
|
||||
name: 'LlamaIndex',
|
||||
description: 'LlamaIndex is a data framework for your LLM applications.',
|
||||
href: '/guides/ai/integrations/llamaindex',
|
||||
},
|
||||
]
|
||||
|
||||
## Case studies
|
||||
|
||||
<div className="grid md:grid-cols-12 gap-4 not-prose">
|
||||
{customers.map((x) => (
|
||||
<div className="col-span-4" key={x.href}>
|
||||
<Link href={x.href} passHref>
|
||||
<a>
|
||||
<GlassPanel title={x.name}>{x.description}</GlassPanel>
|
||||
</a>
|
||||
</Link>
|
||||
</div>
|
||||
))}
|
||||
</div>
|
||||
|
||||
export const customers = [
|
||||
{
|
||||
name: 'Berri AI Boosts Productivity by Migrating from AWS RDS to Supabase with pgvector',
|
||||
description:
|
||||
'Learn how Berri AI overcame challenges with self-hosting their vector database on AWS RDS and successfully migrated to Supabase.',
|
||||
href: 'https://supabase.com/customers/berriai',
|
||||
},
|
||||
{
|
||||
name: 'Mendable switches from Pinecone to Supabase for PostgreSQL vector embeddings',
|
||||
description:
|
||||
'How Mendable boosts efficiency and accuracy of chat powered search for documentation using Supabase with pgvector',
|
||||
href: 'https://supabase.com/customers/mendableai',
|
||||
},
|
||||
{
|
||||
name: 'Markprompt: GDPR-Compliant AI Chatbots for Docs and Websites',
|
||||
description:
|
||||
"AI-powered chatbot platform, Markprompt, empowers developers to deliver efficient and GDPR-compliant prompt experiences on top of their content, by leveraging Supabase's secure and privacy-focused database and authentication solutions",
|
||||
href: 'https://supabase.com/customers/markprompt',
|
||||
},
|
||||
]
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} hideToc={true} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,67 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-concepts',
|
||||
title: 'Concepts',
|
||||
description: 'Learn about embeddings within AI and vector applications.',
|
||||
sidebar_label: 'Concepts',
|
||||
}
|
||||
|
||||
Embeddings are a core concept when building AI and vector applications.
|
||||
|
||||
## What are embeddings?
|
||||
|
||||
Embeddings capture the "relatedness" of text, images, video, or other types of information. This relatedness is most commonly used for:
|
||||
|
||||
- **Search:** how similar is a search term to a body of text?
|
||||
- **Recommendations:** how similar are two products?
|
||||
- **Classifications:** how do we categorize a body of text?
|
||||
- **Clustering:** how do we identify trends?
|
||||
|
||||
Let's explore an example of text embeddings. Say we have three phrases:
|
||||
|
||||
1. "The cat chases the mouse"
|
||||
2. "The kitten hunts rodents"
|
||||
3. "I like ham sandwiches"
|
||||
|
||||
Your job is to group phrases with similar meaning. If you are a human, this should be obvious. Phrases 1 and 2 are almost identical, while phrase 3 has a completely different meaning.
|
||||
|
||||
Although phrases 1 and 2 are similar, they share no common vocabulary (besides "the"). Yet their meanings are nearly identical. How can we teach a computer that these are the same?
|
||||
|
||||
## Human language
|
||||
|
||||
Humans use words and symbols to communicate language. But words in isolation are mostly meaningless - we need to draw from shared knowledge & experience in order to make sense of them. The phrase “You should Google it” only makes sense if you know that Google is a search engine and that people have been using it as a verb.
|
||||
|
||||
In the same way, we need to train a neural network model to understand human language. An effective model should be trained on millions of different examples to understand what each word, phrase, sentence, or paragraph could mean in different contexts.
|
||||
|
||||
So how does this relate to embeddings?
|
||||
|
||||
## How do embeddings work?
|
||||
|
||||
Embeddings compress discrete information (words & symbols) into distributed continuous-valued data (vectors). If we took our phrases from before and plot them on a chart, it might look something like this:
|
||||
|
||||
<img src="/docs/img/ai/vector-similarity.png" alt="Vector similarity" width="640" height="640" />
|
||||
|
||||
Phrases 1 and 2 would be plotted close to each other, since their meanings are similar. We would expect phrase 3 to live somewhere far away since it isn't related. If we had a fourth phrase, “Sally ate Swiss cheese”, this might exist somewhere between phrase 3 (cheese can go on sandwiches) and phrase 1 (mice like Swiss cheese).
|
||||
|
||||
In this example we only have 2 dimensions: the X and Y axis. In reality, we would need many more dimensions to effectively capture the complexities of human language.
|
||||
|
||||
## Using embeddings
|
||||
|
||||
Compared to our 2-dimensional example above, most embedding models will output many more dimensions. For example OpenAI's `text-embedding-ada-002` model outputs 1536 dimensions.
|
||||
|
||||
Why is this useful? Once we have generated embeddings on multiple texts, it is trivial to calculate how similar they are using vector math operations like cosine distance. A common use case for this is search. Your process might look something like this:
|
||||
|
||||
1. Pre-process your knowledge base and generate embeddings for each page
|
||||
2. Store your embeddings to be referenced later
|
||||
3. Build a search page that prompts your user for input
|
||||
4. Take user's input, generate a one-time embedding, then perform a similarity search against your pre-processed embeddings.
|
||||
5. Return the most similar pages to the user
|
||||
|
||||
## See also
|
||||
|
||||
- [Structured and Unstructured embeddings](/docs/guides/ai/structured-unstructured)
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,160 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-engineering-for-scale',
|
||||
title: 'Engineering for Scale',
|
||||
description: 'Building an enterprise-grade vector architecture',
|
||||
subtitle: 'Building an enterprise-grade vector architecture.',
|
||||
sidebar_label: 'Engineering for Scale',
|
||||
}
|
||||
|
||||
Content sources for vectors can be extremely large. As you grow you should run your Vector workloads across several secondary databases (sometimes called "pods"), which allows each collection to scale independently.
|
||||
|
||||
## Simple workloads
|
||||
|
||||
For small workloads it's typical to store your data in a single database.
|
||||
|
||||
If you've used [Vecs](/docs/guides/ai/vecs-python-client) to create 3 different collections, you can expose collections to your web or mobile application using [views](/docs/guides/database/tables#views):
|
||||
|
||||
<div>
|
||||
<img
|
||||
alt="single database"
|
||||
className="dark:hidden"
|
||||
src="/docs/img/ai/scaling/engineering-for-scale--single-database--light.png"
|
||||
/>
|
||||
<img
|
||||
alt="single database"
|
||||
className="hidden dark:block"
|
||||
src="/docs/img/ai/scaling/engineering-for-scale--single-database--dark.png"
|
||||
/>
|
||||
</div>
|
||||
|
||||
For example, with 3 collections, called `docs`, `posts`, and `images`, we could expose the "docs" inside the public schema like this:
|
||||
|
||||
```sql
|
||||
create view public.docs as
|
||||
select
|
||||
id,
|
||||
embedding,
|
||||
metadata, # Expose the metadata as JSON
|
||||
(metadata->>'url')::text as url # Extract the URL as a string
|
||||
from vector
|
||||
```
|
||||
|
||||
You can then use any of the client libraries to access your collections within your applications:
|
||||
|
||||
{/* prettier-ignore */}
|
||||
```js
|
||||
const { data, error } = await supabase
|
||||
.from('docs')
|
||||
.select('id, embedding, metadata')
|
||||
.eq('url', '/hello-world')
|
||||
```
|
||||
|
||||
## Enterprise workloads
|
||||
|
||||
As you move into production, we recommend running splitting your collections into separate projects. This is because it allows your vector stores to scale independently of your production data. Vectors typically grow faster than operational data, and they have different resource requirements. Running them on separate databases removes the single-point-of-failure.
|
||||
|
||||
<div>
|
||||
<img
|
||||
alt="With secondaries"
|
||||
className="dark:hidden"
|
||||
src="/docs/img/ai/scaling/engineering-for-scale--with-secondaries--light.png"
|
||||
/>
|
||||
<img
|
||||
alt="With secondaries"
|
||||
className="hidden dark:block"
|
||||
src="/docs/img/ai/scaling/engineering-for-scale--with-secondaries--dark.png"
|
||||
/>
|
||||
</div>
|
||||
|
||||
You can use as many secondary databases as you need to manage your collections. With this architecture, you have 2 options for accessing collections within your application:
|
||||
|
||||
1. Query the collections directly using Vecs.
|
||||
2. Access the collections from your Primary database through a Wrapper.
|
||||
|
||||
You can use both of these in tandem to suit your use-case. We recommend option `1` wherever possible, as it offers the most scalability.
|
||||
|
||||
### Query collections using Vecs
|
||||
|
||||
Vecs provides methods for querying collections, either using a [cosine similarity function](https://supabase.github.io/vecs/api/#basic) or with [metadata filtering](https://supabase.github.io/vecs/api/#metadata-filtering).
|
||||
|
||||
```python
|
||||
# cosine similarity
|
||||
docs.query(query_vector=[0.4,0.5,0.6], limit=5)
|
||||
|
||||
# metadata filtering
|
||||
docs.query(
|
||||
query_vector=[0.4,0.5,0.6],
|
||||
limit=5,
|
||||
filters={"year": {"$eq": 2012}}, # metadata filters
|
||||
)
|
||||
```
|
||||
|
||||
### Accessing external collections using Wrappers
|
||||
|
||||
Supabase supports [Foreign Data Wrappers](/blog/postgres-foreign-data-wrappers-rust). Wrappers allow you connect two databases together so that you can query them over the network.
|
||||
|
||||
This involves 2 steps: connecting to your remote database from the primary, and creating a Foreign Table.
|
||||
|
||||
#### Connecting your remote database
|
||||
|
||||
Inside your Primary database we need to provide the credentials to access the secondary database:
|
||||
|
||||
```sql
|
||||
create extension postgres_fdw;
|
||||
|
||||
create server docs_server
|
||||
foreign data wrapper postgres_fdw
|
||||
options (host 'db.xxx.supabase.co', port '5432', dbname 'postgres');
|
||||
|
||||
create user mapping for docs_user
|
||||
server docs_server
|
||||
options (user 'postgres', password 'password');
|
||||
```
|
||||
|
||||
#### Create a foreign table
|
||||
|
||||
We can now create a foreign table to access the data in our secondary project.
|
||||
|
||||
```sql
|
||||
create foreign table docs (
|
||||
id text not null,
|
||||
embedding vector(1536),
|
||||
metadata jsonb,
|
||||
url text
|
||||
)
|
||||
server docs_server
|
||||
options (schema_name 'public', table_name 'docs');
|
||||
```
|
||||
|
||||
This looks very similar to our View example above, and you can continue to use the client libraries to access your collections through the foreign table:
|
||||
|
||||
{/* prettier-ignore */}
|
||||
```js
|
||||
const { data, error } = await supabase
|
||||
.from('docs')
|
||||
.select('id, embedding, metadata')
|
||||
.eq('url', '/hello-world')
|
||||
```
|
||||
|
||||
### Enterprise architecture
|
||||
|
||||
This diagram provides an example architecture, allowing you to access the collections either with our client libraries or using Vecs. You can add as many secondary databases as you need, in this example we show one only:
|
||||
|
||||
<div>
|
||||
<img
|
||||
alt="multi database"
|
||||
className="dark:hidden"
|
||||
src="/docs/img/ai/scaling/engineering-for-scale--multi-database--light.png"
|
||||
/>
|
||||
<img
|
||||
alt="multi database"
|
||||
className="hidden dark:block"
|
||||
src="/docs/img/ai/scaling/engineering-for-scale--multi-database--dark.png"
|
||||
/>
|
||||
</div>
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,159 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
import StepHikeCompact from '~/components/StepHikeCompact'
|
||||
|
||||
export const meta = {
|
||||
title: 'Building ChatGPT plugins',
|
||||
subtitle: 'Use Supabase as a Retrieval Store for your ChatGPT plugin.',
|
||||
breadcrumb: 'AI Examples',
|
||||
}
|
||||
|
||||
ChatGPT recently released [Plugins](https://openai.com/blog/chatgpt-plugins) which help ChatGPT access up-to-date information, run computations, or use third-party services.
|
||||
If you're building a plugin for ChatGPT, you'll probably want to answer questions from a specific source. We can solve this with “retrieval plugins”, which allow ChatGPT to access information from a database.
|
||||
|
||||
## What is ChatGPT Retrieval Plugin?
|
||||
|
||||
A [Retrieval Plugin](https://github.com/openai/chatgpt-retrieval-plugin) is a Python project designed to inject external data into a ChatGPT conversation. It does a few things:
|
||||
|
||||
1. Turn documents into smaller chunks.
|
||||
2. Converts chunks into embeddings using OpenAI's `text-embedding-ada-002` model.
|
||||
3. Stores the embeddings into a vector database.
|
||||
4. Queries the vector database for relevant documents when a question is asked.
|
||||
|
||||
It allows ChatGPT to dynamically pull relevant information into conversations from your data sources. This could be PDF documents, Confluence, or Notion knowledge bases.
|
||||
|
||||
## Example: Chat with Postgres Docs
|
||||
|
||||
Let’s build an example where we can “ask ChatGPT questions” about the Postgres documentation. Although ChatGPT already knows about the Postgres documentation because it is publicly available, this is a simple example which demonstrates how to work with PDF files.
|
||||
|
||||
This plugin requires several steps:
|
||||
|
||||
1. Download all the [Postgres docs as a PDF](https://www.postgresql.org/files/documentation/pdf/15/postgresql-15-US.pdf)
|
||||
2. Convert the docs into chunks of embedded text and store them in Supabase
|
||||
3. Run our plugin locally so that we can ask questions about the Postgres docs.
|
||||
|
||||
We'll be saving the Postgres documentation in Postgres, and ChatGPT will be retrieving the documentation whenever a user asks a question:
|
||||
|
||||
<img
|
||||
className="dark:hidden !m-0"
|
||||
alt="diagram reference"
|
||||
src="/docs/img/ai/chatgpt-plugins/chatgpt-plugin-scheme--light.png"
|
||||
/>
|
||||
|
||||
<img
|
||||
className="hidden dark:block !m-0"
|
||||
alt="diagram reference"
|
||||
src="/docs/img/ai/chatgpt-plugins/chatgpt-plugin-scheme--dark.png"
|
||||
/>
|
||||
|
||||
### Step 1: Fork the ChatGPT Retrieval Plugin repository
|
||||
|
||||
Fork the ChatGPT Retrieval Plugin repository to your GitHub account and clone it to your local machine. Read through the `README.md` file to understand the project structure.
|
||||
|
||||
### Step 2: Install dependencies
|
||||
|
||||
Choose your desired datastore provider and remove unused dependencies from `pyproject.toml`. For this example, we'll use Supabase. And install dependencies with Poetry:
|
||||
|
||||
```bash
|
||||
poetry install
|
||||
```
|
||||
|
||||
### Step 3: Create a Supabase project
|
||||
|
||||
Create a [Supabase project](https://supabase.com/dashboard) and database by following the instructions [here](https://supabase.com/docs/guides/platform). Export the environment variables required for the retrieval plugin to work:
|
||||
|
||||
```bash
|
||||
export OPENAI_API_KEY=<open_ai_api_key>
|
||||
export DATASTORE=supabase
|
||||
export SUPABASE_URL=<supabase_url>
|
||||
export SUPABASE_SERVICE_ROLE_KEY=<supabase_key>
|
||||
```
|
||||
|
||||
For Postgres datastore, you'll need to export these environment variables instead:
|
||||
|
||||
```bash
|
||||
export OPENAI_API_KEY=<open_ai_api_key>
|
||||
export DATASTORE=postgres
|
||||
export PG_HOST=<postgres_host_url>
|
||||
export PG_PASSWORD=<postgres_password>
|
||||
```
|
||||
|
||||
### Step 4: Run Postgres Locally
|
||||
|
||||
To start quicker you may use Supabase CLI to spin everything up locally as it already includes pgvector from the start. Install `supabase-cli`, go to the `examples/providers` folder in the repo and run:
|
||||
|
||||
```bash
|
||||
supabase start
|
||||
```
|
||||
|
||||
This will pull all docker images and run supabase stack in docker on your local machine. It will also apply all the necessary migrations to set the whole thing up. You can then use your local setup the same way, just export the environment variables and follow to the next steps.
|
||||
|
||||
Using `supabase-cli` is not required and you can use any other docker image or hosted version of PostgresDB that includes `pgvector`. Just make sure you run migrations from `examples/providers/supabase/migrations/20230414142107_init_pg_vector.sql`.
|
||||
|
||||
### Step 5: Obtain OpenAI API key
|
||||
|
||||
To create embeddings Plugin uses OpenAI API and `text-embedding-ada-002` model. Each time we add some data to our datastore, or try to query relevant information from it, embedding will be created either for inserted data chunk, or for the query itself. To make it work we need to export `OPENAI_API_KEY`. If you already have an account in OpenAI, you just need to go to [User Settings - API keys](https://platform.openai.com/account/api-keys) and Create new secret key.
|
||||
|
||||

|
||||
|
||||
### Step 6: Run the plugin
|
||||
|
||||
Execute the following command to run the plugin:
|
||||
|
||||
```bash
|
||||
poetry run dev
|
||||
# output
|
||||
INFO: Will watch for changes in these directories: ['./chatgpt-retrieval-plugin']
|
||||
INFO: Uvicorn running on http://localhost:3333 (Press CTRL+C to quit)
|
||||
INFO: Started reloader process [87843] using WatchFiles
|
||||
INFO: Started server process [87849]
|
||||
INFO: Waiting for application startup.
|
||||
INFO: Application startup complete.
|
||||
```
|
||||
|
||||
The plugin will start on your localhost - port `:3333` by default.
|
||||
|
||||
### Step 6: Populating data in the datastore
|
||||
|
||||
For this example, we'll upload Postgres documentation to the datastore. Download the [Postgres documentation](https://www.postgresql.org/files/documentation/pdf/15/postgresql-15-US.pdf) and use the `/upsert-file` endpoint to upload it:
|
||||
|
||||
```bash
|
||||
curl -X POST -F \\"file=@./postgresql-15-US.pdf\\" <http://localhost:3333/upsert-file>
|
||||
```
|
||||
|
||||
The plugin will split your data and documents into smaller chunks automatically. You can view the chunks using the Supabase dashboard or any other SQL client you prefer. For the whole Postgres Documentation I got 7,904 records in my documents table, which is not a lot, but we can try to add index for `embedding` column to speed things up by a little. To do so, you should run the following SQL command:
|
||||
|
||||
```sql
|
||||
create index on documents
|
||||
using ivfflat (embedding vector_ip_ops)
|
||||
with (lists = 10);
|
||||
```
|
||||
|
||||
This will create an index for the inner product distance function. Important to note that it is an approximate index. It will change the logic from performing the exact nearest neighbor search to the approximate nearest neighbor search.
|
||||
|
||||
We are using `lists = 10`, because as a general guideline, you should start looking for optimal lists constant value with the formula: `rows / 1000` when you have less than 1 million records in your table.
|
||||
|
||||
### Step 7: Using our plugin within ChatGPT
|
||||
|
||||
To integrate our plugin with ChatGPT, register it in the ChatGPT dashboard. Assuming you have access to ChatGPT Plugins and plugin development, select the Plugins model in a new chat, then choose "Plugin store" and "Develop your own plugin." Enter `localhost:3333` into the domain input, and your plugin is now part of ChatGPT.
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
You can now ask questions about Postgres and receive answers derived from the documentation.
|
||||
|
||||
Let's try it out: ask ChatGPT to find out when to use `check` and when to use `using`. You will be able to see what queries were sent to our plugin and what it responded to.
|
||||
|
||||

|
||||
|
||||
And after ChatGPT receives a response from the plugin it will answer your question with the data from the documentation.
|
||||
|
||||

|
||||
|
||||
## Resources
|
||||
|
||||
- ChatGPT Retrieval Plugin: [github.com/openai/chatgpt-retrieval-plugin](https://github.com/openai/chatgpt-retrieval-plugin)
|
||||
- ChatGTP Plugins: [official documentation](https://platform.openai.com/docs/plugins/introduction)
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
export default Page
|
||||
@@ -0,0 +1,124 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
import StepHikeCompact from '~/components/StepHikeCompact'
|
||||
|
||||
export const meta = {
|
||||
title: 'Adding generative Q&A for your documentation',
|
||||
subtitle:
|
||||
'Learn how to build a ChatGPT-style doc search powered using our headless search toolkit.',
|
||||
breadcrumb: 'AI Examples',
|
||||
}
|
||||
|
||||
Supabase provides a [Headless Search Toolkit](https://github.com/supabase/headless-vector-search) for adding "Generative Q&A" to your documentation. The toolkit is "headless", so that you can integrate it into your existing website and style it to match your website theme.
|
||||
|
||||
You can see how this works with the Supabase docs. Just him `cmd+k` and "ask" for something like "what are the features of supabase?". You will see that the response is streamed back, using the information provided in the docs:
|
||||
|
||||

|
||||
|
||||
## Tech stack
|
||||
|
||||
- Supabase: Database & Edge Functions.
|
||||
- OpenAI: Embeddings and completions.
|
||||
- GitHub Actions: for ingesting your markdown docs.
|
||||
|
||||
## Toolkit
|
||||
|
||||
This toolkit consists of 2 parts:
|
||||
|
||||
- The [Headless Vector Search](https://github.com/supabase/headless-vector-search) template which you can deploy in your own organization.
|
||||
- A [GitHub Action](https://github.com/supabase/embeddings-generator) which will ingest your markdown files, convert them to embeddings, and store them in your database.
|
||||
|
||||
## Usage
|
||||
|
||||
There are 3 steps to build similarity search inside your documentation:
|
||||
|
||||
1. Prepare your database.
|
||||
2. Ingest your documentation.
|
||||
3. Add a search interface.
|
||||
|
||||
### Prepare your database
|
||||
|
||||
To prepare, create a [new Supabase project](https://database.new) and store the database and API credentials, which you can find in the project [settings](https://app.supabase.com/_/settings).
|
||||
|
||||
Now we can use the [Headless Vector Search](https://github.com/supabase/headless-vector-search#set-up) instructions to set up the database:
|
||||
|
||||
1. Clone the repo to your local machine: `git clone git@github.com:supabase/headless-vector-search.git`
|
||||
2. Link the repo to your remote project: `supabase link --project-ref XXX`
|
||||
3. Apply the database migrations: `supabase db push`
|
||||
4. Set your OpenAI key as a secret: `supabase secrets set OPENAI_KEY=sk-xxx`
|
||||
5. Deploy the Edge Functions: `supabase functions deploy --no-verify-jwt`
|
||||
6. Expose `docs` schema via API in Supabase Dashboard [settings](https://app.supabase.com/project/_/settings/api) > `API Settings` > `Exposed schemas`
|
||||
|
||||
### Ingest your documentation
|
||||
|
||||
Now we need to push your documentation into the database as embeddings. You can do this manually, but to make it easier we've created a [GitHub Action](https://github.com/marketplace/actions/supabase-embeddings-generator) which can update your database every time there is a Pull Request.
|
||||
|
||||
In your knowledge base repository, create a new action called `.github/workflows/generate_embeddings.yml` with the following content:
|
||||
|
||||
```yml
|
||||
name: 'generate_embeddings'
|
||||
on: # run on main branch changes
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
|
||||
jobs:
|
||||
generate:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
- uses: supabase/supabase-embeddings-generator@v0.0.x # Update this to the latest version.
|
||||
with:
|
||||
supabase-url: 'https://your-project-ref.supabase.co' # Update this to your project URL.
|
||||
supabase-service-role-key: ${{ secrets.SUPABASE_SERVICE_ROLE_KEY }}
|
||||
openai-key: ${{ secrets.OPENAI_KEY }}
|
||||
docs-root-path: 'docs' # the path to the root of your md(x) files
|
||||
```
|
||||
|
||||
Make sure to choose the latest version, and set your `SUPABASE_SERVICE_ROLE_KEY` and `OPENAI_KEY` as repository secrets in your repo settings (settings > secrets > actions).
|
||||
|
||||
### Add a search interface
|
||||
|
||||
Now inside your docs, you need to create a search interface. Because this is a headless interface, you can use it with any language. The only requirement is that you send the user query to the `query` Edge Function, which will stream an answer back from OpenAI. It might look something like this:
|
||||
|
||||
```js
|
||||
const onSubmit = (e: Event) => {
|
||||
e.preventDefault()
|
||||
answer.value = ""
|
||||
isLoading.value = true
|
||||
|
||||
const query = new URLSearchParams({ query: inputRef.current!.value })
|
||||
const projectUrl = `https://your-project-ref.functions.supabase.co`
|
||||
const queryURL = `${projectURL}/${query}`
|
||||
const eventSource = new EventSource(queryURL)
|
||||
|
||||
eventSource.addEventListener("error", (err) => {
|
||||
isLoading.value = false
|
||||
console.error(err)
|
||||
})
|
||||
|
||||
eventSource.addEventListener("message", (e: MessageEvent) => {
|
||||
isLoading.value = false
|
||||
|
||||
if (e.data === "[DONE]") {
|
||||
eventSource.close()
|
||||
return
|
||||
}
|
||||
|
||||
const completionResponse: CreateCompletionResponse = JSON.parse(e.data)
|
||||
const text = completionResponse.choices[0].text
|
||||
|
||||
answer.value += text
|
||||
});
|
||||
|
||||
isLoading.value = true
|
||||
}
|
||||
```
|
||||
|
||||
## Resources
|
||||
|
||||
- Read about how we built [ChatGPT for the Supabase Docs](https://supabase.com/blog/chatgpt-supabase-docs).
|
||||
- Read the pgvector Docs for [Embeddings and vector similarity](/docs/guides/database/extensions/pgvector)
|
||||
- See how to build something like this from scratch [using Next.js](/docs/guides/ai/examples/nextjs-vector-search).
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
export default Page
|
||||
+7
-12
@@ -1,28 +1,23 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
title: 'Hugging Face',
|
||||
title: 'Generate image captions using Hugging Face',
|
||||
description:
|
||||
'Use the Hugging Face Inference API to make calls to 100,000+ Machine Learning models from Supabase Edge Functions.',
|
||||
subtitle:
|
||||
'Use the Hugging Face Inference API to make calls to 100,000+ Machine Learning models from Supabase Edge Functions.',
|
||||
video: 'https://www.youtube.com/v/OgnYxRkxEUw',
|
||||
tocVideo: 'OgnYxRkxEUw',
|
||||
}
|
||||
|
||||
We can combine Hugging Face with [Supabase Storage](https://supabase.com/storage) and [Database Webhooks](https://supabase.com/docs/guides/database/webhooks) to automatically caption for any image we upload to a storage bucket.
|
||||
|
||||
## About Hugging Face
|
||||
|
||||
[Hugging Face](https://huggingface.co/) is the collaboration platform for the machine learning community.
|
||||
|
||||
[Huggingface.js](https://huggingface.co/docs/huggingface.js/index) provides a convenient way to make calls to 100,000+ Machine Learning models, making it easy to incorporate AI functionality into your [Supabase Edge Functions](https://supabase.com/edge-functions).
|
||||
|
||||
Putting this together with [Supabase Storage](https://supabase.com/storage) and [Database Webhooks](https://supabase.com/docs/guides/database/webhooks) we can easily put together a service that automatically generates captions for any image we upload to a storage bucket.
|
||||
|
||||
<div class="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/OgnYxRkxEUw"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
## Setup
|
||||
|
||||
- Open your Supabase project dashboard or [create a new project](https://app.supabase.com/projects).
|
||||
@@ -0,0 +1,177 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'examples-image-search-python',
|
||||
title: 'Image Search with OpenAI CLIP',
|
||||
description: 'Implement image search with the OpenAI CLIP Model and Supabase Vector.',
|
||||
subtitle: 'Implement image search with the OpenAI CLIP Model and Supabase Vector.',
|
||||
}
|
||||
|
||||
The [OpenAI CLIP Model](https://github.com/openai/CLIP) was trained on a variety of (image, text)-pairs. You can use the CLIP model for:
|
||||
|
||||
- Text-to-Image / Image-To-Text / Image-to-Image / Text-to-Text Search
|
||||
- You can fine-tune it on your own image and text data with the regular SentenceTransformers training code.
|
||||
|
||||
[SentenceTransformers](https://www.sbert.net/examples/applications/image-search/README.html) provides models that allow you to embed images and text into the same vector space. You can use this to find similar images as well as to implement image search.
|
||||
|
||||
You can find the full application code as a Python Poetry project on [GitHub](https://github.com/supabase/supabase/tree/master/examples/ai/image_search#image-search-with-supabase-vector).
|
||||
|
||||
## Create a new Python Project with Poetry
|
||||
|
||||
[Poetry](https://python-poetry.org/) provides packaging and dependency management for Python. If you haven't already, install poetry via pip:
|
||||
|
||||
```shell
|
||||
pip install poetry
|
||||
```
|
||||
|
||||
Then initialize a new project:
|
||||
|
||||
```shell
|
||||
poetry new image-search
|
||||
```
|
||||
|
||||
## Setup Supabase project
|
||||
|
||||
If you haven't already, [install the Supabase CLI](/docs/guides/cli), then initialize Supabase in the root of your newly created poetry project:
|
||||
|
||||
```shell
|
||||
supabase init
|
||||
```
|
||||
|
||||
Next, start your local Supabase stack:
|
||||
|
||||
```shell
|
||||
supabase start
|
||||
```
|
||||
|
||||
This will start up the Supabase stack locally and print out a bunch of environtment details, including your local `DB URL`. Make a note of that for later user.
|
||||
|
||||
## Install the Dependencies
|
||||
|
||||
We will need to add the following dependencies to our project:
|
||||
|
||||
- [`vecs`](https://github.com/supabase/vecs#vecs): Supabase Vector Python Client.
|
||||
- [`sentence-transformers`](https://huggingface.co/sentence-transformers/clip-ViT-B-32): a framework for sentence, text and image embeddings (used with OpenAI CLIP model)
|
||||
- [`matplotlib`](https://matplotlib.org/): for displaying our image result
|
||||
|
||||
```shell
|
||||
poetry add vecs sentence-transformers matplotlib
|
||||
```
|
||||
|
||||
## Import the necessary dependencies
|
||||
|
||||
At the top of your main python script, import the dependencies and store your `DB URL` from above in a variable:
|
||||
|
||||
```python
|
||||
from PIL import Image
|
||||
from sentence_transformers import SentenceTransformer
|
||||
import vecs
|
||||
from matplotlib import pyplot as plt
|
||||
from matplotlib import image as mpimg
|
||||
|
||||
DB_CONNECTION = "postgresql://postgres:postgres@localhost:54322/postgres"
|
||||
```
|
||||
|
||||
## Create embeddings for your images
|
||||
|
||||
In the root of your project, create a new folder called `images` and add some images. You can use the images from the example project on [GitHub](https://github.com/supabase/supabase/tree/master/examples/ai/image_search/images) or you can find license free images on [unsplash](https://unsplash.com).
|
||||
|
||||
Next, create a `seed` method, which will create a new Supabase Vector Collection, generate embeddings for your images, and upsert the embeddings into your database:
|
||||
|
||||
```python
|
||||
def seed():
|
||||
# create vector store client
|
||||
vx = vecs.create_client(DB_CONNECTION)
|
||||
|
||||
# create a collection of vectors with 3 dimensions
|
||||
images = vx.create_collection(name="image_vectors", dimension=512)
|
||||
|
||||
# Load CLIP model
|
||||
model = SentenceTransformer('clip-ViT-B-32')
|
||||
|
||||
# Encode an image:
|
||||
img_emb1 = model.encode(Image.open('./images/one.jpg'))
|
||||
img_emb2 = model.encode(Image.open('./images/two.jpg'))
|
||||
img_emb3 = model.encode(Image.open('./images/three.jpg'))
|
||||
img_emb4 = model.encode(Image.open('./images/four.jpg'))
|
||||
|
||||
# add records to the *images* collection
|
||||
images.upsert(
|
||||
vectors=[
|
||||
(
|
||||
"one.jpg", # the vector's identifier
|
||||
img_emb1, # the vector. list or np.array
|
||||
{"type": "jpg"} # associated metadata
|
||||
), (
|
||||
"two.jpg",
|
||||
img_emb2,
|
||||
{"type": "jpg"}
|
||||
), (
|
||||
"three.jpg",
|
||||
img_emb3,
|
||||
{"type": "jpg"}
|
||||
), (
|
||||
"four.jpg",
|
||||
img_emb4,
|
||||
{"type": "jpg"}
|
||||
)
|
||||
]
|
||||
)
|
||||
print("Inserted images")
|
||||
|
||||
# index the collection for fast search performance
|
||||
images.create_index()
|
||||
print("Created index")
|
||||
```
|
||||
|
||||
Add this method as a script in your `pyproject.toml` file:
|
||||
|
||||
```toml
|
||||
[tool.poetry.scripts]
|
||||
seed = "image_search.main:seed"
|
||||
search = "image_search.main:search"
|
||||
```
|
||||
|
||||
After activating the virtual environtment with `poetry shell` you can now run your seed script via `poetry run seed`. You can inspect the generated embeddings in your local database by visiting the local Supabase dashboard at [localhost:54323](http://localhost:54323/project/default/editor), selecting the `vecs` schema, and the `image_vectors` database.
|
||||
|
||||
## Perform an Image Search from a Text Query
|
||||
|
||||
With Supabase Vector we can easily query our embeddings. We can use either an image as search input or alternative we can generate an embedding from a string input and use that as the query input:
|
||||
|
||||
```python
|
||||
def search():
|
||||
# create vector store client
|
||||
vx = vecs.create_client(DB_CONNECTION)
|
||||
images = vx.get_collection(name="image_vectors")
|
||||
|
||||
# Load CLIP model
|
||||
model = SentenceTransformer('clip-ViT-B-32')
|
||||
# Encode text query
|
||||
query_string = "a bike in front of a red brick wall"
|
||||
text_emb = model.encode(query_string)
|
||||
|
||||
# query the collection filtering metadata for "type" = "jpg"
|
||||
results = images.query(
|
||||
query_vector=text_emb, # required
|
||||
limit=1, # number of records to return
|
||||
filters={"type": {"$eq": "jpg"}}, # metadata filters
|
||||
)
|
||||
result = results[0]
|
||||
print(result)
|
||||
plt.title(result)
|
||||
image = mpimg.imread('./images/' + result)
|
||||
plt.imshow(image)
|
||||
plt.show()
|
||||
```
|
||||
|
||||
By limiting the query to one result, we can show the most relevant image to the user. Finally we use `matplotlib` to show the image result to the user.
|
||||
|
||||
That's it, go ahead and test it out by running `poetry run search` and you will be presented with an image of a "bike in front of a red brick wall".
|
||||
|
||||
## Conclusion
|
||||
|
||||
With just a couple of lines of Python you are able to implement image search as well as reverse image search using OpenAI's CLIP model and Supabase Vector.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
+10
-20
@@ -2,33 +2,23 @@ import Layout from '~/layouts/DefaultGuideLayout'
|
||||
import StepHikeCompact from '~/components/StepHikeCompact'
|
||||
|
||||
export const meta = {
|
||||
title: 'OpenAI Embeddings & Vector Search',
|
||||
title: 'Vector search with Next.js and OpenAI',
|
||||
subtitle:
|
||||
'Learn how to build a ChatGPT-style doc search powered by Next.js, OpenAI, and Supabase.',
|
||||
breadcrumb: 'OpenAI',
|
||||
breadcrumb: 'AI Examples',
|
||||
video: 'https://www.youtube.com/v/xmfNUCjszh4',
|
||||
tocVideo: 'xmfNUCjszh4',
|
||||
}
|
||||
|
||||
In this tutorial we'll look at how you can build a custom ChatGPT-like search experience for your own knowledge base. See our [Supabase Clippy](https://supabase.com/blog/chatgpt-supabase-docs) blog post for an example of how this will look.
|
||||
While our [Headless Vector search](/docs/guides/ai/examples/headless-vector-search) provides a toolkit for generative Q&A, in this tutorial we'll go more in-depth, build a custom ChatGPT-like search experience from the ground-up using Next.js. You will:
|
||||
|
||||
We assume that you have a Next.js project with a collection of `.mdx` files nested inside your `pages` directory. We will start developing locally with the Supabase CLI and then push our local database changes to our hosted Supabase project.
|
||||
1. Convert your markdown into embeddings using OpenAI.
|
||||
2. Store you embeddings in Postgres using pgvector.
|
||||
3. Deploy a function for answering your users' questions.
|
||||
|
||||
## Video Guide
|
||||
You can read our [Supabase Clippy](https://supabase.com/blog/chatgpt-supabase-docs) blog post for a full example.
|
||||
|
||||
<div class="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/xmfNUCjszh4"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
<Admonition type="note">
|
||||
You can find the [full example on
|
||||
GitHub](https://github.com/supabase-community/nextjs-openai-doc-search).
|
||||
</Admonition>
|
||||
We assume that you have a Next.js project with a collection of `.mdx` files nested inside your `pages` directory. We will start developing locally with the Supabase CLI and then push our local database changes to our hosted Supabase project. You can find the [full Next.js example on GitHub](https://github.com/supabase-community/nextjs-openai-doc-search).
|
||||
|
||||
## Create a project
|
||||
|
||||
@@ -294,7 +284,7 @@ With our database set up, we need to process and store all `.mdx` files in the `
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||
```txt
|
||||
```bash
|
||||
NEXT_PUBLIC_SUPABASE_URL=
|
||||
NEXT_PUBLIC_SUPABASE_ANON_KEY=
|
||||
SUPABASE_SERVICE_ROLE_KEY=
|
||||
@@ -553,5 +543,5 @@ Want to learn more about the awesome tech that is powering this?
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} hideToc={true} />
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
export default Page
|
||||
+46
-11
@@ -3,20 +3,35 @@ import Layout from '~/layouts/DefaultGuideLayout'
|
||||
export const meta = {
|
||||
id: 'examples-openai',
|
||||
title: 'Generating OpenAI GPT3 completions',
|
||||
description: 'Using OpenAI in Edge Functions.',
|
||||
description: 'Generate GPT text completions using OpenAI and Supabase Edge Functions.',
|
||||
subtitle: 'Generate GPT text completions using OpenAI and Supabase Edge Functions.',
|
||||
video: 'https://www.youtube.com/v/29p8kIqyU_Y',
|
||||
tocVideo: '29p8kIqyU_Y',
|
||||
}
|
||||
|
||||
<div class="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/29p8kIqyU_Y"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
OpenAI provides a [completions API](https://platform.openai.com/docs/api-reference/completions) that allows you to use their generative GPT models in your own applications.
|
||||
|
||||
Use the [OpenAI completions API](https://platform.openai.com/docs/api-reference/completions) in Supabase Edge Functions.
|
||||
OpenAI's API is intended to be used from the server-side. Supabase offers Edge Functions to make it easy to interact with third party APIs like OpenAI.
|
||||
|
||||
## Setup Supabase project
|
||||
|
||||
If you haven't already, [install the Supabase CLI](/docs/guides/cli) and initialize your project:
|
||||
|
||||
```shell
|
||||
supabase init
|
||||
```
|
||||
|
||||
## Create edge function
|
||||
|
||||
Scaffold a new edge function called `openai` by running:
|
||||
|
||||
```shell
|
||||
supabase functions new openai
|
||||
```
|
||||
|
||||
A new edge function will now exist under `./supabase/functions/openai/index.ts`.
|
||||
|
||||
We'll design the function to take your user's query (via POST request) and forward it to OpenAI's API.
|
||||
|
||||
```ts index.ts
|
||||
import 'xhr_polyfill'
|
||||
@@ -31,7 +46,7 @@ serve(async (req) => {
|
||||
prompt: query,
|
||||
max_tokens: 256,
|
||||
temperature: 0,
|
||||
stream: true,
|
||||
stream: false,
|
||||
}
|
||||
|
||||
return fetch('https://api.openai.com/v1/completions', {
|
||||
@@ -45,12 +60,28 @@ serve(async (req) => {
|
||||
})
|
||||
```
|
||||
|
||||
Note that we are setting `stream` to `false` which will wait until the entire response is complete before returning. If you wish to stream GPT's response word-by-word back to your client, set `stream` to `true`.
|
||||
|
||||
## Create OpenAI key
|
||||
|
||||
You may have noticed we were passing `OPENAI_API_KEY` in the Authorization header to OpenAI. To generate this key, go to https://platform.openai.com/account/api-keys and create a new secret key.
|
||||
|
||||
After getting the key, copy it into a new file called `.env.local` in your `./supabase` folder:
|
||||
|
||||
```
|
||||
OPENAI_API_KEY=your-key-here
|
||||
```
|
||||
|
||||
## Run locally
|
||||
|
||||
Serve the edge function locally by running:
|
||||
|
||||
```bash
|
||||
supabase functions serve --env-file ./supabase/.env.local --no-verify-jwt
|
||||
```
|
||||
|
||||
Notice how we are passing in the `.env.local` file.
|
||||
|
||||
Use cURL or Postman to make a POST request to http://localhost:54321/functions/v1/openai.
|
||||
|
||||
```bash
|
||||
@@ -59,8 +90,12 @@ curl -i --location --request POST http://localhost:54321/functions/v1/openai \
|
||||
--data '{"query":"What is Supabase?"}'
|
||||
```
|
||||
|
||||
You should see a GPT response come back from OpenAI!
|
||||
|
||||
## Deploy
|
||||
|
||||
Deploy your function to the cloud by runnning:
|
||||
|
||||
```bash
|
||||
supabase functions deploy --no-verify-jwt openai
|
||||
supabase secrets set --env-file ./supabase/.env.local
|
||||
@@ -0,0 +1,119 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-google-colab',
|
||||
title: 'Google Colab',
|
||||
description: 'Use Google Colab to manage your Supabase Vector store.',
|
||||
subtitle: 'Use Google Colab to manage your Supabase Vector store.',
|
||||
sidebar_label: 'Google Colab',
|
||||
}
|
||||
|
||||
<a
|
||||
className="w-64"
|
||||
href="https://colab.research.google.com/github/supabase/supabase/blob/master/examples/ai/vector_hello_world.ipynb"
|
||||
>
|
||||
<img src="/docs/img/ai/colab-badge.svg" />
|
||||
</a>
|
||||
|
||||
Google Colab is a hosted Jupyter Notebook service. It provides free access to computing resources, including GPUs and TPUs, and is well-suited to machine learning, data science, and education. We can use Colab to manage collections using [Supabase Vecs](/docs/guides/ai/vecs-python-client).
|
||||
|
||||
In this tutorial we'll connect to a database running on the Supabase [platform](https://app.supabase.com/). If you don't already have a database, you can create one here: [database.new](https://database.new).
|
||||
|
||||
## Create a new notebook
|
||||
|
||||
Start by visiting [colab.research.google.com](https://colab.research.google.com/). There you can create a new notebook.
|
||||
|
||||

|
||||
|
||||
## Install Vecs
|
||||
|
||||
We'll use the Supabase Vector client, [Vecs](/docs/guides/ai/vecs-python-client), to manage our collections.
|
||||
|
||||
At the top of the notebook add the notebook paste the following code and hit the "execute" button (`ctrl+enter`):
|
||||
|
||||
```py
|
||||
pip install vecs
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Connect to your database
|
||||
|
||||
Find the Postgres connection string for your Supabase project in the [database settings](https://app.supabase.com/_/settings/database) of the dashboard. Copy the "URI" format, which should look something like `postgresql:/postgres:<password>@<host>:5432/postgres`
|
||||
|
||||
Create a new code block below the install block (`ctrl+m b`) and add the following code using the Postgres URI you copied above:
|
||||
|
||||
```py
|
||||
import vecs
|
||||
|
||||
DB_CONNECTION = "postgresql://postgres:<password>@<host>:5432/postgres"
|
||||
|
||||
# create vector store client
|
||||
vx = vecs.create_client(DB_CONNECTION)
|
||||
```
|
||||
|
||||
Execute the code block (`ctrl+enter`). If no errors were returned then your connection was successful.
|
||||
|
||||
## Create a collection
|
||||
|
||||
Now we're going to create a new collection and insert some documents.
|
||||
|
||||
Create a new code block below the install block (`ctrl+m b`). Add the following code to the code block and execute it (`ctrl+enter`):
|
||||
|
||||
```py
|
||||
collection = vx.create_collection(name="colab_collection", dimension=3)
|
||||
|
||||
collection.upsert(
|
||||
vectors=[
|
||||
(
|
||||
"vec0", # the vector's identifier
|
||||
[0.1, 0.2, 0.3], # the vector. list or np.array
|
||||
{"year": 1973} # associated metadata
|
||||
),
|
||||
(
|
||||
"vec1",
|
||||
[0.7, 0.8, 0.9],
|
||||
{"year": 2012}
|
||||
)
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
This will create a table inside your database within the `vecs` schema, called `colab_collection`. You can view the inserted items in the [Table Editor](https://app.supabase.com/project/_/editor/), by selecting the `vecs` schema from the schema dropdown.
|
||||
|
||||

|
||||
|
||||
## Query your documents
|
||||
|
||||
Now we can search for documents based on their similarity. Create a new code block and execute the following code:
|
||||
|
||||
```py
|
||||
collection.query(
|
||||
query_vector=[0.4,0.5,0.6], # required
|
||||
limit=5, # number of records to return
|
||||
filters={}, # metadata filters
|
||||
measure="cosine_distance", # distance measure to use
|
||||
include_value=False, # should distance measure values be returned?
|
||||
include_metadata=False, # should record metadata be returned?
|
||||
)
|
||||
```
|
||||
|
||||
You will see that this returns two documents in an array `['vec1', 'vec0']`:
|
||||
|
||||

|
||||
|
||||
It also returns a warning:
|
||||
|
||||
```
|
||||
Query does not have a covering index for cosine_distance.
|
||||
```
|
||||
|
||||
You can lean more about creating indexes in the [Vecs documentation](https://supabase.github.io/vecs/api/#create-an-index).
|
||||
|
||||
## Resources
|
||||
|
||||
- Vecs API: [supabase.github.io/vecs/api](https://supabase.github.io/vecs/api)
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,172 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-hugging-face',
|
||||
title: 'Hugging Face',
|
||||
description: 'Learn how to integrate hugging face models with Supabase',
|
||||
sidebar_label: 'Hugging Face',
|
||||
}
|
||||
|
||||
[Hugging Face](https://huggingface.co) is an open source hub for AI/ML models and tools. With over 100,000 machine learning models available, Hugging Face provides a great way to integrate specialized AI & ML tasks into your application.
|
||||
|
||||
Hugging Face exposes an [Inference API](https://huggingface.co/inference-api) you can use to execute AI tasks remotely on Hugging Face servers. This opens the doors to using Hugging Face with languages like TypeScript and can be deployed using [Edge Functions](/docs/guides/functions).
|
||||
|
||||
## AI Tasks
|
||||
|
||||
Below are some of the types of tasks you can perform with Hugging Face:
|
||||
|
||||
### Natural language
|
||||
|
||||
- [Summarization](https://huggingface.co/tasks/summarization)
|
||||
- [Text classification](https://huggingface.co/tasks/text-classification)
|
||||
- [Text generation](https://huggingface.co/tasks/text-generation)
|
||||
- [Translation](https://huggingface.co/tasks/translation)
|
||||
- [Fill in the blank](https://huggingface.co/tasks/fill-mask)
|
||||
|
||||
### Computer Vision
|
||||
|
||||
- [Image to text](https://huggingface.co/tasks/image-to-text)
|
||||
- [Text to image](https://huggingface.co/tasks/text-to-image)
|
||||
- [Image classification](https://huggingface.co/tasks/image-classification)
|
||||
- [Video classification](https://huggingface.co/tasks/video-classification)
|
||||
- [Object detection](https://huggingface.co/tasks/object-detection)
|
||||
- [Image segmentation](https://huggingface.co/tasks/image-segmentation)
|
||||
|
||||
### Audio
|
||||
|
||||
- [Text to speech](https://huggingface.co/tasks/text-to-speech)
|
||||
- [Speech to text](https://huggingface.co/tasks/automatic-speech-recognition)
|
||||
- [Audio classification](https://huggingface.co/tasks/audio-classification)
|
||||
|
||||
See a [full list of tasks](https://huggingface.co/tasks).
|
||||
|
||||
## Access token
|
||||
|
||||
First generate a Hugging Face access token for your app:
|
||||
|
||||
https://huggingface.co/settings/tokens
|
||||
|
||||
Name your token based on the app its being used for and the environment. For example, if you are building an image generation app you might create 2 tokens:
|
||||
|
||||
- "My Image Generator (Dev)"
|
||||
- "My Image Generator (Prod)"
|
||||
|
||||
Since we will be using this token for the inference API, choose the `read` role.
|
||||
|
||||
<Admonition type="info">
|
||||
|
||||
Though it is possible to use the Hugging Face inference API today without an access token, [you may be rate limited](https://huggingface.co/docs/huggingface.js/inference/README#usage).
|
||||
|
||||
To ensure you don't experience any unexpected downtime or errors, we recommend creating an access token.
|
||||
|
||||
</Admonition>
|
||||
|
||||
## Edge Functions
|
||||
|
||||
Edge Functions are server-side TypeScript functions that run on-demand. Since Edge Functions run on a server, you can safely give them access to your Hugging Face access token.
|
||||
|
||||
<Admonition type="info">
|
||||
|
||||
You will need the `supabase` CLI [installed](/docs/guides/cli) for the following commands to work.
|
||||
|
||||
</Admonition>
|
||||
|
||||
To create a new Edge Function, navigate to your local project and initialize Supabase if you haven't already:
|
||||
|
||||
```shell
|
||||
supabase init
|
||||
```
|
||||
|
||||
Then create an Edge Function:
|
||||
|
||||
```shell
|
||||
supabase functions new text-to-image
|
||||
```
|
||||
|
||||
Create a file called `.env.local` to store your Hugging Face access token:
|
||||
|
||||
```shell
|
||||
HUGGING_FACE_ACCESS_TOKEN=<your-token-here>
|
||||
```
|
||||
|
||||
Let's modify the Edge Function to import Hugging Face's inference client and perform a `text-to-image` request:
|
||||
|
||||
```ts
|
||||
import { serve } from 'https://deno.land/std@0.168.0/http/server.ts'
|
||||
import { HfInference } from 'https://esm.sh/@huggingface/inference@2.3.2'
|
||||
|
||||
const hf = new HfInference(Deno.env.get('HUGGING_FACE_ACCESS_TOKEN'))
|
||||
|
||||
serve(async (req) => {
|
||||
const { prompt } = await req.json()
|
||||
|
||||
const image = await hf.textToImage(
|
||||
{
|
||||
inputs: prompt,
|
||||
model: 'stabilityai/stable-diffusion-2',
|
||||
},
|
||||
{
|
||||
use_cache: false,
|
||||
}
|
||||
)
|
||||
|
||||
return new Response(image)
|
||||
})
|
||||
```
|
||||
|
||||
1. This function creates a new instance of `HfInference` using the `HUGGING_FACE_ACCESS_TOKEN` environment variable.
|
||||
|
||||
1. It expects a POST request that includes a JSON request body. The JSON body should include a parameter called `prompt` that represents the text-to-image prompt that we will pass to Hugging Face's inference API.
|
||||
|
||||
1. Next we call `textToImage()`, passing in the user's prompt along with the model that we would like to use for the image generation. Today Hugging Face recommends `stabilityai/stable-diffusion-2`, but you can change this to any other text-to-image model. You can see a list of which models are supported for each task by navigating to their [models page](https://huggingface.co/models?pipeline_tag=text-to-image) and filtering by task.
|
||||
|
||||
1. We set `use_cache` to `false` so that repeat queries with the same prompt will produce new images. If the task and model you are using is deterministic (will always produce the same result based on the same input), consider setting `use_cache` to `true` for faster responses.
|
||||
|
||||
1. The `image` result returned from the API will be a `Blob`. We can pass the `Blob` directly into a `new Response()` which will automatically set the content type and body of the response from the `image`.
|
||||
|
||||
Finally let's serve the Edge Function locally to test it:
|
||||
|
||||
```shell
|
||||
supabase functions serve --env-file .env.local --no-verify-jwt
|
||||
```
|
||||
|
||||
Remember to pass in the `.env.local` file using the `--env-file` parameter so that the Edge Function can access the `HUGGING_FACE_ACCESS_TOKEN`.
|
||||
|
||||
<Admonition type="info">
|
||||
|
||||
For demo purposes we set `--no-verify-jwt` to make it easy to test the Edge Function without passing in a JWT token. In a real application you will need to pass the JWT as a `Bearer` token in the `Authorization` header.
|
||||
|
||||
</Admonition>
|
||||
|
||||
At this point, you can make an API request to your Edge Function using your preferred frontend framework (Next.js, React, Expo, etc). We can also test from the terminal using `curl`:
|
||||
|
||||
```shell
|
||||
curl --output result.jpg --location --request POST 'http://localhost:54321/functions/v1/text-to-image' \
|
||||
--header 'Content-Type: application/json' \
|
||||
--data '{"query":"Llama wearing sunglasses"}'
|
||||
```
|
||||
|
||||
In this example, your generated image will save to `result.jpg`:
|
||||
|
||||
<img
|
||||
src="/docs/img/ai/hugging-face/llama-sunglasses-example.png"
|
||||
alt="Llama wearing sunglasses example"
|
||||
width="400"
|
||||
height="400"
|
||||
/>
|
||||
|
||||
## Next steps
|
||||
|
||||
You can now create an Edge Function that invokes a Hugging Face task using your model of choice.
|
||||
|
||||
Try running some other [AI tasks](#ai-tasks).
|
||||
|
||||
## Resources
|
||||
|
||||
- Official [Hugging Face site](https://huggingface.co/).
|
||||
- Official [Hugging Face JS docs](https://huggingface.co/docs/huggingface.js).
|
||||
- [Generate image captions](/docs/guides/ai/examples/huggingface-image-captioning) using Hugging Face.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,66 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-integration-llamaindex',
|
||||
title:
|
||||
'Learn how to integrate Supabase with LlamaIndex, a data framework for your LLM applications.',
|
||||
subtitle:
|
||||
'Learn how to integrate Supabase with LlamaIndex, a data framework for your LLM applications.',
|
||||
breadcrumb: 'AI Integrations',
|
||||
}
|
||||
|
||||
This guide will walk you through a basic example using the LlamaIndex [SupabaseVectorStore](https://github.com/supabase/supabase/blob/master/examples/ai/llamaindex/llamaindex.ipynb).
|
||||
|
||||
<DatabaseSetup />
|
||||
|
||||
## Launching a notebook
|
||||
|
||||
Launch our [LlamaIndex](https://github.com/supabase/supabase/blob/master/examples/ai/llamaindex/llamaindex.ipynb) notebook in Colab:
|
||||
|
||||
<a
|
||||
className="w-64"
|
||||
href="https://colab.research.google.com/github/supabase/supabase/blob/master/examples/ai/llamaindex/llamaindex.ipynb"
|
||||
>
|
||||
<img src="/docs/img/ai/colab-badge.svg" />
|
||||
</a>
|
||||
|
||||
At the top of the notebook, you'll see a button `Copy to Drive`. Click this button to copy the notebook to your Google Drive.
|
||||
|
||||
## Fill in your OpenAI credentials
|
||||
|
||||
Inside the Notebook, add your `OPENAI_API_KEY` key. Find the cell which contains this code:
|
||||
|
||||
```py
|
||||
import os
|
||||
os.environ['OPENAI_API_KEY'] = "[your_openai_api_key]"
|
||||
```
|
||||
|
||||
## Connecting to your database
|
||||
|
||||
Inside the Notebook, find the cell which specifies the `DB_CONNECTION`. It will contain some code like this:
|
||||
|
||||
```python
|
||||
DB_CONNECTION = "postgresql://<user>:<password>@<host>:<port>/<db_name>"
|
||||
|
||||
# create vector store client
|
||||
vx = vecs.create_client(DB_CONNECTION)
|
||||
```
|
||||
|
||||
Replace the `DB_CONNECTION` with your own connection string for your database, which you set up in first step of this guide.
|
||||
|
||||
## Stepping through the notebook
|
||||
|
||||
Now all that's left is to step through the notebook. You can do this by clicking the "execute" button (`ctrl+enter`) at the top left of each code cell. The notebook guides you through the process of creating a collection, adding data to it, and querying it.
|
||||
|
||||
You can view the inserted items in the [Table Editor](https://app.supabase.com/project/_/editor/), by selecting the `vecs` schema from the schema dropdown.
|
||||
|
||||

|
||||
|
||||
## Resources
|
||||
|
||||
- Visit the LlamaIndex + SupabaseVectorStore [docs](https://gpt-index.readthedocs.io/en/latest/examples/vector_stores/SupabaseVectorIndexDemo.html)
|
||||
- Visit the official LlamaIndex [repo](https://github.com/jerryjliu/llama_index/)
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,215 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-lang-chain',
|
||||
title: 'LangChain',
|
||||
description:
|
||||
'Learn how to integrate Supabase with LangChain, a popular framework for composing AI, Vectors, and embeddings',
|
||||
sidebar_label: 'LangChain',
|
||||
}
|
||||
|
||||
[LangChain](langchain.com) is a popular framework for working with AI, Vectors, and embeddings. LangChain supports using Supabase as a [vector store](https://js.langchain.com/docs/modules/indexes/vector_stores/integrations/supabase), using the `pgvector` extension.
|
||||
|
||||
## Initializing your database
|
||||
|
||||
Prepare you database with the relevant tables:
|
||||
|
||||
```sql
|
||||
-- Enable the pgvector extension to work with embedding vectors
|
||||
create extension vector;
|
||||
|
||||
-- Create a table to store your documents
|
||||
create table documents (
|
||||
id bigserial primary key,
|
||||
content text, -- corresponds to Document.pageContent
|
||||
metadata jsonb, -- corresponds to Document.metadata
|
||||
embedding vector(1536) -- 1536 works for OpenAI embeddings, change if needed
|
||||
);
|
||||
|
||||
-- Create a function to search for documents
|
||||
create function match_documents (
|
||||
query_embedding vector(1536),
|
||||
match_count int default null,
|
||||
filter jsonb DEFAULT '{}'
|
||||
) returns table (
|
||||
id bigint,
|
||||
content text,
|
||||
metadata jsonb,
|
||||
similarity float
|
||||
)
|
||||
language plpgsql
|
||||
as $$
|
||||
#variable_conflict use_column
|
||||
begin
|
||||
return query
|
||||
select
|
||||
id,
|
||||
content,
|
||||
metadata,
|
||||
1 - (documents.embedding <=> query_embedding) as similarity
|
||||
from documents
|
||||
where metadata @> filter
|
||||
order by documents.embedding <=> query_embedding
|
||||
limit match_count;
|
||||
end;
|
||||
$$;
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
You can now search your documents using any Node.js application. This is intended to be run on a secure server route.
|
||||
|
||||
```js
|
||||
import { SupabaseVectorStore } from 'langchain/vectorstores/supabase'
|
||||
import { OpenAIEmbeddings } from 'langchain/embeddings/openai'
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
|
||||
const supabaseKey = process.env.SUPABASE_SERVICE_ROLE_KEY
|
||||
if (!supabaseKey) throw new Error(`Expected SUPABASE_SERVICE_ROLE_KEY`)
|
||||
|
||||
const url = process.env.SUPABASE_URL
|
||||
if (!url) throw new Error(`Expected env var SUPABASE_URL`)
|
||||
|
||||
export const run = async () => {
|
||||
const client = createClient(url, supabaseKey)
|
||||
|
||||
const vectorStore = await SupabaseVectorStore.fromTexts(
|
||||
['Hello world', 'Bye bye', "What's this?"],
|
||||
[{ id: 2 }, { id: 1 }, { id: 3 }],
|
||||
new OpenAIEmbeddings(),
|
||||
{
|
||||
client,
|
||||
tableName: 'documents',
|
||||
queryName: 'match_documents',
|
||||
}
|
||||
)
|
||||
|
||||
const resultOne = await vectorStore.similaritySearch('Hello world', 1)
|
||||
|
||||
console.log(resultOne)
|
||||
}
|
||||
```
|
||||
|
||||
### Simple Metadata Filtering
|
||||
|
||||
Given the above `match_documents` Postgres function, you can also pass a filter parameter to only return documents with a specific metadata field value. This filter parameter is a JSON object, and the `match_documents` function will use the Postgres JSONB Containment operator `@>` to filter documents by the metadata field values you specify. See details on the [Postgres JSONB Containment operator](https://www.postgresql.org/docs/current/datatype-json.html#JSON-CONTAINMENT) for more information.
|
||||
|
||||
```js
|
||||
import { SupabaseVectorStore } from 'langchain/vectorstores/supabase'
|
||||
import { OpenAIEmbeddings } from 'langchain/embeddings/openai'
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
|
||||
// First, follow set-up instructions above
|
||||
|
||||
const privateKey = process.env.SUPABASE_SERVICE_ROLE_KEY
|
||||
if (!privateKey) throw new Error(`Expected env var SUPABASE_SERVICE_ROLE_KEY`)
|
||||
|
||||
const url = process.env.SUPABASE_URL
|
||||
if (!url) throw new Error(`Expected env var SUPABASE_URL`)
|
||||
|
||||
export const run = async () => {
|
||||
const client = createClient(url, privateKey)
|
||||
|
||||
const vectorStore = await SupabaseVectorStore.fromTexts(
|
||||
['Hello world', 'Hello world', 'Hello world'],
|
||||
[{ user_id: 2 }, { user_id: 1 }, { user_id: 3 }],
|
||||
new OpenAIEmbeddings(),
|
||||
{
|
||||
client,
|
||||
tableName: 'documents',
|
||||
queryName: 'match_documents',
|
||||
}
|
||||
)
|
||||
|
||||
const result = await vectorStore.similaritySearch('Hello world', 1, {
|
||||
user_id: 3,
|
||||
})
|
||||
|
||||
console.log(result)
|
||||
}
|
||||
```
|
||||
|
||||
### Advanced Metadata Filtering
|
||||
|
||||
You can also use query builder-style filtering ([similar to how the Supabase JavaScript library works](https://supabase.com/docs/reference/javascript/using-filters)) instead of passing an object. Note that since the filter properties will be in the metadata column, you need to use arrow operators (`->` for integer or `->>` for text) as defined in [Postgrest API documentation](https://postgrest.org/en/stable/references/api/tables_views.html?highlight=operators#json-columns) and specify the data type of the property (e.g. the column should look something like `metadata->some_int_value::int`).
|
||||
|
||||
```js
|
||||
import { SupabaseFilterRPCCall, SupabaseVectorStore } from 'langchain/vectorstores/supabase'
|
||||
import { OpenAIEmbeddings } from 'langchain/embeddings/openai'
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
|
||||
// First, follow set-up instructions above
|
||||
|
||||
const privateKey = process.env.SUPABASE_SERVICE_ROLE_KEY
|
||||
if (!privateKey) throw new Error(`Expected env var SUPABASE_SERVICE_ROLE_KEY`)
|
||||
|
||||
const url = process.env.SUPABASE_URL
|
||||
if (!url) throw new Error(`Expected env var SUPABASE_URL`)
|
||||
|
||||
export const run = async () => {
|
||||
const client = createClient(url, privateKey)
|
||||
|
||||
const embeddings = new OpenAIEmbeddings()
|
||||
|
||||
const store = new SupabaseVectorStore(embeddings, {
|
||||
client,
|
||||
tableName: 'documents',
|
||||
})
|
||||
|
||||
const docs = [
|
||||
{
|
||||
pageContent:
|
||||
'This is a long text, but it actually means something because vector database does not understand Lorem Ipsum. So I would need to expand upon the notion of quantum fluff, a theorectical concept where subatomic particles coalesce to form transient multidimensional spaces. Yet, this abstraction holds no real-world application or comprehensible meaning, reflecting a cosmic puzzle.',
|
||||
metadata: { b: 1, c: 10, stuff: 'right' },
|
||||
},
|
||||
{
|
||||
pageContent:
|
||||
'This is a long text, but it actually means something because vector database does not understand Lorem Ipsum. So I would need to proceed by discussing the echo of virtual tweets in the binary corridors of the digital universe. Each tweet, like a pixelated canary, hums in an unseen frequency, a fascinatingly perplexing phenomenon that, while conjuring vivid imagery, lacks any concrete implication or real-world relevance, portraying a paradox of multidimensional spaces in the age of cyber folklore.',
|
||||
metadata: { b: 2, c: 9, stuff: 'right' },
|
||||
},
|
||||
{ pageContent: 'hello', metadata: { b: 1, c: 9, stuff: 'right' } },
|
||||
{ pageContent: 'hello', metadata: { b: 1, c: 9, stuff: 'wrong' } },
|
||||
{ pageContent: 'hi', metadata: { b: 2, c: 8, stuff: 'right' } },
|
||||
{ pageContent: 'bye', metadata: { b: 3, c: 7, stuff: 'right' } },
|
||||
{ pageContent: "what's this", metadata: { b: 4, c: 6, stuff: 'right' } },
|
||||
]
|
||||
|
||||
await store.addDocuments(docs)
|
||||
|
||||
const funcFilterA: SupabaseFilterRPCCall = (rpc) =>
|
||||
rpc
|
||||
.filter('metadata->b::int', 'lt', 3)
|
||||
.filter('metadata->c::int', 'gt', 7)
|
||||
.textSearch('content', `'multidimensional' & 'spaces'`, {
|
||||
config: 'english',
|
||||
})
|
||||
|
||||
const resultA = await store.similaritySearch('quantum', 4, funcFilterA)
|
||||
|
||||
const funcFilterB: SupabaseFilterRPCCall = (rpc) =>
|
||||
rpc
|
||||
.filter('metadata->b::int', 'lt', 3)
|
||||
.filter('metadata->c::int', 'gt', 7)
|
||||
.filter('metadata->>stuff', 'eq', 'right')
|
||||
|
||||
const resultB = await store.similaritySearch('hello', 2, funcFilterB)
|
||||
|
||||
console.log(resultA, resultB)
|
||||
}
|
||||
```
|
||||
|
||||
## Hybrid search
|
||||
|
||||
LangChain supports the concept of a hybrid search, which combines Similarity Search with Full Text Search. Read the official docs to get started: [Supabase Hybrid Search](https://js.langchain.com/docs/modules/indexes/retrievers/supabase-hybrid).
|
||||
|
||||
You can install the LangChain Hybrid Search function though our [database.dev package manager](https://database.dev/langchain/hybrid_search).
|
||||
|
||||
## Resources
|
||||
|
||||
- Official [LangChain site](https://langchain.com/).
|
||||
- Official [LangChain docs](https://js.langchain.com/docs/modules/indexes/vector_stores/integrations/supabase).
|
||||
- Supabase [Hybrid Search](https://js.langchain.com/docs/modules/indexes/retrievers/supabase-hybrid).
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,156 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-collections',
|
||||
title: 'Managing collections',
|
||||
description: 'Learn how to manage groups of vector records using the vecs Python library',
|
||||
sidebar_label: 'Managing collections',
|
||||
}
|
||||
|
||||
A collection is an group of vector records managed by the `vecs` Python library. Records can be added to or updated in a collection. Collections can be queried at any time, but should be indexed for scalable query performance.
|
||||
|
||||
Supabase provides a [Python client](/docs/guides/ai/vecs-python-client) called `vecs` for managing unstructured vector stores in Postgres. If you come from a data science background, this unstructured data approach will feel familiar. If you are more interested in a structured data approach, see [Vector columns](/docs/guides/ai/vector-columns) or read our guide on [Structured & Unstructured Embeddings](/docs/guides/ai/structured-unstructured-embeddings).
|
||||
|
||||
Under the hood `vecs` will manage the necessary Postgres tables and columns to store and query your collections.
|
||||
|
||||
## API
|
||||
|
||||
Find the full API in the [official API docs](https://supabase.github.io/vecs/api).
|
||||
|
||||
### Connecting
|
||||
|
||||
Before you can interact with vecs, create the client to communicate with Postgres.
|
||||
|
||||
```python
|
||||
import vecs
|
||||
|
||||
DB_CONNECTION = "postgresql://<user>:<password>@<host>:<port>/<db_name>"
|
||||
|
||||
# create vector store client
|
||||
vx = vecs.create_client(DB_CONNECTION)
|
||||
```
|
||||
|
||||
### Create collection
|
||||
|
||||
You can create a collection to store vectors specifying the collections name and the number of dimensions in the vectors you intend to store.
|
||||
|
||||
```python
|
||||
docs = vx.create_collection(name="docs", dimension=3)
|
||||
```
|
||||
|
||||
If another collection exists with the same name,
|
||||
|
||||
### Get an existing collection
|
||||
|
||||
To access a previously created collection, use `get_collection` to retrieve it by name
|
||||
|
||||
```python
|
||||
docs = vx.get_collection(name="docs")
|
||||
```
|
||||
|
||||
### Upserting vectors
|
||||
|
||||
`vecs` combines the concepts of "insert" and "update" into "upsert". Upserting records adds them to the collection if the `id` is not present, or updates the existing record if the `id` does exist.
|
||||
|
||||
```python
|
||||
# add records to the collection
|
||||
docs.upsert(
|
||||
vectors=[
|
||||
(
|
||||
"vec0", # the vector's identifier
|
||||
[0.1, 0.2, 0.3], # the vector. list or np.array
|
||||
{"year": 1973} # associated metadata
|
||||
),
|
||||
(
|
||||
"vec1",
|
||||
[0.7, 0.8, 0.9],
|
||||
{"year": 2012}
|
||||
)
|
||||
]
|
||||
)
|
||||
```
|
||||
|
||||
### Create an index
|
||||
|
||||
Collections can be queried immediately after being created.
|
||||
However, for good performance, the collection should be indexed after records have been upserted.
|
||||
|
||||
Indexes should be created **after** the collection has been populated with records. Building an index on an empty collection will result in significantly reduced recall. Once the index has been created you can still upsert new documents into the collection but you should rebuild the index if the size of the collection more than doubles.
|
||||
|
||||
Only one index may exist per-collection. By default, creating an index will replace any existing index.
|
||||
|
||||
To create an index:
|
||||
|
||||
```python
|
||||
##
|
||||
# INSERT RECORDS HERE
|
||||
##
|
||||
|
||||
# index the collection to be queried by cosine distance
|
||||
docs.create_index(measure=vecs.IndexMeasure.cosine_distance)
|
||||
```
|
||||
|
||||
Available options for query `measure` are:
|
||||
|
||||
- `vecs.IndexMeasure.cosine_distance`
|
||||
- `vecs.IndexMeasure.l2_distance`
|
||||
- `vecs.IndexMeasure.max_inner_product`
|
||||
|
||||
which correspond to different methods for comparing query vectors to the vectors in the database.
|
||||
|
||||
If you aren't sure which to use, stick with the default (cosine_distance) by omitting the parameter i.e.: `docs.create_index()`.
|
||||
|
||||
<Admonition type="note">
|
||||
|
||||
The time required to create an index grows with the number of records and size of vectors. For a few thousand records expect sub-minute a response in under a minute. It may take a few minutes for larger collections.
|
||||
|
||||
</Admonition>
|
||||
|
||||
For an in-depth guide on vector indexes, see [Managing indexes](/docs/guides/ai/managing-indexes).
|
||||
|
||||
### Query
|
||||
|
||||
Be aware that indexes are essential for good performance. If you do not create an index, every query will return a warning that includes the `IndexMeasure` you should index.
|
||||
|
||||
#### Basic
|
||||
|
||||
The simplest form of search is to provide a query vector.
|
||||
|
||||
```python
|
||||
docs.query(
|
||||
query_vector=[0.4,0.5,0.6], # required
|
||||
limit=5, # number of records to return
|
||||
filters={}, # metadata filters
|
||||
measure="cosine_distance", # distance measure to use
|
||||
include_value=False, # should distance measure values be returned?
|
||||
include_metadata=False, # should record metadata be returned?
|
||||
)
|
||||
```
|
||||
|
||||
Which returns a list of vector record `ids`.
|
||||
|
||||
#### Metadata Filtering
|
||||
|
||||
The metadata that is associated with each record can also be filtered during a query.
|
||||
|
||||
As an example, `{"year": {"$eq": 2005}}` filters a `year` metadata key to be equal to 2005
|
||||
|
||||
In context:
|
||||
|
||||
```python
|
||||
docs.query(
|
||||
query_vector=[0.4,0.5,0.6],
|
||||
filters={"year": {"$eq": 2012}}, # metadata filters
|
||||
)
|
||||
```
|
||||
|
||||
For a complete reference, see the [metadata guide](https://supabase.github.io/vecs/concepts_metadata/).
|
||||
|
||||
## Resources
|
||||
|
||||
- Official Vecs Documentation: https://supabase.github.io/vecs/api
|
||||
- Source Code: https://github.com/supabase/vecs
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,95 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-managing-indexes',
|
||||
title: 'Managing indexes',
|
||||
description: 'Understanding vector indexes',
|
||||
sidebar_label: 'Managing indexes',
|
||||
}
|
||||
|
||||
Once your vector table starts to grow, you will likely want to add an index to speed up queries. Without indexes, you'll be performing a sequential scan which can be a resource-intensive operation when you have many records.
|
||||
|
||||
## IVFFlat indexes
|
||||
|
||||
Today `pgvector` indexes use an algorithm called IVFFlat. IVF stands for 'inverted file indexes'. It works by clustering your vectors in order to reduce the similarity search scope. Rather than comparing a vector to every other vector, the vector is only compared against vectors within the same cell cluster (or nearby clusters, depending on your configuration).
|
||||
|
||||
### Inverted lists (cell clusters)
|
||||
|
||||
When you create the index, you choose the number of inverted lists (cell clusters). Increase this number to speed up queries, but at the expense of recall.
|
||||
|
||||
For example, to create an index with 100 lists on a column that uses the cosine operator:
|
||||
|
||||
```sql
|
||||
create index on items using ivfflat (column_name vector_cosine_ops) with (lists = 100);
|
||||
```
|
||||
|
||||
For more info on the different operators, see [Distance operations](#distance-operators).
|
||||
|
||||
For every query, you can set the number of probes (1 by default). The number of probes corresponds to the number of nearby cells to probe for a match. Increase this for better recall at the expense of speed.
|
||||
|
||||
To set the number of probes for the duration of the session run:
|
||||
|
||||
```sql
|
||||
set ivfflat.probes = 10;
|
||||
```
|
||||
|
||||
To set the number of probes only for the current transaction run:
|
||||
|
||||
```sql
|
||||
begin;
|
||||
set local ivfflat.probes = 10;
|
||||
select ...
|
||||
commit;
|
||||
```
|
||||
|
||||
If the number of probes is the same as the number of lists, exact nearest neighbor search will be performed and the planner won't use the index.
|
||||
|
||||
### Approximate nearest neighbor
|
||||
|
||||
One important note with IVF indexes is that nearest neighbor search is approximate, since exact search on high dimensional data can't be indexed efficiently. This means that similarity results will change (slightly) after you add an index (trading recall for speed).
|
||||
|
||||
## Distance operators
|
||||
|
||||
The type of index required depends on the distance operator you are using. `pgvector` includes 3 distance operators:
|
||||
|
||||
| Operator | Description | [**Operator class**](https://www.postgresql.org/docs/current/sql-createopclass.html) |
|
||||
| -------- | ---------------------- | ------------------------------------------------------------------------------------ |
|
||||
| `<->` | Euclidean distance | `vector_l2_ops` |
|
||||
| `<#>` | negative inner product | `vector_ip_ops` |
|
||||
| `<=>` | cosine distance | `vector_cosine_ops` |
|
||||
|
||||
Use the following SQL commands to create an index for the operator(s) used in your queries.
|
||||
|
||||
### Euclidean L2 distance (`vector_l2_ops`)
|
||||
|
||||
```sql
|
||||
create index on items using ivfflat (column_name vector_l2_ops) with (lists = 100);
|
||||
```
|
||||
|
||||
### Inner product (`vector_ip_ops`)
|
||||
|
||||
```sql
|
||||
create index on items using ivfflat (column_name vector_ip_ops) with (lists = 100);
|
||||
```
|
||||
|
||||
### Cosine distance (`vector_cosine_ops`)
|
||||
|
||||
```sql
|
||||
create index on items using ivfflat (column_name vector_cosine_ops) with (lists = 100);
|
||||
```
|
||||
|
||||
Currently vectors with up to 2,000 dimensions can be indexed.
|
||||
|
||||
If you are using the `vecs` Python library, follow the instructions in [Managing collections](/docs/guides/ai/managing-collections#create-an-index) to create indexes.
|
||||
|
||||
## When should you add indexes?
|
||||
|
||||
`pgvector` recommends adding indexes only after the table has sufficient data, so that the internal IVFFlat cell clusters are based on your data's distribution. Anytime the distribution changes significantly, consider recreating indexes.
|
||||
|
||||
## Resources
|
||||
|
||||
Read more about indexing on `pgvector`'s [GitHub page](https://github.com/pgvector/pgvector#indexing).
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,156 @@
|
||||
import { CodeHikeConfig, remarkCodeHike } from '@code-hike/mdx'
|
||||
import { GetStaticPaths, GetStaticProps } from 'next'
|
||||
import { MDXRemote, MDXRemoteSerializeResult } from 'next-mdx-remote'
|
||||
import { serialize } from 'next-mdx-remote/serialize'
|
||||
import { relative } from 'path'
|
||||
import rehypeSlug from 'rehype-slug'
|
||||
import remarkGfm from 'remark-gfm'
|
||||
import codeHikeTheme from 'config/code-hike.theme.json' assert { type: 'json' }
|
||||
import components from '~/components'
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
import { UrlTransformFunction, linkTransform } from '~/lib/mdx/plugins/rehypeLinkTransform'
|
||||
import remarkMkDocsAdmonition from '~/lib/mdx/plugins/remarkAdmonition'
|
||||
import { removeTitle } from '~/lib/mdx/plugins/remarkRemoveTitle'
|
||||
|
||||
// We fetch these docs at build time from an external repo
|
||||
const org = 'supabase'
|
||||
const repo = 'vecs'
|
||||
const branch = 'main'
|
||||
const docsDir = 'docs'
|
||||
const externalSite = 'https://supabase.github.io/vecs'
|
||||
|
||||
// Each external docs page is mapped to a local page
|
||||
const pageMap = [
|
||||
{
|
||||
slug: 'api',
|
||||
meta: {
|
||||
title: 'API',
|
||||
},
|
||||
remoteFile: 'api.md',
|
||||
},
|
||||
{
|
||||
slug: 'collections',
|
||||
meta: {
|
||||
title: 'Collections',
|
||||
},
|
||||
remoteFile: 'concepts_collections.md',
|
||||
},
|
||||
{
|
||||
slug: 'indexes',
|
||||
meta: {
|
||||
title: 'Indexes',
|
||||
},
|
||||
remoteFile: 'concepts_indexes.md',
|
||||
},
|
||||
{
|
||||
slug: 'metadata',
|
||||
meta: {
|
||||
title: 'Metadata',
|
||||
},
|
||||
remoteFile: 'concepts_metadata.md',
|
||||
},
|
||||
]
|
||||
|
||||
interface PythonClientDocsProps {
|
||||
source: MDXRemoteSerializeResult
|
||||
meta: {
|
||||
title: string
|
||||
description?: string
|
||||
}
|
||||
}
|
||||
|
||||
export default function PythonClientDocs({ source, meta }: PythonClientDocsProps) {
|
||||
return (
|
||||
<Layout meta={meta}>
|
||||
<MDXRemote {...source} components={components} />
|
||||
</Layout>
|
||||
)
|
||||
}
|
||||
|
||||
/**
|
||||
* Fetch markdown from external repo and transform links
|
||||
*/
|
||||
export const getStaticProps: GetStaticProps<PythonClientDocsProps> = async ({ params }) => {
|
||||
const page = pageMap.find(({ slug }) => slug === params.slug)
|
||||
|
||||
if (!page) {
|
||||
throw new Error(`No page mapping found for slug '${params.slug}'`)
|
||||
}
|
||||
|
||||
const { remoteFile, meta } = page
|
||||
|
||||
const response = await fetch(
|
||||
`https://raw.githubusercontent.com/${org}/${repo}/${branch}/${docsDir}/${remoteFile}`
|
||||
)
|
||||
|
||||
const source = await response.text()
|
||||
|
||||
const urlTransform: UrlTransformFunction = (url) => {
|
||||
try {
|
||||
const externalSiteUrl = new URL(externalSite)
|
||||
|
||||
const placeholderHostname = 'placeholder'
|
||||
const { hostname, pathname, hash } = new URL(url, `http://${placeholderHostname}`)
|
||||
|
||||
// Don't modify a url with a FQDN or a url that's only a hash
|
||||
if (hostname !== placeholderHostname || pathname === '/') {
|
||||
return url
|
||||
}
|
||||
|
||||
const relativePage = (
|
||||
pathname.endsWith('.md')
|
||||
? pathname.replace(/\.md$/, '')
|
||||
: relative(externalSiteUrl.pathname, pathname)
|
||||
).replace(/^\//, '')
|
||||
|
||||
const page = pageMap.find(({ remoteFile }) => `${relativePage}.md` === remoteFile)
|
||||
|
||||
// If we have a mapping for this page, use the mapped path
|
||||
if (page) {
|
||||
return page.slug + hash
|
||||
}
|
||||
|
||||
// If we don't have this page in our docs, link to original docs
|
||||
return `${externalSite}/${relativePage}${hash}`
|
||||
} catch (err) {
|
||||
console.error('Error transforming markdown URL', err)
|
||||
return url
|
||||
}
|
||||
}
|
||||
|
||||
const codeHikeOptions: CodeHikeConfig = {
|
||||
theme: codeHikeTheme,
|
||||
lineNumbers: true,
|
||||
showCopyButton: true,
|
||||
skipLanguages: [],
|
||||
autoImport: false,
|
||||
}
|
||||
|
||||
const mdxSource = await serialize(source, {
|
||||
scope: {
|
||||
chCodeConfig: codeHikeOptions,
|
||||
},
|
||||
mdxOptions: {
|
||||
remarkPlugins: [
|
||||
remarkGfm,
|
||||
remarkMkDocsAdmonition,
|
||||
[removeTitle, meta.title],
|
||||
[remarkCodeHike, codeHikeOptions],
|
||||
],
|
||||
rehypePlugins: [[linkTransform, urlTransform], rehypeSlug],
|
||||
},
|
||||
})
|
||||
|
||||
return { props: { source: mdxSource, meta } }
|
||||
}
|
||||
|
||||
export const getStaticPaths: GetStaticPaths = async () => {
|
||||
return {
|
||||
paths: pageMap.map(({ slug }) => ({
|
||||
params: {
|
||||
slug,
|
||||
},
|
||||
})),
|
||||
fallback: false,
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,62 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-vecs-python-client',
|
||||
title: 'Face similarity search',
|
||||
subtitle: 'Identify the celebrities you looks most similar to using Supabase Vecs.',
|
||||
breadcrumb: 'AI Quickstarts',
|
||||
}
|
||||
|
||||
This guide will walk you through a ["Face Similarity Search"](https://github.com/supabase/supabase/blob/master/examples/ai/face_similarity.ipynb) example using Colab and Supabase Vecs. You'll identify the celebrities you (or any other person) looks most similar to. You will:
|
||||
|
||||
1. Launch a Postgres database that uses pgvector to store embeddings
|
||||
1. Launch a notebook that connects to your database
|
||||
1. Load the "`ashraq/tmdb-people-image`" celebrity dataset
|
||||
1. Use the `face_recognition` model to create an embedding for every celebrity photo.
|
||||
1. Search for similar faces inside the dataset.
|
||||
|
||||
<DatabaseSetup />
|
||||
|
||||
## Launching a notebook
|
||||
|
||||
Launch our [`semantic_text_deduplication`](https://github.com/supabase/supabase/blob/master/examples/ai/face_similarity.ipynb) notebook in Colab:
|
||||
|
||||
<a
|
||||
className="w-64"
|
||||
href="https://colab.research.google.com/github/supabase/supabase/blob/master/examples/ai/face_similarity.ipynb"
|
||||
>
|
||||
<img src="/docs/img/ai/colab-badge.svg" />
|
||||
</a>
|
||||
|
||||
At the top of the notebook, you'll see a button `Copy to Drive`. Click this button to copy the notebook to your Google Drive.
|
||||
|
||||
## Connecting to your database
|
||||
|
||||
Inside the Notebook, find the cell which specifies the `DB_CONNECTION`. It will contain some code like this:
|
||||
|
||||
```python
|
||||
import vecs
|
||||
|
||||
DB_CONNECTION = "postgresql://<user>:<password>@<host>:<port>/<db_name>"
|
||||
|
||||
# create vector store client
|
||||
vx = vecs.create_client(DB_CONNECTION)
|
||||
```
|
||||
|
||||
Replace the `DB_CONNECTION` with your own connection string for your database, which you set up in first step of this guide.
|
||||
|
||||
## Stepping through the notebook
|
||||
|
||||
Now all that's left is to step through the notebook. You can do this by clicking the "execute" button (`ctrl+enter`) at the top left of each code cell. The notebook guides you through the process of creating a collection, adding data to it, and querying it.
|
||||
|
||||
You can view the inserted items in the [Table Editor](https://app.supabase.com/project/_/editor/), by selecting the `vecs` schema from the schema dropdown.
|
||||
|
||||

|
||||
|
||||
## Next steps
|
||||
|
||||
You can now start building your own applications with Vecs. Check our [examples](/docs/guides/ai#examples) for ideas.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,62 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-vecs-python-client',
|
||||
title: 'Creating and managing collections',
|
||||
subtitle: 'Connecting to your database with Colab.',
|
||||
breadcrumb: 'AI Quickstarts',
|
||||
}
|
||||
|
||||
This guide will walk you through a basic ["Hello World"](https://github.com/supabase/supabase/blob/master/examples/ai/vector_hello_world.ipynb) example using Colab and Supabase Vecs. You'll learn how to:
|
||||
|
||||
1. Launch a Postgres database that uses pgvector to store embeddings
|
||||
1. Launch a notebook that connects to your database
|
||||
1. Create a vector collection
|
||||
1. Add data to the collection
|
||||
1. Query the collection
|
||||
|
||||
<DatabaseSetup />
|
||||
|
||||
## Launching a notebook
|
||||
|
||||
Launch our [`vector_hello_world`](https://github.com/supabase/supabase/blob/master/examples/ai/vector_hello_world.ipynb) notebook in Colab:
|
||||
|
||||
<a
|
||||
className="w-64"
|
||||
href="https://colab.research.google.com/github/supabase/supabase/blob/master/examples/ai/vector_hello_world.ipynb"
|
||||
>
|
||||
<img src="/docs/img/ai/colab-badge.svg" />
|
||||
</a>
|
||||
|
||||
At the top of the notebook, you'll see a button `Copy to Drive`. Click this button to copy the notebook to your Google Drive.
|
||||
|
||||
## Connecting to your database
|
||||
|
||||
Inside the Notebook, find the cell which specifies the `DB_CONNECTION`. It will contain some code like this:
|
||||
|
||||
```python
|
||||
import vecs
|
||||
|
||||
DB_CONNECTION = "postgresql://<user>:<password>@<host>:<port>/<db_name>"
|
||||
|
||||
# create vector store client
|
||||
vx = vecs.create_client(DB_CONNECTION)
|
||||
```
|
||||
|
||||
Replace the `DB_CONNECTION` with your own connection string for your database, which you set up in first step of this guide.
|
||||
|
||||
## Stepping through the notebook
|
||||
|
||||
Now all that's left is to step through the notebook. You can do this by clicking the "execute" button (`ctrl+enter`) at the top left of each code cell. The notebook guides you through the process of creating a collection, adding data to it, and querying it.
|
||||
|
||||
You can view the inserted items in the [Table Editor](https://app.supabase.com/project/_/editor/), by selecting the `vecs` schema from the schema dropdown.
|
||||
|
||||

|
||||
|
||||
## Next steps
|
||||
|
||||
You can now start building your own applications with Vecs. Check our [examples](/docs/guides/ai#examples) for ideas.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,65 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
import HuggingFaceDeployment from '~/components/MDX/ai/quickstart_hf_deployment.mdx'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-vecs-python-client',
|
||||
title: 'Semantic Text Deduplication',
|
||||
subtitle: 'Finding duplicate movie reviews with Supabase Vecs.',
|
||||
breadcrumb: 'AI Quickstarts',
|
||||
}
|
||||
|
||||
This guide will walk you through a ["Semantic Text Deduplication"](https://github.com/supabase/supabase/blob/master/examples/ai/semantic_text_deduplication.ipynb) example using Colab and Supabase Vecs. You'll learn how to find similar movie reviews using embeddings, and remove any that seem like duplicates. You will:
|
||||
|
||||
1. Launch a Postgres database that uses pgvector to store embeddings
|
||||
1. Launch a notebook that connects to your database
|
||||
1. Load the IMDB dataset
|
||||
1. Use the `sentence-transformers/all-MiniLM-L6-v2` model to create an embedding representing the semantic meaning of each review.
|
||||
1. Search for all duplicates.
|
||||
|
||||
<DatabaseSetup />
|
||||
|
||||
## Launching a notebook
|
||||
|
||||
Launch our [`semantic_text_deduplication`](https://github.com/supabase/supabase/blob/master/examples/ai/semantic_text_deduplication.ipynb) notebook in Colab:
|
||||
|
||||
<a
|
||||
className="w-64"
|
||||
href="https://colab.research.google.com/github/supabase/supabase/blob/master/examples/ai/semantic_text_deduplication.ipynb"
|
||||
>
|
||||
<img src="/docs/img/ai/colab-badge.svg" />
|
||||
</a>
|
||||
|
||||
At the top of the notebook, you'll see a button `Copy to Drive`. Click this button to copy the notebook to your Google Drive.
|
||||
|
||||
## Connecting to your database
|
||||
|
||||
Inside the Notebook, find the cell which specifies the `DB_CONNECTION`. It will contain some code like this:
|
||||
|
||||
```python
|
||||
import vecs
|
||||
|
||||
DB_CONNECTION = "postgresql://<user>:<password>@<host>:<port>/<db_name>"
|
||||
|
||||
# create vector store client
|
||||
vx = vecs.create_client(DB_CONNECTION)
|
||||
```
|
||||
|
||||
Replace the `DB_CONNECTION` with your own connection string for your database, which you set up in first step of this guide.
|
||||
|
||||
## Stepping through the notebook
|
||||
|
||||
Now all that's left is to step through the notebook. You can do this by clicking the "execute" button (`ctrl+enter`) at the top left of each code cell. The notebook guides you through the process of creating a collection, adding data to it, and querying it.
|
||||
|
||||
You can view the inserted items in the [Table Editor](https://app.supabase.com/project/_/editor/), by selecting the `vecs` schema from the schema dropdown.
|
||||
|
||||

|
||||
|
||||
<HuggingFaceDeployment />
|
||||
|
||||
## Next steps
|
||||
|
||||
You can now start building your own applications with Vecs. Check our [examples](/docs/guides/ai#examples) for ideas.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,114 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'structured-unstructured-embeddings',
|
||||
title: 'Structured and Unstructured',
|
||||
description:
|
||||
'Supabase is flexible enough to associate structured and unstructured metadata with embeddings.',
|
||||
subtitle:
|
||||
'Supabase is flexible enough to associate structured and unstructured metadata with embeddings.',
|
||||
sidebar_label: 'Structured and unstructured embeddings',
|
||||
}
|
||||
|
||||
Most vector stores treat metadata associated with embeddings like NoSQL, unstructured data. Supabase is flexible enough to store unstructured and structured metadata.
|
||||
|
||||
## Structured
|
||||
|
||||
```sql
|
||||
create table docs (
|
||||
id uuid primary key,
|
||||
embedding vector(3),
|
||||
content text,
|
||||
url string
|
||||
);
|
||||
|
||||
insert into docs
|
||||
(id, content, url, embedding)
|
||||
values
|
||||
('79409372-7556-4ccc-ab8f-5786a6cfa4f7', array[0.1, 0.2, 0.3], 'Hello world', '/hello-world');
|
||||
```
|
||||
|
||||
Notice that we've associated two pieces of metadata, `content` and `url`, with the embedding. Those fields can be filtered, constrained, indexed, and generally operated on using the full power of SQL. Structured metadata fits naturally with a traditional Supabase application, and can be managed via database [migrations](/docs/guides/getting-started/local-development#database-migrations).
|
||||
|
||||
## Unstructured
|
||||
|
||||
```sql
|
||||
create table docs (
|
||||
id uuid primary key,
|
||||
embedding vector(3),
|
||||
meta jsonb
|
||||
);
|
||||
|
||||
insert into docs
|
||||
(id, embedding, meta)
|
||||
values
|
||||
(
|
||||
'79409372-7556-4ccc-ab8f-5786a6cfa4f7',
|
||||
array[0.1, 0.2, 0.3],
|
||||
'{"content": "Hello world", "url": "/hello-world"}'
|
||||
);
|
||||
```
|
||||
|
||||
An unstructured approach does not specify the metadata fields that are expected. It stores all metadata in a flexible `json`/`jsonb` column. The tradeoff is that the querying/filtering capabilities of a schemaless data type are less flexible than when each field has a dedicated column. It also pushes the burden of metadata data integrity onto application code, which is more error prone than enforcing constraints in the database.
|
||||
|
||||
The unstructured approach is recommended:
|
||||
|
||||
- for ephemeral/interactive workloads e.g. data science or scientific research
|
||||
- when metadata fields are user-defined or unknown
|
||||
- during rapid prototyping
|
||||
|
||||
Client libraries like python's [vecs](https://github.com/supabase/vecs) use this structure. For example, running:
|
||||
|
||||
```py
|
||||
#!/usr/bin/env python3
|
||||
import vecs
|
||||
|
||||
docs = vx.create_collection(name="docs", dimension=1536)
|
||||
|
||||
docs.upsert(vectors=[
|
||||
('79409372-7556-4ccc-ab8f-5786a6cfa4f7', [100, 200, 300], { url: '/hello-world' })
|
||||
])
|
||||
|
||||
```
|
||||
|
||||
automatically creates the unstructured SQL table during the call to `create_collection`.
|
||||
|
||||
Note that when working with client libraries that emit SQL DDL, like `create table ...`, you should add that SQL to your migrations when moving to production to maintain a single source of truth for your database's schema.
|
||||
|
||||
## Hybrid
|
||||
|
||||
The structured metadata style is recommended when the fields being tracked are known in advance. If you have a combination of known and unknown metadata fields, you can accommodate the unknown fields by adding a `json`/`jsonb` column to the table. In that situation, known fields should continue to use dedicated columns for best query performance and throughput.
|
||||
|
||||
```sql
|
||||
create table docs (
|
||||
id uuid primary key,
|
||||
embedding vector(3),
|
||||
content text,
|
||||
url string,
|
||||
meta jsonb
|
||||
);
|
||||
|
||||
insert into docs
|
||||
(id, embedding, meta)
|
||||
values
|
||||
(
|
||||
'79409372-7556-4ccc-ab8f-5786a6cfa4f7',
|
||||
array[0.1, 0.2, 0.3],
|
||||
'Hello world',
|
||||
'/hello-world',
|
||||
'{"key": "value"}'
|
||||
);
|
||||
```
|
||||
|
||||
## Choosing the right model
|
||||
|
||||
Both approaches create a table where you can store your embeddings and some metadata. You should choose the best approach for your use-case. In summary:
|
||||
|
||||
- Structured metadata is best when fields are known in advance or query patterns are predictable e.g. a production Supabase application
|
||||
- Unstructured metadata is best when fields are unknown/user-defined or when working with data interactively e.g. exploratory research
|
||||
|
||||
Both approaches are valid, and the one you should choose depends on your use-case.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,91 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
import StepHikeCompact from '~/components/StepHikeCompact'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-vecs-python-client',
|
||||
title: 'Python client',
|
||||
subtitle: 'Manage unstructured vector stores in PostgreSQL.',
|
||||
breadcrumb: 'AI Quickstarts',
|
||||
}
|
||||
|
||||
Supabase provides a Python client called [`vecs`](https://github.com/supabase/vecs) for managing unstructured vector stores. This client provides a set of useful tools for creating and querying collections in PostgreSQL using the [pgvector](/docs/guides/database/extensions/pgvector) extension.
|
||||
|
||||
## Quick start
|
||||
|
||||
Let's see how Vecs works using a local database. Make sure you have the Supabase CLI [installed](/docs/guides/cli#installation) on your machine.
|
||||
|
||||
### Initialize your project
|
||||
|
||||
Start a local Postgres instance in any folder using the `init` and `start` commands. Make sure you have Docker running!
|
||||
|
||||
```bash
|
||||
# Initialize your project
|
||||
supabase init
|
||||
|
||||
# Start Postgres
|
||||
supabase start
|
||||
```
|
||||
|
||||
### Create a collection
|
||||
|
||||
Inside a Python shell, run the following commands to create a new collection called "docs", with 3 dimensions.
|
||||
|
||||
```py
|
||||
import vecs
|
||||
|
||||
# create vector store client
|
||||
vx = vecs.create_client("postgresql://postgres:postgres@localhost:54322/postgres")
|
||||
|
||||
# create a collection of vectors with 3 dimensions
|
||||
docs = vx.create_collection(name="docs", dimension=3)
|
||||
```
|
||||
|
||||
### Add embeddings
|
||||
|
||||
Now we can insert some embeddings into our "docs" collection using the `usert()` command:
|
||||
|
||||
```py
|
||||
import vecs
|
||||
|
||||
# create vector store client
|
||||
docs = vecs.get_collection(name="docs")
|
||||
|
||||
# a collection of vectors with 3 dimensions
|
||||
vectors=[
|
||||
("vec0", [0.1, 0.2, 0.3], {"year": 1973}),
|
||||
("vec1", [0.7, 0.8, 0.9], {"year": 2012})
|
||||
]
|
||||
|
||||
# insert our vectors
|
||||
docs.upsert(vectors=vectors)
|
||||
```
|
||||
|
||||
### Query the collection
|
||||
|
||||
You can now query the collection to retrieve a relevant match:
|
||||
|
||||
```py
|
||||
import vecs
|
||||
|
||||
docs = vecs.get_collection(name="docs")
|
||||
|
||||
# query the collection filtering metadata for "year" = 2012
|
||||
docs.query(
|
||||
query_vector=[0.4,0.5,0.6], # required
|
||||
limit=1, # number of records to return
|
||||
filters={"year": {"$eq": 2012}}, # metadata filters
|
||||
)
|
||||
```
|
||||
|
||||
## Deep Dive
|
||||
|
||||
For a more in-depth guide on `vecs` collections, see [Managing collections](/docs/guides/ai/managing-collections).
|
||||
|
||||
## Resources
|
||||
|
||||
- Official Vecs Documentation: https://supabase.github.io/vecs/api
|
||||
- Source Code: https://github.com/supabase/vecs
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -0,0 +1,153 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'ai-vector-columns',
|
||||
title: 'Vector columns',
|
||||
description: 'Learn how to use vectors within your own Postgres tables',
|
||||
sidebar_label: 'Vector columns',
|
||||
}
|
||||
|
||||
Supabase offers a number of different ways to store and query vectors within Postgres. If you prefer to use Python to store and query your vectors using collections, see [Managing collections](/docs/guides/ai/managing-collections). If you want more control over vectors within your own Postgres tables or would like to interact with them using a different language like JavaScript, keep reading.
|
||||
|
||||
Vectors in Supabase are enabled via [pgvector](https://github.com/pgvector/pgvector/), a PostgreSQL extension for storing and querying vectors in Postgres. It can be used to store [embeddings](/docs/guides/ai/concepts#what-are-embeddings).
|
||||
|
||||
## Usage
|
||||
|
||||
### Enable the extension
|
||||
|
||||
<Tabs
|
||||
scrollable
|
||||
size="small"
|
||||
type="underlined"
|
||||
defaultActiveId="dashboard"
|
||||
>
|
||||
<TabPanel id="dashboard" label="Dashboard">
|
||||
|
||||
1. Go to the [Database](https://app.supabase.com/project/_/database/tables) page in the Dashboard.
|
||||
2. Click on **Extensions** in the sidebar.
|
||||
3. Search for "vector" and enable the extension.
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="sql" label="SQL">
|
||||
|
||||
```sql
|
||||
-- Example: enable the "vector" extension.
|
||||
create extension vector
|
||||
with
|
||||
schema extensions;
|
||||
|
||||
-- Example: disable the "vector" extension
|
||||
drop
|
||||
extension if exists vector;
|
||||
```
|
||||
|
||||
Even though the SQL code is `create extension`, this is the equivalent of "enabling the extension".
|
||||
To disable an extension, call `drop extension`.
|
||||
|
||||
</TabPanel>
|
||||
</Tabs>
|
||||
|
||||
### Create a table to store vectors
|
||||
|
||||
After enabling the `vector` extension, you will get access to a new data type called `vector`. The size of the vector (indicated in parenthesis) represents the number of dimensions stored in that vector.
|
||||
|
||||
```sql
|
||||
create table documents (
|
||||
id serial primary key,
|
||||
title text not null,
|
||||
body text not null,
|
||||
embedding vector(1536)
|
||||
);
|
||||
```
|
||||
|
||||
In the above SQL snippet, we create a `documents` table with a column called `embedding` (note this is just a regular Postgres column - you can name it whatever you like). We give the `embedding` column a `vector` data type with 1536 dimensions. Change this to the number of dimensions used in your vector application. For example, if you are generating embeddings using OpenAI's `text-embeddings-ada-002` model, you would set this number as 1536 since that model produces 1536 dimensions.
|
||||
|
||||
### Storing a vector / embedding
|
||||
|
||||
In this example we'll generate a vector using the OpenAI API client, then store it in the database using the Supabase JavaScript client.
|
||||
|
||||
```js
|
||||
const title = 'First post!'
|
||||
const body = 'Hello world!'
|
||||
|
||||
// Generate a vector using OpenAI
|
||||
const embeddingResponse = await openai.createEmbedding({
|
||||
model: 'text-embedding-ada-002',
|
||||
input: body,
|
||||
})
|
||||
|
||||
const [{ embedding }] = embeddingResponse.data.data
|
||||
|
||||
// Store the vector in Postgres
|
||||
const { data, error } = await supabase.from('documents').insert({
|
||||
title,
|
||||
body,
|
||||
embedding,
|
||||
})
|
||||
```
|
||||
|
||||
This example uses the JavaScript Supabase client, but you can modify it to work with any [supported language library](/docs#client-libraries).
|
||||
|
||||
### Querying a vector / embedding
|
||||
|
||||
Similarity search is the most common use case for vectors. `pgvector` support 3 new operators for performing similarity search:
|
||||
|
||||
| Operator | Description |
|
||||
| -------- | ---------------------- |
|
||||
| `<->` | Euclidean distance |
|
||||
| `<#>` | negative inner product |
|
||||
| `<=>` | cosine distance |
|
||||
|
||||
Choosing the right operator depends on your needs. If you are searching over OpenAI embeddings, OpenAI recommends using cosine similarity. For more information on how embeddings work and how they relate to each other, see [What are Embeddings?](/docs/guides/ai/concepts#what-are-embeddings).
|
||||
|
||||
Supabase client libraries like `supabase-js` connect to your Postgres instance via [PostgREST](docs/guides/getting-started/architecture#postgrest-api). PostgREST does not currently support `pgvector` similarity operators, so we'll need to wrap our query in a Postgres function and call it via the `rpc()` method:
|
||||
|
||||
```sql
|
||||
create or replace function match_documents (
|
||||
query_embedding vector(1536),
|
||||
match_threshold float,
|
||||
match_count int
|
||||
)
|
||||
returns table (
|
||||
id bigint,
|
||||
content text,
|
||||
similarity float
|
||||
)
|
||||
language sql stable
|
||||
as $$
|
||||
select
|
||||
documents.id,
|
||||
documents.content,
|
||||
1 - (documents.embedding <=> query_embedding) as similarity
|
||||
from documents
|
||||
where 1 - (documents.embedding <=> query_embedding) > match_threshold
|
||||
order by similarity desc
|
||||
limit match_count;
|
||||
$$;
|
||||
```
|
||||
|
||||
This function takes a `query_embedding` argument and compares it to all other embeddings in the `documents` table. Each comparison returns a similarity score. If the similarity is greater than the `match_threshold` argument, it is returned. The number of rows returned is limited by the `match_count` argument.
|
||||
|
||||
Feel free to modify this method to fit the needs of your application. The `match_threshold` ensures that only documents that have a minimum similarity to the `query_embedding` are returned. Without this, you may end up returning documents that subjectively don't match. This value will vary for each application - you will need to perform your own testing to determine the threshold that makes sense for your app.
|
||||
|
||||
To execute the function from your client library, call `rpc()` with the name of your Postgres function:
|
||||
|
||||
```ts
|
||||
const { data: documents } = await supabaseClient.rpc('match_documents', {
|
||||
query_embedding: embedding, // Pass the embedding you want to compare
|
||||
match_threshold: 0.78, // Choose an appropriate threshold for your data
|
||||
match_count: 10, // Choose the number of matches
|
||||
})
|
||||
```
|
||||
|
||||
In this example `embedding` would be another embedding you wish to compare against your table of pre-generated embedding documents. For example if you were building a search engine, every time the user submits their query you would first generate an embedding on the search query itself (using `openai.createEmbedding()`), then pass it into the above `rpc()` function to match.
|
||||
|
||||
Vectors and embedding can be used for much more than search. Learn more about embeddings at [What are Embeddings?](/docs/guides/ai/concepts#what-are-embeddings).
|
||||
|
||||
### Indexes
|
||||
|
||||
Once your vector table starts to grow, you will likely want to add an index to speed up queries. See [Managing indexes](/docs/guides/ai/managing-indexes) to learn how vector indexes work and how to create them.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -74,6 +74,17 @@ Supabase provides a Realtime API using [Realtime](https://github.com/supabase/re
|
||||
Realtime leverages PostgreSQL's built-in logical replication. You can manage your Realtime API simply by managing Postgres publications.
|
||||
Go to your project's [Replication section](https://app.supabase.com/project/_/database/replication) to get started.
|
||||
|
||||
## API URL and Keys
|
||||
|
||||
You can find the API URL and Keys in the [Dashboard](https://app.supabase.com/project/_/settings/api).
|
||||
|
||||
<video width="99%" muted playsInline controls={true}>
|
||||
<source
|
||||
src="https://xguihxuzqibwxjnimxev.supabase.co/storage/v1/object/public/videos/docs/api/api-url-and-key.mp4"
|
||||
type="video/mp4"
|
||||
/>
|
||||
</video>
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -90,7 +90,7 @@ const [captchaToken, setCaptchaToken] = useState()
|
||||
|
||||
Now lets add the HCaptcha component to the JSX section of our code
|
||||
|
||||
```html
|
||||
```jsx
|
||||
<HCaptcha />
|
||||
```
|
||||
|
||||
|
||||
@@ -95,7 +95,7 @@ Future<void> signOut() async {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Supabase Flutter Client](https://github.com/supabase/supabase-flutter)
|
||||
|
||||
|
||||
@@ -19,6 +19,14 @@ A collection of framework-specific Auth utilities for working with Supabase.
|
||||
description={'A pre-built React component for authenticating users.'}
|
||||
/>
|
||||
</div>
|
||||
{/* Flutter Auth UI */}
|
||||
<div className="col-span-6">
|
||||
<ButtonCard
|
||||
to={'/guides/auth/auth-helpers/flutter-auth-ui'}
|
||||
title={'Flutter Auth UI'}
|
||||
description={'Pre-built Flutter widgets for authenticating users.'}
|
||||
/>
|
||||
</div>
|
||||
{/* Next.js */}
|
||||
<div className="col-span-6">
|
||||
<ButtonCard
|
||||
|
||||
@@ -25,7 +25,7 @@ npm install @supabase/supabase-js @supabase/auth-ui-react @supabase/auth-ui-shar
|
||||
|
||||
Pass `supabaseClient` from `@supabase/supabase-js` as a prop to the component.
|
||||
|
||||
```js title=/src/index.js
|
||||
```js /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
|
||||
@@ -38,7 +38,7 @@ This renders the Auth component without any styling.
|
||||
We recommend using one of the predefined themes to style the UI.
|
||||
Import the theme you want to use and pass it to the `appearance.theme` prop.
|
||||
|
||||
```js lines=4,16 title=/src/index.js
|
||||
```js mark=4,16 /src/index.js
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
import {
|
||||
// Import predefined theme
|
||||
@@ -63,7 +63,7 @@ const App = () => (
|
||||
|
||||
The Auth component also supports login with [official social providers](../../auth#providers).
|
||||
|
||||
```js lines=13 title=/src/index.js
|
||||
```js mark=11 /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
import { ThemeSupa } from '@supabase/auth-ui-shared'
|
||||
@@ -79,6 +79,23 @@ const App = () => (
|
||||
)
|
||||
```
|
||||
|
||||
### Options
|
||||
|
||||
Options are available via `queryParams`:
|
||||
|
||||
```jsx
|
||||
<Auth
|
||||
supabaseClient={supabase}
|
||||
providers={['google']}
|
||||
queryParams={{
|
||||
access_type: 'offline',
|
||||
prompt: 'consent',
|
||||
hd: 'domain.com',
|
||||
}}
|
||||
onlyThirdPartyProviders={true}
|
||||
/>
|
||||
```
|
||||
|
||||
### Supported Views
|
||||
|
||||
The Auth component is currently shipped with the following views:
|
||||
@@ -106,7 +123,7 @@ There are several ways to customize Auth UI:
|
||||
|
||||
Auth UI comes with several themes to customize the appearance. Each predefined theme comes with at least two variations, a `default` variation, and a `dark` variation. You can switch between these themes using the `theme` prop. Import the theme you want to use and pass it to the `appearance.theme` prop.
|
||||
|
||||
```js lines=2,13 title=/src/index.js
|
||||
```js mark=3,14 /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
import { ThemeSupa } from '@supabase/auth-ui-shared'
|
||||
@@ -135,7 +152,7 @@ Currently there is only one predefined theme available, but we plan to add more.
|
||||
|
||||
Auth UI comes with two theme variations: `default` and `dark`. You can switch between these themes with the `theme` prop.
|
||||
|
||||
```js lines=14 title=/src/index.js
|
||||
```js mark=15 /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
import { ThemeSupa } from '@supabase/auth-ui-shared'
|
||||
@@ -161,7 +178,7 @@ If you don't pass a value to `theme` it uses the `"default"` theme. You can pass
|
||||
|
||||
Auth UI themes can be overridden using variable tokens. See the [list of variable tokens](https://github.com/supabase/auth-ui/blob/main/packages/shared/src/theming/Themes.ts).
|
||||
|
||||
```js lines=14-21 title=/src/index.js
|
||||
```js mark=12:19 /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
import { ThemeSupa } from '@supabase/auth-ui-shared'
|
||||
@@ -193,7 +210,7 @@ If you created your own theme, you may not need to override any of the them.
|
||||
You can create your own theme by following the same structure within a `appearance.theme` property.
|
||||
See the list of [tokens within a theme](https://github.com/supabase/auth-ui/blob/main/packages/shared/src/theming/Themes.ts).
|
||||
|
||||
```js title=/src/index.js
|
||||
```js /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
|
||||
@@ -243,7 +260,7 @@ You can swich between different variations of your theme with the ["theme" prop]
|
||||
You can use custom CSS classes for the following elements:
|
||||
`"button"`, `"container"`, `"anchor"`, `"divider"`, `"label"`, `"input"`, `"loader"`, `"message"`.
|
||||
|
||||
```js title=/src/index.js
|
||||
```js /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
|
||||
@@ -271,7 +288,7 @@ const App = () => (
|
||||
You can use custom CSS inline styles for the following elements:
|
||||
`"button"`, `"container"`, `"anchor"`, `"divider"`, `"label"`, `"input"`, `"loader"`, `"message"`.
|
||||
|
||||
```js title=/src/index.js
|
||||
```js /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
|
||||
@@ -295,7 +312,7 @@ const App = () => (
|
||||
|
||||
You can use custom labels with `localization.variables`. See the [list of labels](https://github.com/supabase/auth-ui/blob/main/packages/shared/src/localization/en.json) that can be overwritten.
|
||||
|
||||
```js title=/src/index.js
|
||||
```js mark=10:15 /src/index.js
|
||||
import { createClient } from '@supabase/supabase-js'
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
|
||||
@@ -304,7 +321,6 @@ const supabase = createClient('<INSERT PROJECT URL>', '<INSERT PROJECT ANON API
|
||||
const App = () => (
|
||||
<Auth
|
||||
supabaseClient={supabase}
|
||||
//highlight-start
|
||||
localization={{
|
||||
variables: {
|
||||
sign_in: {
|
||||
@@ -313,7 +329,6 @@ const App = () => (
|
||||
},
|
||||
},
|
||||
}}
|
||||
//highlight-end
|
||||
/>
|
||||
)
|
||||
```
|
||||
|
||||
@@ -0,0 +1,130 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'flutter-auth-ui',
|
||||
title: 'Flutter Auth UI',
|
||||
description: 'Prebuilt, customizable Flutter widgets for authenticating users.',
|
||||
}
|
||||
|
||||
Flutter Auth UI is a Flutter package containing pre-built widgets for authenticating users.
|
||||
It is unstyled and can match your brand and aesthetic.
|
||||
|
||||
<image src="https://raw.githubusercontent.com/supabase-community/flutter-auth-ui/main/assets/supabase_auth_ui.png" />
|
||||
|
||||
## Add Flutter Auth UI
|
||||
|
||||
Add the latest version of the package [supabase-auth-ui](https://pub.dev/packages/supabase_auth_ui) to pubspec.yaml:
|
||||
|
||||
```yaml
|
||||
dependencies:
|
||||
flutter:
|
||||
sdk: flutter
|
||||
supabase_auth_ui: ^0.1.0+2
|
||||
```
|
||||
|
||||
### Initialize the Flutter Auth Package
|
||||
|
||||
```dart
|
||||
import 'package:flutter/material.dart';
|
||||
import 'package:supabase_auth_ui/supabase_auth_ui.dart';
|
||||
|
||||
void main() async {
|
||||
await Supabase.initialize(
|
||||
url: dotenv.get('SUPABASE_URL'),
|
||||
anonKey: dotenv.get('SUPABASE_ANON_KEY'),
|
||||
);
|
||||
|
||||
runApp(const MyApp());
|
||||
}
|
||||
```
|
||||
|
||||
### Email Auth
|
||||
|
||||
Use a SupaEmailAuth widget to create an email and password signin and signup form. It also contains a button to toggle to display a forgot password form.
|
||||
|
||||
You can pass metadataFields to add additional fields to the form to pass as metadata to Supabase.
|
||||
|
||||
```dart
|
||||
SupaEmailAuth(
|
||||
redirectTo: kIsWeb ? null : 'io.mydomain.myapp://callback',
|
||||
onSignInComplete: (response) {},
|
||||
onSignUpComplete: (response) {},
|
||||
metadataFields: [
|
||||
MetaDataField(
|
||||
prefixIcon: const Icon(Icons.person),
|
||||
label: 'Username',
|
||||
key: 'username',
|
||||
validator: (val) {
|
||||
if (val == null || val.isEmpty) {
|
||||
return 'Please enter something';
|
||||
}
|
||||
return null;
|
||||
},
|
||||
),
|
||||
],
|
||||
)
|
||||
```
|
||||
|
||||
### Magic Link Auth
|
||||
|
||||
Use SupaMagicAuth widget to create a magic link signIn form.
|
||||
|
||||
```dart
|
||||
SupaMagicAuth(
|
||||
redirectUrl: kIsWeb ? null : 'io.mydomain.myapp://callback',
|
||||
onSuccess: (Session response) {},
|
||||
onError: (error) {},
|
||||
)
|
||||
```
|
||||
|
||||
### Reset password
|
||||
|
||||
Use SupaResetPassword to create a password reset form.
|
||||
|
||||
```dart
|
||||
SupaResetPassword(
|
||||
accessToken: supabase.auth.currentSession?.accessToken,
|
||||
onSuccess: (UserResponse response) {},
|
||||
onError: (error) {},
|
||||
)
|
||||
```
|
||||
|
||||
### Phone Auth
|
||||
|
||||
Use SupaPhoneAuth to create a phone authentication form.
|
||||
|
||||
```dart
|
||||
SupaPhoneAuth(
|
||||
authAction: SupaAuthAction.signUp,
|
||||
onSuccess: (AuthResponse response) {},
|
||||
),
|
||||
```
|
||||
|
||||
### Social Auth
|
||||
|
||||
The package supports login with [official social providers](../../auth#providers).
|
||||
|
||||
Use SupaSocialsAuth to create list of social login buttons.
|
||||
|
||||
```dart
|
||||
SupaSocialsAuth(
|
||||
socialProviders: [
|
||||
SocialProviders.apple,
|
||||
SocialProviders.google,
|
||||
],
|
||||
colored: true,
|
||||
redirectUrl: kIsWeb
|
||||
? null
|
||||
: 'io.mydomain.myapp://callback',
|
||||
onSuccess: (Session response) {},
|
||||
onError: (error) {},
|
||||
)
|
||||
```
|
||||
|
||||
### Theming
|
||||
|
||||
This package uses plain Flutter components allowing you to control the appearance of the components using your own theme.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -62,7 +62,7 @@ yarn add @supabase/auth-helpers-react
|
||||
|
||||
Retrieve your project URL and anon key in your project's [API settings](https://app.supabase.com/project/_/settings/api) in the Dashboard to set up the following environment variables. For local development you can set them in a `.env.local` file. See an [example](https://github.com/supabase/auth-helpers/blob/main/examples/nextjs/.env.local.example).
|
||||
|
||||
```bash title=.env.local
|
||||
```bash .env.local
|
||||
NEXT_PUBLIC_SUPABASE_URL=your-supabase-url
|
||||
NEXT_PUBLIC_SUPABASE_ANON_KEY=your-supabase-anon-key
|
||||
```
|
||||
@@ -79,7 +79,7 @@ NEXT_PUBLIC_SUPABASE_ANON_KEY=your-supabase-anon-key
|
||||
|
||||
Wrap your `pages/_app.js` component with the `SessionContextProvider` component:
|
||||
|
||||
```jsx title=pages/_app.js
|
||||
```jsx pages/_app.js
|
||||
import { createPagesBrowserClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { SessionContextProvider } from '@supabase/auth-helpers-react'
|
||||
import { useState } from 'react'
|
||||
@@ -104,7 +104,7 @@ function MyApp({ Component, pageProps }) {
|
||||
|
||||
Wrap your `pages/_app.tsx` component with the `SessionContextProvider` component:
|
||||
|
||||
```tsx lines=2,8 title=pages/_app.tsx
|
||||
```tsx mark=2,8 pages/_app.tsx
|
||||
import { createPagesBrowserClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { SessionContextProvider, Session } from '@supabase/auth-helpers-react'
|
||||
import { useState } from 'react'
|
||||
@@ -148,7 +148,7 @@ The `Code Exchange` API route is required for the [server-side auth flow](https:
|
||||
|
||||
Create a new file at `pages/api/auth/callback.js` and populate with the following:
|
||||
|
||||
```jsx title="pages/api/auth/callback.js"
|
||||
```jsx pages/api/auth/callback.js
|
||||
import { NextApiHandler } from 'next'
|
||||
import { createPagesServerClient } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
@@ -172,7 +172,7 @@ export default handler
|
||||
|
||||
Create a new file at `pages/api/auth/callback.ts` and populate with the following:
|
||||
|
||||
```tsx title="pages/api/auth/callback.ts"
|
||||
```tsx pages/api/auth/callback.ts
|
||||
import { NextApiHandler } from 'next'
|
||||
import { createPagesServerClient } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
@@ -242,7 +242,7 @@ export default async (req: NextApiRequest, res: NextApiResponse) => {
|
||||
|
||||
For [row level security](/docs/learn/auth-deep-dive/auth-row-level-security) to work properly when fetching data client-side, you need to make sure to use the `supabaseClient` from the `useSupabaseClient` hook and only run your query once the user is defined client-side in the `useUser()` hook:
|
||||
|
||||
```jsx lines=10-17
|
||||
```jsx mark=10:17
|
||||
import { Auth } from '@supabase/auth-ui-react'
|
||||
import { ThemeSupa } from '@supabase/auth-ui-shared'
|
||||
import { useUser, useSupabaseClient } from '@supabase/auth-helpers-react'
|
||||
@@ -291,7 +291,7 @@ export default LoginPage
|
||||
|
||||
Create a server supabase client to retrieve the logged in user's session:
|
||||
|
||||
```jsx title=pages/profile.js
|
||||
```jsx pages/profile.js
|
||||
import { createPagesServerClient } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
export default function Profile({ user }) {
|
||||
@@ -553,7 +553,7 @@ Create a server supabase client to retrieve the logged in user's session:
|
||||
>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title=pages/api/protected-route.js
|
||||
```jsx pages/api/protected-route.js
|
||||
import { createPagesServerClient } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
const ProtectedRoute = async (req, res) => {
|
||||
@@ -581,7 +581,7 @@ export default ProtectedRoute
|
||||
</TabPanel>
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title=pages/api/protected-route.ts
|
||||
```tsx pages/api/protected-route.ts
|
||||
import { NextApiHandler } from 'next'
|
||||
import { createPagesServerClient } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
@@ -614,7 +614,7 @@ export default ProtectedRoute
|
||||
|
||||
As an alternative to protecting individual pages you can use a [Next.js Middleware](https://nextjs.org/docs/middleware) to protect the entire directory or those that match the config object. In the following example, all requests to `/middleware-protected/*` will check whether a user is signed in, if successful the request will be forwarded to the destination route, otherwise the user will be redirected:
|
||||
|
||||
```ts title=middleware.ts
|
||||
```ts middleware.ts
|
||||
import { createMiddlewareClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { NextResponse } from 'next/server'
|
||||
import type { NextRequest } from 'next/server'
|
||||
@@ -698,7 +698,7 @@ Use `createPagesServerClient` within your `NextApiHandler`:
|
||||
>
|
||||
<TabPanel id="before" label="Before">
|
||||
|
||||
```tsx title=pages/api/protected-route.ts
|
||||
```tsx pages/api/protected-route.ts
|
||||
import { withApiAuth } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
export default withApiAuth(async function ProtectedRoute(req, res, supabase) {
|
||||
@@ -711,7 +711,7 @@ export default withApiAuth(async function ProtectedRoute(req, res, supabase) {
|
||||
</TabPanel>
|
||||
<TabPanel id="after" label="After">
|
||||
|
||||
```tsx title=pages/api/protected-route.ts
|
||||
```tsx pages/api/protected-route.ts
|
||||
import { NextApiHandler } from 'next'
|
||||
import { createPagesServerClient } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
@@ -752,7 +752,7 @@ Use `createPagesServerClient` within `getServerSideProps`:
|
||||
>
|
||||
<TabPanel id="before" label="Before">
|
||||
|
||||
```tsx title=pages/profile.tsx
|
||||
```tsx pages/profile.tsx
|
||||
import { withPageAuth, User } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
export default function Profile({ user }: { user: User }) {
|
||||
@@ -765,7 +765,7 @@ export const getServerSideProps = withPageAuth({ redirectTo: '/' })
|
||||
</TabPanel>
|
||||
<TabPanel id="after" label="After">
|
||||
|
||||
```tsx title=pages/profile.js
|
||||
```tsx pages/profile.js
|
||||
import { createPagesServerClient, User } from '@supabase/auth-helpers-nextjs'
|
||||
import { GetServerSidePropsContext } from 'next'
|
||||
|
||||
@@ -811,7 +811,7 @@ export const getServerSideProps = async (ctx: GetServerSidePropsContext) => {
|
||||
>
|
||||
<TabPanel id="before" label="Before">
|
||||
|
||||
```tsx title=middleware.ts
|
||||
```tsx middleware.ts
|
||||
import { withMiddlewareAuth } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
export const middleware = withMiddlewareAuth({
|
||||
@@ -832,7 +832,7 @@ export const config = {
|
||||
</TabPanel>
|
||||
<TabPanel id="after" label="After">
|
||||
|
||||
```tsx title=middleware.ts
|
||||
```tsx middleware.ts
|
||||
import { createMiddlewareClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { NextResponse } from 'next/server'
|
||||
import type { NextRequest } from 'next/server'
|
||||
|
||||
@@ -10,6 +10,15 @@ export const meta = {
|
||||
|
||||
The [Next.js Auth Helpers package](https://github.com/supabase/auth-helpers) configures Supabase Auth to store the user's `session` in a `cookie`, rather than `localStorage`. This makes it available across the client and server of the App Router - [Client Components](/docs/guides/auth/auth-helpers/nextjs#client-components), [Server Components](/docs/guides/auth/auth-helpers/nextjs#server-components), [Server Actions](/docs/guides/auth/auth-helpers/nextjs#server-actions), [Route Handlers](/docs/guides/auth/auth-helpers/nextjs#route-handlers) and [Middleware](/docs/guides/auth/auth-helpers/nextjs#middleware). The `session` is automatically sent along with any requests to Supabase.
|
||||
|
||||
<div className="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/MVYhyGZGLuo"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
> Note: If you are using the `pages` directory, check out [Auth Helpers in Next.js Pages Directory](/docs/guides/auth/auth-helpers/nextjs-pages).
|
||||
|
||||
## Configuration
|
||||
@@ -43,7 +52,7 @@ yarn add @supabase/auth-helpers-nextjs
|
||||
|
||||
Retrieve your project's URL and anon key from your [API settings](https://app.supabase.com/project/_/settings/api), and create a `.env.local` file with the following environment variables:
|
||||
|
||||
```bash title=".env.local"
|
||||
```bash .env.local
|
||||
NEXT_PUBLIC_SUPABASE_URL=your-supabase-url
|
||||
NEXT_PUBLIC_SUPABASE_ANON_KEY=your-supabase-anon-key
|
||||
```
|
||||
@@ -62,7 +71,7 @@ NEXT_PUBLIC_SUPABASE_ANON_KEY=your-supabase-anon-key
|
||||
|
||||
Create a new `middleware.js` file in the root of your project and populate with the following:
|
||||
|
||||
```jsx title="middleware.js"
|
||||
```jsx middleware.js
|
||||
import { createMiddlewareClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { NextResponse } from 'next/server'
|
||||
|
||||
@@ -80,7 +89,7 @@ export async function middleware(req) {
|
||||
|
||||
Create a new `middleware.ts` file in the root of your project and populate with the following:
|
||||
|
||||
```tsx title="middleware.ts"
|
||||
```tsx middleware.ts
|
||||
import { createMiddlewareClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { NextResponse } from 'next/server'
|
||||
|
||||
@@ -116,7 +125,7 @@ The `Code Exchange` route is required for the [server-side auth flow](https://su
|
||||
|
||||
Create a new file at `app/auth/callback/route.js` and populate with the following:
|
||||
|
||||
```jsx title="app/auth/callback.route.js"
|
||||
```jsx app/auth/callback/route.js
|
||||
import { createRouteHandlerClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { cookies } from 'next/headers'
|
||||
import { NextResponse } from 'next/server'
|
||||
@@ -141,7 +150,7 @@ export async function GET(request) {
|
||||
|
||||
Create a new file at `app/auth/callback/route.ts` and populate with the following:
|
||||
|
||||
```tsx title="app/auth/callback.route.ts"
|
||||
```tsx app/auth/callback/route.ts
|
||||
import { createRouteHandlerClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { cookies } from 'next/headers'
|
||||
import { NextResponse } from 'next/server'
|
||||
@@ -170,6 +179,15 @@ export async function GET(request: NextRequest) {
|
||||
|
||||
## Authentication
|
||||
|
||||
<div className="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/11zi7sUJFoU"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
Authentication can be initiated [client](/docs/guides/auth/auth-helpers/nextjs#client-side) or [server-side](/docs/guides/auth/auth-helpers/nextjs#server-side). All of the [supabase-js authentication strategies](/docs/reference/javascript/auth-api) are supported with the Auth Helpers client.
|
||||
|
||||
> Note: The authentication flow requires the [Code Exchange Route](/docs/guides/auth/auth-helpers/nextjs#code-exchange-route) to exchange a `code` for the user's `session`.
|
||||
@@ -186,7 +204,7 @@ Client Components can be used to trigger the authentication process from event h
|
||||
>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title="app/login.js"
|
||||
```jsx app/login.js
|
||||
'use client'
|
||||
|
||||
import { createClientComponentClient } from '@supabase/auth-helpers-nextjs'
|
||||
@@ -244,7 +262,7 @@ export default function Login() {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title="app/login.ts"
|
||||
```tsx app/login.ts
|
||||
'use client'
|
||||
|
||||
import { createClientComponentClient } from '@supabase/auth-helpers-nextjs'
|
||||
@@ -319,7 +337,7 @@ The combination of [Server Components](https://nextjs.org/docs/getting-started/r
|
||||
>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title="app/login.js"
|
||||
```jsx app/login.js
|
||||
import { createServerActionClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { revalidatePath } from 'next/cache'
|
||||
import { cookies } from 'next/headers'
|
||||
@@ -379,7 +397,7 @@ export default async function Login() {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title="app/login.ts"
|
||||
```tsx app/login.ts
|
||||
import { createServerActionClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { revalidatePath } from 'next/cache'
|
||||
import { cookies } from 'next/headers'
|
||||
@@ -446,6 +464,15 @@ export default async function Login() {
|
||||
|
||||
### Client Component
|
||||
|
||||
<div className="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/f4yAnVgcJqI"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
[Client Components](https://nextjs.org/docs/getting-started/react-essentials#client-components) allow the use of client-side hooks - such as `useEffect` and `useState`. They can be used to request data from Supabase client-side, and [subscribe to realtime events](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs/app/realtime-posts.tsx).
|
||||
|
||||
<Tabs
|
||||
@@ -456,7 +483,7 @@ export default async function Login() {
|
||||
>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title="app/client/page.jsx"
|
||||
```jsx app/client/page.jsx
|
||||
'use client'
|
||||
|
||||
import { createClientComponentClient } from '@supabase/auth-helpers-nextjs'
|
||||
@@ -483,7 +510,7 @@ export default function Home() {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```jsx title="app/new-post.tsx"
|
||||
```jsx app/new-post.tsx
|
||||
"use client";
|
||||
|
||||
import { createClientComponentClient } from "@supabase/auth-helpers-nextjs";
|
||||
@@ -521,8 +548,25 @@ export default function Home() {
|
||||
|
||||
> check out [this repo](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs) for more examples, including [realtime subscriptions](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs/app/realtime-posts.tsx).
|
||||
|
||||
#### Singleton
|
||||
|
||||
The `createClientComponentClient` function implements a [Singleton pattern](https://en.wikipedia.org/wiki/Singleton_pattern) to simplify instantiating Supabase clients. If you need multiple Supabase instances across Client Components - for example, when using multiple schemas - you can pass an additional configuration option for `{ isSingleton: false }` to get a new client every time this function is called.
|
||||
|
||||
```jsx
|
||||
const supabase = createClientComponentClient({ isSingleton: false })
|
||||
```
|
||||
|
||||
### Server Component
|
||||
|
||||
<div className="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/SUS1t6Kq7-8"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
[Server Components](https://nextjs.org/docs/getting-started/react-essentials#server-components) allow for asynchronous data to be fetched server-side.
|
||||
|
||||
> Note: In order to use Supabase in Server Components, you need to have implemented the [Middleware](/docs/guides/auth/auth-helpers/nextjs#refresh-session-with-middleware) steps above.
|
||||
@@ -535,7 +579,7 @@ export default function Home() {
|
||||
>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title="app/page.jsx"
|
||||
```jsx app/page.jsx
|
||||
import { cookies } from 'next/headers'
|
||||
import { createServerComponentClient } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
@@ -550,7 +594,7 @@ export default async function Home() {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title="app/page.tsx"
|
||||
```tsx app/page.tsx
|
||||
import { cookies } from 'next/headers'
|
||||
import { createServerComponentClient } from '@supabase/auth-helpers-nextjs'
|
||||
|
||||
@@ -572,6 +616,15 @@ export default async function ServerComponent() {
|
||||
|
||||
### Server Action
|
||||
|
||||
<div className="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/B5TUzTKO9CE"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
[Server Actions](https://nextjs.org/docs/app/building-your-application/data-fetching/server-actions) allow mutations to be performed server-side.
|
||||
|
||||
> Note: Server Actions are currently in `alpha` so may change without notice.
|
||||
@@ -584,7 +637,7 @@ export default async function ServerComponent() {
|
||||
>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title="app/new-post.jsx"
|
||||
```jsx app/new-post.jsx
|
||||
import { cookies } from 'next/headers'
|
||||
import { createServerActionClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { revalidatePath } from 'next/cache'
|
||||
@@ -611,7 +664,7 @@ export default async function NewTodo() {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title="app/new-post.tsx"
|
||||
```tsx app/new-post.tsx
|
||||
import { cookies } from 'next/headers'
|
||||
import { createServerActionClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { revalidatePath } from 'next/cache'
|
||||
@@ -643,6 +696,15 @@ export default async function NewTodo() {
|
||||
|
||||
### Route Handler
|
||||
|
||||
<div className="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/3kK-40z0DHI"
|
||||
frameBorder="1"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowFullScreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
[Route Handlers](https://nextjs.org/docs/app/building-your-application/routing/router-handlers) replace API Routes and allow for logic to be performed server-side. They can respond to `GET`, `POST`, `PUT`, `PATCH`, `DELETE`, `HEAD`, and `OPTIONS` requests.
|
||||
|
||||
<Tabs
|
||||
@@ -653,7 +715,7 @@ export default async function NewTodo() {
|
||||
>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title="app/api/todos/route.jsx"
|
||||
```jsx app/api/todos/route.jsx
|
||||
import { createRouteHandlerClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { NextResponse } from 'next/server'
|
||||
import { cookies } from 'next/headers'
|
||||
@@ -670,7 +732,7 @@ export async function POST(request) {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title="app/api/todos/route.tsx"
|
||||
```tsx app/api/todos/route.tsx
|
||||
import { createRouteHandlerClient } from '@supabase/auth-helpers-nextjs'
|
||||
import { NextResponse } from 'next/server'
|
||||
import { cookies } from 'next/headers'
|
||||
@@ -696,8 +758,9 @@ See [refreshing session example](/docs/guides/auth/auth-helpers/nextjs#refresh-s
|
||||
|
||||
## More examples
|
||||
|
||||
- [Full App Router repo](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs)
|
||||
- [Realtime](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs/app/realtime-posts.tsx)
|
||||
- [Cookie-based Auth and the Next.js 13 App Router (free course)](https://youtube.com/playlist?list=PL5S4mPUpp4OtMhpnp93EFSo42iQ40XjbF)
|
||||
- [Full App Router example](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs)
|
||||
- [Realtime Subscriptions](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs/app/realtime-posts.tsx)
|
||||
- [Protected Routes](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs/app/[id]/page.tsx)
|
||||
- [Conditional Rendering in Client Components with SSR](https://github.com/supabase/supabase/tree/master/examples/auth/nextjs/app/login-form.tsx)
|
||||
|
||||
@@ -736,7 +799,7 @@ With v0.7.x of the Next.js Auth Helpers a new naming convention has been impleme
|
||||
|
||||
#### createClientComponentClient returns singleton
|
||||
|
||||
You no longer need to implement logic to ensure there is only a single instance of the Supabase Client shared across all Client Components - this is now handled by the `createClientComponentClient` function. Call it as many times as you want!
|
||||
You no longer need to implement logic to ensure there is only a single instance of the Supabase Client shared across all Client Components - this is now the default and handled by the `createClientComponentClient` function. Call it as many times as you want!
|
||||
|
||||
```jsx
|
||||
"use client";
|
||||
@@ -749,6 +812,8 @@ export default function() {
|
||||
}
|
||||
```
|
||||
|
||||
For an example of creating multiple Supabase clients, check [Singleton section](/docs/guides/auth/auth-helpers/nextjs#singleton) above.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
export default Page
|
||||
@@ -56,7 +56,7 @@ This library supports the following tooling versions:
|
||||
|
||||
Retrieve your project URL and anon key in your project's [API settings](https://app.supabase.com/project/_/settings/api) in the Dashboard to set up the following environment variables. For local development you can set them in a `.env` file. See an [example](https://github.com/supabase/auth-helpers/blob/main/examples/remix/.env.example).
|
||||
|
||||
```bash title=.env
|
||||
```bash .env
|
||||
SUPABASE_URL=YOUR_SUPABASE_URL
|
||||
SUPABASE_ANON_KEY=YOUR_SUPABASE_ANON_KEY
|
||||
```
|
||||
@@ -75,7 +75,7 @@ The `Code Exchange` route is required for the [server-side auth flow](https://su
|
||||
|
||||
Create a new file at `app/routes/auth.callback.jsx` and populate with the following:
|
||||
|
||||
```jsx title="app/routes/auth.callback.jsx"
|
||||
```jsx app/routes/auth.callback.jsx
|
||||
import { redirect } from '@remix-run/node'
|
||||
import { createServerClient } from '@supabase/auth-helpers-remix'
|
||||
|
||||
@@ -105,7 +105,7 @@ export const loader = async ({ request }) => {
|
||||
|
||||
Create a new file at `app/routes/auth.callback.tsx` and populate with the following:
|
||||
|
||||
```tsx title="app/routes/auth.callback.tsx"
|
||||
```tsx app/routes/auth.callback.tsx
|
||||
import { redirect } from '@remix-run/node'
|
||||
import { createServerClient } from '@supabase/auth-helpers-remix'
|
||||
|
||||
@@ -328,7 +328,7 @@ Since our environment variables are not available client-side, we need to plumb
|
||||
>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title=app/root.jsx
|
||||
```jsx app/root.jsx
|
||||
export const loader = () => {
|
||||
const env = {
|
||||
SUPABASE_URL: process.env.SUPABASE_URL,
|
||||
@@ -343,26 +343,26 @@ export const loader = () => {
|
||||
|
||||
Next, we call the `useLoaderData` hook in our component to get the `env` object.
|
||||
|
||||
```jsx title=app/root.jsx
|
||||
```jsx app/root.jsx
|
||||
const { env } = useLoaderData()
|
||||
```
|
||||
|
||||
We then want to instantiate a single instance of a Supabase browser client, to be used across our client-side components.
|
||||
|
||||
```jsx title=app/root.jsx
|
||||
```jsx app/root.jsx
|
||||
const [supabase] = useState(() => createBrowserClient(env.SUPABASE_URL, env.SUPABASE_ANON_KEY))
|
||||
```
|
||||
|
||||
And then we can share this instance across our application with Outlet Context.
|
||||
|
||||
```jsx title=app/root.jsx
|
||||
```jsx app/root.jsx
|
||||
<Outlet context={{ supabase }} />
|
||||
```
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title=app/root.tsx
|
||||
```tsx app/root.tsx
|
||||
export const loader = ({}: LoaderArgs) => {
|
||||
const env = {
|
||||
SUPABASE_URL: process.env.SUPABASE_URL!,
|
||||
@@ -377,13 +377,13 @@ export const loader = ({}: LoaderArgs) => {
|
||||
|
||||
Next, we call the `useLoaderData` hook in our component to get the `env` object.
|
||||
|
||||
```tsx title=app/root.tsx
|
||||
```tsx app/root.tsx
|
||||
const { env } = useLoaderData<typeof loader>()
|
||||
```
|
||||
|
||||
We then want to instantiate a single instance of a Supabase browser client, to be used across our client-side components.
|
||||
|
||||
```tsx title=app/root.tsx
|
||||
```tsx app/root.tsx
|
||||
const [supabase] = useState(() =>
|
||||
createBrowserClient<Database>(env.SUPABASE_URL, env.SUPABASE_ANON_KEY)
|
||||
)
|
||||
@@ -391,7 +391,7 @@ const [supabase] = useState(() =>
|
||||
|
||||
And then we can share this instance across our application with Outlet Context.
|
||||
|
||||
```tsx title=app/root.tsx
|
||||
```tsx app/root.tsx
|
||||
<Outlet context={{ supabase }} />
|
||||
```
|
||||
|
||||
@@ -417,7 +417,7 @@ Let's pipe that through from our loader.
|
||||
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title=app/root.jsx
|
||||
```jsx app/root.jsx
|
||||
export const loader = async ({ request }) => {
|
||||
const env = {
|
||||
SUPABASE_URL: process.env.SUPABASE_URL,
|
||||
@@ -451,7 +451,7 @@ export const loader = async ({ request }) => {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title=app/root.tsx
|
||||
```tsx app/root.tsx
|
||||
export const loader = async ({ request }: LoaderArgs) => {
|
||||
const env = {
|
||||
SUPABASE_URL: process.env.SUPABASE_URL!,
|
||||
@@ -496,7 +496,7 @@ And then use the revalidator, inside the `onAuthStateChange` hook.
|
||||
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title=app/root.jsx
|
||||
```jsx app/root.jsx
|
||||
const { env, session } = useLoaderData()
|
||||
const { revalidate } = useRevalidator()
|
||||
|
||||
@@ -524,7 +524,7 @@ useEffect(() => {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title=app/root.tsx
|
||||
```tsx app/root.tsx
|
||||
const { env, session } = useLoaderData<typeof loader>()
|
||||
const { revalidate } = useRevalidator()
|
||||
|
||||
@@ -569,7 +569,7 @@ Now we can use our outlet context to access our single instance of Supabase and
|
||||
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title=app/components/login.jsx
|
||||
```jsx app/components/login.jsx
|
||||
export default function Login() {
|
||||
const { supabase } = useOutletContext()
|
||||
|
||||
@@ -607,7 +607,7 @@ export default function Login() {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title=app/components/login.tsx
|
||||
```tsx app/components/login.tsx
|
||||
export default function Login() {
|
||||
const { supabase } = useOutletContext<{ supabase: SupabaseClient<Database> }>()
|
||||
|
||||
@@ -656,7 +656,7 @@ export default function Login() {
|
||||
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```jsx title=app/routes/realtime.jsx
|
||||
```jsx app/routes/realtime.jsx
|
||||
import { useLoaderData, useOutletContext } from '@remix-run/react'
|
||||
import { createServerClient } from '@supabase/auth-helpers-remix'
|
||||
import { json } from '@remix-run/node'
|
||||
@@ -704,7 +704,7 @@ export default function Index() {
|
||||
|
||||
<TabPanel id="ts" label="TypeScript">
|
||||
|
||||
```tsx title=app/routes/realtime.tsx
|
||||
```tsx app/routes/realtime.tsx
|
||||
import { useLoaderData, useOutletContext } from '@remix-run/react'
|
||||
import { createServerClient } from '@supabase/auth-helpers-remix'
|
||||
import { json } from '@remix-run/node'
|
||||
|
||||
File diff suppressed because it is too large.
Load diff
@@ -88,7 +88,7 @@ Future<void> signOut() async {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Supabase Flutter Client](https://github.com/supabase/supabase-flutter)
|
||||
|
||||
|
||||
@@ -65,7 +65,7 @@ We are using `next` as our query parameter, but this can name whatever you like.
|
||||
The email link you receive will behave like a magic link. When the link is clicked you will be sent to the `redirectTo` URL you specified that points to the path with the exchange code.
|
||||
|
||||
### Exchange authorization code
|
||||
After redirecting to the server page, we need to retrieve the code from the query parameter called `code` and pass it to the `.exchangeAuthCodeForSession` function.
|
||||
After redirecting to the server page, we need to retrieve the code from the query parameter called `code` and pass it to the `.exchangeCodeForSession` function.
|
||||
```ts
|
||||
// api/auth/callback.ts
|
||||
|
||||
|
||||
@@ -104,6 +104,8 @@ create policy "Users can update their own profiles."
|
||||
2. Enables RLS.
|
||||
3. Creates a policy which allows logged in users to update their own data.
|
||||
|
||||
**Note:** If you want to use upsert operations, the user needs to have `INSERT`, `UPDATE`, and `SELECT` permissions.
|
||||
|
||||
### Only anon or authenticated access
|
||||
|
||||
You can add a Postgres role
|
||||
|
||||
@@ -1,4 +1,5 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
import AppleSecretGenerator from '~/components/AppleSecretGenerator'
|
||||
|
||||
export const meta = {
|
||||
id: 'auth-apple',
|
||||
@@ -89,69 +90,15 @@ Now you'll need to download a `secret key` file from Apple that will be used to
|
||||
- Save the downloaded file -- this contains your "secret key" that will be used to generate your `client_secret`.
|
||||
- Click `Done` at the top right.
|
||||
|
||||
## Generate a `client_secret`
|
||||
## Generate a client secret
|
||||
|
||||
The `secret key` you downloaded is used to create the `client_secret` string you'll need to authenticate your users.
|
||||
You need to configure a client secret when using Sign in with Apple for Web. This is a specially crafted [JWT signed with a secret key downloaded from Apple's Developer Center](https://developer.apple.com/documentation/signinwithapplerestapi/generate_and_validate_tokens).
|
||||
|
||||
According to the [Apple Docs](https://developer.apple.com/documentation/signinwithapplerestapi/generate_and_validate_tokens) it needs to be a JWT
|
||||
token encrypted using the Elliptic Curve Digital Signature Algorithm (ECDSA) with the P-256 curve and the SHA-256 hash algorithm.
|
||||
<Admonition>
|
||||
Use this tool to generate a new Apple client secret. No keys leave your browser!
|
||||
</Admonition>
|
||||
|
||||
At this time, the easiest way to generate this JWT token is with [Ruby](https://www.ruby-lang.org/en/).
|
||||
If you don't have Ruby installed, you can [Download Ruby Here](https://www.ruby-lang.org/en/downloads).
|
||||
|
||||
- Install Ruby (or check to make sure it's installed on your system).
|
||||
- Install [ruby-jwt](https://github.com/jwt/ruby-jwt).
|
||||
- From the command line, run: `sudo gem install jwt`.
|
||||
|
||||
Create the script below using a text editor: `secret_gen.rb`
|
||||
|
||||
```ruby
|
||||
require "jwt"
|
||||
|
||||
key_file = "Path to the private key"
|
||||
team_id = "Your Team ID"
|
||||
client_id = "The Service ID of the service you created"
|
||||
key_id = "The Key ID of the private key"
|
||||
|
||||
validity_period = 180 # In days. Max 180 (6 months) according to Apple docs.
|
||||
|
||||
private_key = OpenSSL::PKey::EC.new IO.read key_file
|
||||
|
||||
token = JWT.encode(
|
||||
{
|
||||
iss: team_id,
|
||||
iat: Time.now.to_i,
|
||||
exp: Time.now.to_i + 86400 * validity_period,
|
||||
aud: "https://appleid.apple.com",
|
||||
sub: client_id
|
||||
},
|
||||
private_key,
|
||||
"ES256",
|
||||
header_fields=
|
||||
{
|
||||
kid: key_id
|
||||
}
|
||||
)
|
||||
puts token
|
||||
```
|
||||
|
||||
1. Edit the `secret_gen.rb` file:
|
||||
|
||||
- `key_file` = "Path to the private key you downloaded from Apple". It should look like this: `AuthKey_XXXXXXXXXX.p8`.
|
||||
- `team_id` = "Your Team ID". This is found at the Apple Developer website, under Membership details. This is a 10-character alphanumeric string called "Team ID". Alternatively, this can be seen next to your name in the upper right when viewing your Certificates, Identifiers & Profiles.
|
||||
- `client_id` = "The Service ID of the service you created". This is the `Services ID` you created in the above step `Obtain a Services ID`. If you've lost this ID, you can find it in the Apple Developer Site:
|
||||
- Go to `Certificates, Identifiers & Profiles`.
|
||||
- Click `Identifiers` at the left.
|
||||
- At the top right drop-down, select `Services IDs`.
|
||||
- Find your Identifier in the list (i.e. app.com.acme.roadrunner).
|
||||
- `key_id` = "The Key ID of the private key". This can be found in the name of your downloaded secret file (For a file named `AuthKey_XXXXXXXXXX.p8` your key_id is `XXXXXXXXXX`). If you've lost this ID, you can find it in the Apple Developer Site:
|
||||
- Go to `Certificates, Identifiers & Profiles`.
|
||||
- Click `Keys` at the left.
|
||||
- Click on your newly-created key in the list.
|
||||
- Look under `Key ID` to find your key_id.
|
||||
|
||||
2. From the command line, run: `ruby secret_gen.rb > client_secret.txt`.
|
||||
3. Your `client_secret` is now stored in this `client_secret.txt` file.
|
||||
<AppleSecretGenerator />
|
||||
|
||||
## Add your OAuth credentials to Supabase
|
||||
|
||||
@@ -180,8 +127,6 @@ async function signout() {
|
||||
## Resources
|
||||
|
||||
- [Apple Developer Account](https://developer.apple.com).
|
||||
- [Ruby](https://www.ruby-lang.org/en/) Docs.
|
||||
- [ruby-jwt](https://github.com/jwt/ruby-jwt) library.
|
||||
- Thanks to [Janak Amarasena](https://medium.com/@janakda) who did all the heavy lifting in [How to configure Sign In with Apple](https://medium.com/identity-beyond-borders/how-to-configure-sign-in-with-apple-77c61e336003).
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
@@ -68,7 +68,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Bitbucket Account](https://bitbucket.org)
|
||||
|
||||
|
||||
@@ -69,7 +69,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Discord Account](https://discord.com)
|
||||
- [Discord Developer Portal](https://discord.com/developers)
|
||||
|
||||
@@ -83,7 +83,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Facebook Developers Dashboard](https://developers.facebook.com/)
|
||||
|
||||
|
||||
@@ -79,7 +79,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [GitHub Developer Settings](https://github.com/settings/developers)
|
||||
|
||||
|
||||
@@ -65,7 +65,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [GitLab Account](https://gitlab.com)
|
||||
|
||||
|
||||
@@ -105,6 +105,7 @@ async function signInWithGoogle() {
|
||||
queryParams: {
|
||||
access_type: 'offline',
|
||||
prompt: 'consent',
|
||||
hd: 'domain.com', // google will also allow OAuth logins to be restricted to a specified domain using the 'hd' parameter
|
||||
},
|
||||
},
|
||||
})
|
||||
@@ -113,7 +114,7 @@ async function signInWithGoogle() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Google Cloud Platform Console](https://console.cloud.google.com/home/dashboard)
|
||||
|
||||
|
||||
@@ -64,7 +64,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [LinkedIn Developer Dashboard](https://api.LinkedIn.com/apps)
|
||||
|
||||
|
||||
@@ -68,7 +68,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Notion Account](https://notion.so)
|
||||
- [Notion Developer Portal](https://www.notion.so/my-integrations)
|
||||
|
||||
@@ -80,7 +80,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Slack Developer Dashboard](https://api.slack.com/apps)
|
||||
|
||||
|
||||
@@ -72,7 +72,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Spotify Developer Dashboard](https://developer.spotify.com/dashboard/)
|
||||
|
||||
|
||||
@@ -83,7 +83,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Twitch Account](https://twitch.tv)
|
||||
- [Twitch Developer Console](https://dev.twitch.tv/console)
|
||||
|
||||
@@ -73,7 +73,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Twitter Developer Dashboard](https://developer.twitter.com/en/portal/dashboard)
|
||||
|
||||
|
||||
@@ -81,7 +81,7 @@ async function signout() {
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Zoom App Marketplace](https://marketplace.zoom.us/)
|
||||
|
||||
|
||||
@@ -25,7 +25,7 @@ You can use the `supabase sso` [subcommands](/docs/reference/cli/supabase-sso) t
|
||||
|
||||
SAML 2.0 support is disabled by default on Supabase projects. You can configure this on the [Auth Providers](https://app.supabase.com/project/_/auth/providers) page on your project.
|
||||
|
||||
Please note that SAML 2.0 support is offered on tiers Pro and above. Check the [Pricing](https://supabase.com/pricing) page for more information.
|
||||
Please note that SAML 2.0 support is offered on plans Pro and above. Check the [Pricing](https://supabase.com/pricing) page for more information.
|
||||
|
||||
## Terminology
|
||||
|
||||
|
||||
@@ -13,9 +13,16 @@ The Supabase CLI provides the tools you need to manage multiple environments.
|
||||
This guide shows you how to set up your local Supabase development environment that integrates with GitHub Actions to automatically
|
||||
test and release schema changes to staging and production Supabase projects.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
Make sure you have these installed on your local machine:
|
||||
|
||||
- [Docker Desktop](https://docs.docker.com/desktop/)
|
||||
- [Supabase CLI](/docs/guides/cli)
|
||||
- [Git](https://github.com/git-guides/install-git)
|
||||
|
||||
To get started:
|
||||
|
||||
- [Install the Supabase CLI](/docs/guides/cli)
|
||||
- Create a [Supabase project](https://app.supabase.com) or use an existing one
|
||||
- Initialize a local Git repository
|
||||
|
||||
@@ -202,7 +209,7 @@ Create the following files inside the `.github/workflows` directory:
|
||||
>
|
||||
<TabPanel id="ci" label="ci.yaml">
|
||||
|
||||
```yaml title=.github/workflows/ci.yml
|
||||
```yaml .github/workflows/ci.yml
|
||||
name: CI
|
||||
|
||||
on:
|
||||
@@ -233,7 +240,7 @@ jobs:
|
||||
</TabPanel>
|
||||
<TabPanel id="staging" label="staging.yaml">
|
||||
|
||||
```yaml title=.github/workflows/staging.yml
|
||||
```yaml .github/workflows/staging.yml
|
||||
name: Deploy Migrations to Staging
|
||||
|
||||
on:
|
||||
@@ -264,7 +271,7 @@ jobs:
|
||||
</TabPanel>
|
||||
<TabPanel id="production" label="production.yaml">
|
||||
|
||||
```yaml title=.github/workflows/production.yml
|
||||
```yaml .github/workflows/production.yml
|
||||
name: Deploy Migrations to Production
|
||||
|
||||
on:
|
||||
|
||||
@@ -12,7 +12,7 @@ We can reference the environment variable by using the `env()` function.
|
||||
|
||||
Inside of our `.env` file we add the environment variable as we normally would
|
||||
|
||||
```env
|
||||
```bash
|
||||
GITHUB_CLIENT_ID=""
|
||||
GITHUB_SECRET=""
|
||||
```
|
||||
|
||||
@@ -160,7 +160,7 @@ returns:
|
||||
## Resources
|
||||
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [PostgreSQL Arrays](https://www.postgresql.org/docs/15/arrays.html)
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
@@ -3,20 +3,17 @@ import Layout from '~/layouts/DefaultGuideLayout'
|
||||
export const meta = {
|
||||
id: 'column-encryption',
|
||||
title: 'Column Encryption',
|
||||
description: 'Use Supabase to store and serve files.',
|
||||
description: 'Encrypt columns using Transparent Column Encryption.',
|
||||
subtitle: 'Encrypt columns using Transparent Column Encryption.',
|
||||
sidebar_label: 'Overview',
|
||||
video: 'https://www.youtube.com/v/J9mTPY8rIXE',
|
||||
}
|
||||
|
||||
Encrypted Columns for Tables
|
||||
Supabase provides a secure method for encrypting columns using [Vault](/docs/guides/database/vault), our Postgres secrets manager. Vault is Postgres extension with an integrated UI intended to act as a secure global secrets management for you project.
|
||||
|
||||
## Transparent Column Encryption (TCE)
|
||||
Vault enables an advanced feature called Transparent Column Encryption (TCE) which provides a safe way to encrypt your data so that it doesn't leak into logs and backups. It can also provide row-level authenticated encryption.
|
||||
|
||||
TCE provides a safe way to encrypt your data so that it doesn't leak into logs and backups. It can also provide row-level authenticated encryption.
|
||||
|
||||
TCE is the primary building block of [Vault](/docs/guides/database/vault), Supabase's Postgres secrets manager. Vault is a built-in table with an integrated UI intended to act as a secure global secrets management for you project. However if you need more fine-grain control over your encrypted data, such as encrypting columns in your own tables, you can use TCE directly. Any Postgres value that can be cast to `text` or `bytea` can be encrypted using TCE.
|
||||
|
||||
### Encrypting columns
|
||||
## Encrypting columns
|
||||
|
||||
When creating a new column in the Dashboard, you can choose to encrypt a `text` or `bytea` column. You will choose which key you would like to encrypt it with by selecting an existing key ID or creating a new one.
|
||||
|
||||
@@ -26,10 +23,50 @@ Once you've created an encrypted column, you can insert data into the table like
|
||||
|
||||

|
||||
|
||||
## Decrypting data
|
||||
|
||||
Decrypted data is accessed using a special view that is automatically created after adding an encrypted column to a table. This view decrypts the data row-by-row as you access it. By default, this view is called `decrypted_<your-table-name>`. In the example below, the decryption view for the `profiles` table is called `decrypted_profiles`. Notice there is a new column in the view called `decrypted_emails` that contains the decrypted email value.
|
||||
|
||||

|
||||
|
||||
## Using an Encrypted Table
|
||||
|
||||
Now that you have TCE setup for a table, it's easy to use by simply inserting data into the table, and querying that data by looking at its generated view. The view is named `decrypted_<table_name>` and by default is in the same schema as your table:
|
||||
|
||||
```sql
|
||||
insert into secrets
|
||||
(secret, account_id)
|
||||
values
|
||||
('1234-5678-8765-4321', 123);
|
||||
```
|
||||
|
||||
Now that you have inserted data, look at the table and notice how the secret is encrypted. This is the data that is stored on disk, the encrypted card number, the key id, and the account id, **but the key itself is not stored**. This means if someone gets a backup or dump of your database, they cannot decrypt the secret, they do not have the key, only the key ID:
|
||||
|
||||
```sql
|
||||
> select * from secrets where account_id = 123;
|
||||
-[ RECORD 1 ]------+---------------------------------------------------------------------
|
||||
id | 1
|
||||
secret | jf8KfImkKTr+j4gzyDZQtLDEFL9eSlFuKjNlNEJvDg+OIKUr2wjF/8NnYcLisb5F9xiN
|
||||
account_id | 123
|
||||
key_id | 7f753c4f-8c68-457a-8801-1798b2e9f44d
|
||||
nonce | \x300a14aa721184ff7cf0f6bf088da267
|
||||
```
|
||||
|
||||
For you, the developer, you need the unencrypted secret for you application. No problem, you can access that data using the dynamically generated decryption view `decrypted_secrets`:
|
||||
|
||||
```sql
|
||||
> select * from decrypted_secrets where account_id = 123;
|
||||
-[ RECORD 1 ]----------------+---------------------------------------------------------------------
|
||||
id | 1
|
||||
secret | jf8KfImkKTr+j4gzyDZQtLDEFL9eSlFuKjNlNEJvDg+OIKUr2wjF/8NnYcLisb5F9xiN
|
||||
decrypted_secret | 1234-5678-8765-4321
|
||||
account_id | 123
|
||||
key_id | 7f753c4f-8c68-457a-8801-1798b2e9f44d
|
||||
nonce | \x300a14aa721184ff7cf0f6bf088da267
|
||||
```
|
||||
|
||||
Notice how there is a new column called `decrypted_secret`. This column is not stored in database or on disk at all, it is generated “on-the-fly” as you select from the view. Database dumps do not contain this information, only the view itself, and most importantly, **raw decryption keys are never stored**.
|
||||
|
||||
## How Key Derivation Works
|
||||
|
||||
The current state-of-the-art in encryption libraries is [libsodium](https://doc.libsodium.org/).
|
||||
@@ -202,43 +239,7 @@ security label for pgsodium
|
||||
|
||||
The new label indicates which column is to be associated with the secret, and that's it! Your `account_id` and secret are now protected under the same authentication signature as the secret itself.
|
||||
|
||||
## Using an Encrypted Table
|
||||
|
||||
Now that you have TCE setup for a table, it's easy to use by simply inserting data into the table, and querying that data by looking at its generated view. The view is named `decrypted_<table_name>` and by default is in the same schema as your table:
|
||||
|
||||
```sql
|
||||
insert into secrets
|
||||
(secret, account_id)
|
||||
values
|
||||
('1234-5678-8765-4321', 123);
|
||||
```
|
||||
|
||||
Now that you have inserted data, look at the table and notice how the secret is encrypted. This is the data that is stored on disk, the encrypted card number, the key id, and the account id, **but the key itself is not stored**. This means if someone gets a backup or dump of your database, they cannot decrypt the secret, they do not have the key, only the key ID:
|
||||
|
||||
```sql
|
||||
> select * from secrets where account_id = 123;
|
||||
-[ RECORD 1 ]------+---------------------------------------------------------------------
|
||||
id | 1
|
||||
secret | jf8KfImkKTr+j4gzyDZQtLDEFL9eSlFuKjNlNEJvDg+OIKUr2wjF/8NnYcLisb5F9xiN
|
||||
account_id | 123
|
||||
key_id | 7f753c4f-8c68-457a-8801-1798b2e9f44d
|
||||
nonce | \x300a14aa721184ff7cf0f6bf088da267
|
||||
```
|
||||
|
||||
For you, the developer, you need the unencrypted secret for you application. No problem, you can access that data using the dynamically generated decryption view `decrypted_secrets`:
|
||||
|
||||
```sql
|
||||
> select * from decrypted_secrets where account_id = 123;
|
||||
-[ RECORD 1 ]----------------+---------------------------------------------------------------------
|
||||
id | 1
|
||||
secret | jf8KfImkKTr+j4gzyDZQtLDEFL9eSlFuKjNlNEJvDg+OIKUr2wjF/8NnYcLisb5F9xiN
|
||||
decrypted_secret | 1234-5678-8765-4321
|
||||
account_id | 123
|
||||
key_id | 7f753c4f-8c68-457a-8801-1798b2e9f44d
|
||||
nonce | \x300a14aa721184ff7cf0f6bf088da267
|
||||
```
|
||||
|
||||
Notice how there is a new column called `decrypted_secret`. This column is not stored in database or on disk at all, it is generated “on-the-fly” as you select from the view. Database dumps do not contain this information, only the view itself, and most importantly, **raw decryption keys are never stored**.
|
||||
## Resources
|
||||
|
||||
- [Supabase Vault](/docs/guides/database/vault)
|
||||
- Read more about Supabase Vault in the [blog post](https://supabase.com/blog/vault-now-in-beta)
|
||||
|
||||
@@ -1,61 +1,29 @@
|
||||
import Layout from '~/layouts/DefaultGuideLayout'
|
||||
import StepHikeCompact from '~/components/StepHikeCompact'
|
||||
|
||||
export const meta = {
|
||||
id: 'connecting-to-postgres',
|
||||
title: 'Database Connections',
|
||||
description: 'There are various ways to connect to your Postgres database.',
|
||||
title: 'Connecting to your database',
|
||||
description: 'Explore the options for connecting to your Postgres database.',
|
||||
}
|
||||
|
||||
Supabase provides several options for programmatically connecting to your Postgres database:
|
||||
|
||||
## Types of Connection
|
||||
1. Direct connections using Postgres' standard connection system
|
||||
2. Connection pooling using PgBouncer
|
||||
3. Programmatic access uing the [Serverless APIs](/docs/guides/api)
|
||||
|
||||
- HTTP connections using the API.
|
||||
- Direct connections using Postgres' standard connection system.
|
||||
- Connection pooling using PgBouncer.
|
||||
## Serverless APIs
|
||||
|
||||
### Direct vs Pooling vs API
|
||||
|
||||
- A "direct connection" is when a connection is made to the database using Postgres' native connection implementation. You should use this for tools which are always alive - usually installed on a long-running server.
|
||||
- A "connection pool" is a system (external to Postgres) which keeps connections "open". You should use this for serverless functions and tools which disconnect from the database frequently.
|
||||
- The API is an auto-generated REST interface. You should use this for all browser and application interactions. The API server internally handles a connection pool.
|
||||
|
||||
Why would you use a connection pool? Primarily because the way that Postgres handles connections isn't very scalable for a large number of _temporary_ connections.
|
||||
You can use these simple questions to determine which connection method to use:
|
||||
|
||||
- Are you connecting to a database and _maintaining_ a connection? If yes, use a direct connection.
|
||||
- Are you connecting to your database and then _disconnecting_ immediately (e.g. a serverless environment)? If yes, use a connection pool.
|
||||
|
||||
## API
|
||||
|
||||
Supabase provides an auto-updating [API](/docs/guides/database/api). This is the easiest way to get started if you are managing data (fetching, inserting, updating).
|
||||
|
||||
### Interfaces
|
||||
|
||||
We provides several types of API to suit your preferences and use-case:
|
||||
Supabase provides auto-updating [APIs](/docs/guides/database/api). This is the easiest way to get started if you are managing data (fetching, inserting, updating). We provides several types of API to suit your preferences:
|
||||
|
||||
- [REST](/docs/guides/database/api#rest-api): interact with your database through a REST interface.
|
||||
- [GraphQL](/docs/guides/database/api#graphql-api): interact with your database through a GraphQL interface.
|
||||
- [Realtime](/docs/guides/database/api#realtime-api): listen to database changes over websockets.
|
||||
|
||||
You cannot manage the database schema via the API (for security reasons). To do that you can use the dashboard or connect directly to your database.
|
||||
|
||||
### API URL and Keys
|
||||
|
||||
You can find the API URL and Keys in the [Dashboard](https://app.supabase.com/project/_/settings/api).
|
||||
|
||||
<video width="99%" muted playsInline controls={true}>
|
||||
<source
|
||||
src="https://xguihxuzqibwxjnimxev.supabase.co/storage/v1/object/public/videos/docs/api/api-url-and-key.mp4"
|
||||
type="video/mp4"
|
||||
/>
|
||||
</video>
|
||||
|
||||
## Direct connections
|
||||
|
||||
Every Supabase project provides a full Postgres database. You can connect to the database using any tool which supports Postgres.
|
||||
|
||||
### Finding your connection string
|
||||
Every Supabase project provides a full Postgres database. You can connect to the database using [any tool which supports Postgres](#integrations). You can find the connection string in the [Database settings](https://app.supabase.com/project/_/settings/database) inside the dashboard:
|
||||
|
||||
1. Go to the `Settings` section.
|
||||
2. Click `Database`.
|
||||
@@ -68,42 +36,9 @@ Every Supabase project provides a full Postgres database. You can connect to the
|
||||
/>
|
||||
</video>
|
||||
|
||||
## Connection Pool
|
||||
## Connection Pooler
|
||||
|
||||
Connection pools are useful for managing a large number of _temporary_ connections. For example, if you are using [Prisma](/docs/guides/integrations/prisma) deployed to a Serverless environment.
|
||||
|
||||
### How connection pooling works
|
||||
|
||||
A "connection pool" is a system (external to Postgres) which manages connections, rather than PostgreSQL's native system. Supabase uses [PgBouncer](https://www.pgbouncer.org/) for connection pooling.
|
||||
|
||||
When a client makes a request, PgBouncer "allocates" an available connection to the client.
|
||||
When the client transaction or session is completed the connection is returned to the pool and is free to be used by another client.
|
||||
|
||||

|
||||
|
||||
### Pool modes
|
||||
|
||||
Pool Mode determines how PgBouncer handles a connection.
|
||||
|
||||
#### Session
|
||||
|
||||
When a new client connects, a connection is assigned to the client until it disconnects. Afterward, the connection is returned back to the pool.
|
||||
|
||||
All PostgreSQL features can be used with this option.
|
||||
|
||||
#### Transaction
|
||||
|
||||
This is the suggested option for serverless functions. A connection is only assigned to the client for the duration of a transaction. Two consecutive transactions from the same client
|
||||
could be executed over two different connections.
|
||||
|
||||
Some session-based PostgreSQL features such as prepared statements are not available with this option.
|
||||
A comprehensive list of incompatible features can be found [here](https://www.pgbouncer.org/features.html).
|
||||
|
||||
#### Statement
|
||||
|
||||
This is the most granular option. Connections are returned to the pool after every statement. Transactions with multiple statements are not allowed. This is best used when `AUTOCOMMIT` is in use.
|
||||
|
||||
### Finding the connection pool config
|
||||
Every Supabase project comes with PgBouncer for connection pooling. A connection pooler is useful for managing a large number of _temporary_ connections. For example, if you are using [Prisma](/docs/guides/integrations/prisma), Drizzle, Kysely, or anything deployed to a Serverless environment (AWS Lambdas or Edge Functions). You can find the connection pool config in the [Database settings](https://app.supabase.com/project/_/settings/database) inside the dashboard:
|
||||
|
||||
1. Go to the `Settings` section.
|
||||
2. Click `Database`.
|
||||
@@ -116,34 +51,290 @@ This is the most granular option. Connections are returned to the pool after eve
|
||||
/>
|
||||
</video>
|
||||
|
||||
## Choosing a connection method
|
||||
|
||||
- The Serverless APIs provide programmatic access and have built-in connection pooling. You can use these for all browser and application interactions. We recommend using these wherever possible.
|
||||
- A "direct connection" is Postgres' native connection system. You should use this for tools which are always alive - usually installed on a long-running server, like Node.js, Ruby, Python, etc.
|
||||
- A "connection pooler" is a tool which keeps connections "alive". You should use this for serverless functions and tools which disconnect from the database frequently, like Prisma, Drizzle, Kysely, etc.
|
||||
|
||||
Why would you use a connection pool? Primarily because the way that Postgres handles connections isn't very scalable for a large number of _temporary_ connections. You can use these simple questions to determine which connection method to use:
|
||||
|
||||
- Are you connecting to a database and _maintaining_ a connection? If yes, use a direct connection.
|
||||
- Are you connecting to your database and then _disconnecting_ immediately (e.g. a serverless environment)? If yes, use a connection pool.
|
||||
|
||||
## Connecting with SSL
|
||||
|
||||
Use this when connecting to your database to prevent snooping and man-in-the-middle attacks.
|
||||
You should connect to your database using SSL wherever possible, to prevent snooping and man-in-the-middle attacks.
|
||||
|
||||
You can obtain your connection info and Server root certificate from your application's dashboard:
|
||||
|
||||
Obtain your connection info and Server root certificate from your application’s dashboard.
|
||||

|
||||
|
||||
Assuming you’ve downloaded your certificate and it’s located at `$HOME/Downloads/prod-ca-2021.cer`, and your Host address is `db.abcdefghijklm.supabase.co` you can connect to the DB with
|
||||
SSL enabled as illustrated below:
|
||||
## How connection pooling works
|
||||
|
||||
1. With `psql`
|
||||
A "connection pool" is a system (external to Postgres) which manages connections, rather than PostgreSQL's native system. Supabase uses [PgBouncer](https://www.pgbouncer.org/) for connection pooling.
|
||||
|
||||
```
|
||||
psql "sslmode=verify-full sslrootcert=$HOME/Downloads/prod-ca-2021.cer host=db.abcdefghijklm.supabase.co dbname=postgres user=postgres"
|
||||
When a client makes a request, PgBouncer "allocates" an available connection to the client. When the client transaction or session is completed the connection is returned to the pool and is free to be used by another client.
|
||||
|
||||

|
||||
|
||||
Pgbounce provides several Pool Modes, each handling connections differently:
|
||||
|
||||
#### Session
|
||||
|
||||
When a new client connects, a connection is assigned to the client until it disconnects. Afterward, the connection is returned back to the pool.
|
||||
|
||||
All PostgreSQL features can be used with this option.
|
||||
|
||||
#### Transaction
|
||||
|
||||
This is the suggested option for serverless functions. A connection is only assigned to the client for the duration of a transaction. Two consecutive transactions from the same client could be executed over two different connections.
|
||||
|
||||
Some session-based PostgreSQL features such as prepared statements are not available with this option. A comprehensive list of incompatible features can be found [here](https://www.pgbouncer.org/features.html).
|
||||
|
||||
#### Statement
|
||||
|
||||
This is the most granular option. Connections are returned to the pool after every statement. Transactions with multiple statements are not allowed. This is best used when `AUTOCOMMIT` is in use.
|
||||
|
||||
## Integrations
|
||||
|
||||
### Connecting with Drizzle
|
||||
|
||||
[Drizzle ORM](https://github.com/drizzle-team/drizzle-orm) is a TypeScript ORM for SQL databases designed with maximum type safety in mind. You can use their ORM to connect to your database.
|
||||
|
||||
<StepHikeCompact>
|
||||
|
||||
<StepHikeCompact.Step step={1}>
|
||||
|
||||
<StepHikeCompact.Details title="Install">
|
||||
|
||||
Install Drizzle and releated dependencies.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||
```shell
|
||||
npm i drizzle-orm postgres
|
||||
npm i -D drizzle-kit
|
||||
```
|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
<StepHikeCompact.Step step={2}>
|
||||
|
||||
<StepHikeCompact.Details title="Create your models">
|
||||
|
||||
Create a `schema.ts` file and define your models.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||
```ts
|
||||
import { pgTable, serial, text, varchar } from "drizzle-orm/pg-core";
|
||||
|
||||
export const users = pgTable('users', {
|
||||
id: serial('id').primaryKey(),
|
||||
fullName: text('full_name'),
|
||||
phone: varchar('phone', { length: 256 }),
|
||||
});
|
||||
```
|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
<StepHikeCompact.Step step={3}>
|
||||
|
||||
<StepHikeCompact.Details title="Connect">
|
||||
|
||||
Connect to your database using the Connection Pooler for serverless environments, and the Direct Connection for long-running servers.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||
```ts
|
||||
import { drizzle } from 'drizzle-orm/postgres-js'
|
||||
import postgres from 'postgres'
|
||||
import { users } from './schema'
|
||||
|
||||
const connectionString = process.env.DATABASE_URL
|
||||
const client = postgres(connectionString)
|
||||
const db = drizzle(client);
|
||||
|
||||
const allUsers = await db.select().from(users);
|
||||
```
|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
</StepHikeCompact>
|
||||
|
||||
### Connecting with pgAdmin
|
||||
|
||||
[`pgAdmin`](https://www.pgadmin.org/) is a GUI tool for managing Postgres databases. You can use it to connect to your database via SSL:
|
||||
|
||||
<StepHikeCompact>
|
||||
|
||||
<StepHikeCompact.Step step={1}>
|
||||
|
||||
<StepHikeCompact.Details title="Register">
|
||||
|
||||
Register a new Postgres server.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||

|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
<StepHikeCompact.Step step={2}>
|
||||
|
||||
<StepHikeCompact.Details title="Name">
|
||||
|
||||
Name your server.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||

|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
<StepHikeCompact.Step step={3}>
|
||||
|
||||
<StepHikeCompact.Details title="Connect">
|
||||
|
||||
Add the connection info. You can use the "Direct connection" config, which you can find in your Supabase dashboard.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||

|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
<StepHikeCompact.Step step={4}>
|
||||
|
||||
<StepHikeCompact.Details title="SSL">
|
||||
|
||||
Navigate to the SSL tab and change the SSL mode to Require. Next navigate to the Root certificate input, it will open up a file-picker modal. Select the certificate you downloaded from your Supabase dashboard and save the server details. PgAdmin should now be able to connect to your Postgres via SSL.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||

|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
</StepHikeCompact>
|
||||
|
||||
### Connecting with psql
|
||||
|
||||
[`psql`](https://www.postgresql.org/docs/current/app-psql.html) is a command-line tool that comes with Postgres.
|
||||
|
||||
Assuming you've downloaded your SSL certificate to `$HOME/Downloads/prod-supabase.cer`, and your host address is `db.ref.supabase.co` you connect to your database via SSL:
|
||||
|
||||
```shell
|
||||
psql "sslmode=verify-full sslrootcert=$HOME/Downloads/prod-supabase.cer host=db.ref.supabase.co dbname=postgres user=postgres"
|
||||
```
|
||||
|
||||
2. With `pgAdmin`
|
||||
a. Register a new Postgres server
|
||||

|
||||
### Connecting with Postgres.js
|
||||
|
||||
b. Name your server to your liking and add the connection info.
|
||||

|
||||

|
||||
[Postgres.js](https://github.com/porsager/postgres) is a full-featured PostgreSQL client for Node.js and Deno.
|
||||
|
||||
3. Navigate to the SSL tab and change the SSL mode to Require. Next navigate to the Root certificate input, it will open up a
|
||||
file-picker modal. Select the certificate you downloaded from your Supabase dashboard and save the server details. PgAdmin
|
||||
should now be able to connect to your Postgres via SSL.
|
||||

|
||||
<StepHikeCompact>
|
||||
|
||||
<StepHikeCompact.Step step={1}>
|
||||
|
||||
<StepHikeCompact.Details title="Install">
|
||||
|
||||
Install Drizzle and releated dependencies.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||
```shell
|
||||
npm i postgres
|
||||
npm i -D drizzle-kit
|
||||
```
|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
<StepHikeCompact.Step step={2}>
|
||||
|
||||
<StepHikeCompact.Details title="Connect">
|
||||
|
||||
Create a `db.js` file with the connection details. Use the Connection Pooler for serverless environments, and the Direct Connection for long-running servers.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||
```ts
|
||||
// db.js
|
||||
import postgres from 'postgres'
|
||||
|
||||
const connectionString = process.env.DATABASE_URL
|
||||
const sql = postgres(connectionString)
|
||||
|
||||
export default sql
|
||||
```
|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
<StepHikeCompact.Step step={3}>
|
||||
|
||||
<StepHikeCompact.Details title="Execute commands">
|
||||
|
||||
Use the connection to execute commands.
|
||||
|
||||
</StepHikeCompact.Details>
|
||||
|
||||
<StepHikeCompact.Code>
|
||||
|
||||
```ts
|
||||
import sql from './db.js'
|
||||
|
||||
async function getUsersOver(age) {
|
||||
const users = await sql`
|
||||
select name, age
|
||||
from users
|
||||
where age > ${ age }
|
||||
`
|
||||
// users = Result [{ name: "Walter", age: 80 }, { name: 'Murray', age: 68 }, ...]
|
||||
return users
|
||||
}
|
||||
```
|
||||
|
||||
</StepHikeCompact.Code>
|
||||
|
||||
</StepHikeCompact.Step>
|
||||
|
||||
</StepHikeCompact>
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
|
||||
@@ -9,6 +9,8 @@ export const meta = {
|
||||
|
||||
[pgvector](https://github.com/pgvector/pgvector/) is a PostgreSQL extension for vector similarity search. It can also be used for storing [embeddings](https://supabase.com/blog/openai-embeddings-postgres-vector).
|
||||
|
||||
Learn more about Supabase's [AI & Vector](/docs/guides/ai) offering.
|
||||
|
||||
## Concepts
|
||||
|
||||
### Vector similarity
|
||||
@@ -81,13 +83,14 @@ const embeddingResponse = await openai.createEmbedding({
|
||||
model: 'text-embedding-ada-002',
|
||||
input: body,
|
||||
})
|
||||
const [responseData] = embeddingResponse.data.data.
|
||||
|
||||
const [{ embedding }] = embeddingResponse.data.data
|
||||
|
||||
// Store the vector in Postgres
|
||||
const { data, error } = await supabase.from('posts').insert({
|
||||
title,
|
||||
body,
|
||||
embedding: responseData.embedding,
|
||||
embedding,
|
||||
})
|
||||
```
|
||||
|
||||
|
||||
@@ -226,7 +226,7 @@ final data = await supabase.rpc('nearby_restaurants',params: {
|
||||
|
||||

|
||||
|
||||
When you are working on a map-based application where the user scrolls through your map, you might want to load the that lies within the bounding box of the map every time your users scroll. PostGIS can return the rows that are within the bounding box just by supplying the bottom left and the top right coordinates. Let’s look at what the function would look like.
|
||||
When you are working on a map-based application where the user scrolls through your map, you might want to load the data that lies within the bounding box of the map every time your users scroll. PostGIS can return the rows that are within the bounding box just by supplying the bottom left and the top right coordinates. Let’s look at what the function would look like:
|
||||
|
||||
```sql
|
||||
create or replace function restaurants_in_view(min_lat float, min_long float, max_lat float, max_long float)
|
||||
@@ -235,14 +235,14 @@ language sql
|
||||
as $$
|
||||
select id, name, st_astext(location) as location
|
||||
from public.restaurants
|
||||
where location && ST_SetSRID(ST_MakeBox2D(ST_Point(min_long, min_lat), ST_Point(max_long, max_lat)),4326)
|
||||
where location && ST_SetSRID(ST_MakeBox2D(ST_Point(min_long, min_lat), ST_Point(max_long, max_lat)), 4326)
|
||||
$$;
|
||||
```
|
||||
|
||||
[`&&`](https://postgis.net/docs/geometry_overlaps.html) operator used in the `where` statement here returns a boolean of whether the bounding box of the two geometries intersect or not. We basically are creating a bounding box from the two points and finding those points that fall under the bounding box. We are also utilizing a few different PostGIS functions here.
|
||||
The [`&&`](https://postgis.net/docs/geometry_overlaps.html) operator used in the `where` statement here returns a boolean of whether the bounding box of the two geometries intersect or not. We are basically creating a bounding box from the two points and finding those points that fall under the bounding box. We are also utilizing a few different PostGIS functions:
|
||||
|
||||
- [ST_MakeBox2D](https://postgis.net/docs/ST_MakeBox2D.html): Creates a 2-dimensional box from two points.
|
||||
- [ST_SetSRID](https://postgis.net/docs/ST_SetSRID.html): Sets the [SRID](https://postgis.net/docs/manual-dev/using_postgis_dbmanagement.html#spatial_ref_sys), which is an identifier of what coordinate system to use, for the geometry. 4326 the standard longitude and latitude coordinate systems.
|
||||
- [ST_SetSRID](https://postgis.net/docs/ST_SetSRID.html): Sets the [SRID](https://postgis.net/docs/manual-dev/using_postgis_dbmanagement.html#spatial_ref_sys), which is an identifier of what coordinate system to use for the geometry. 4326 is the standard longitude and latitude coordinate system.
|
||||
|
||||
You can call this function from your client using `rpc()` like this:
|
||||
|
||||
|
||||
@@ -2,45 +2,36 @@ import Layout from '~/layouts/DefaultGuideLayout'
|
||||
|
||||
export const meta = {
|
||||
id: 'json',
|
||||
title: 'JSON',
|
||||
description: 'Using the JSON data type in PostgreSQL.',
|
||||
title: 'Managing JSON and unstructured data',
|
||||
description: 'Using the JSON data type in Postgres.',
|
||||
subtitle: 'Using the JSON data type in Postgres.',
|
||||
}
|
||||
|
||||
PostgreSQL supports [JSON functions and operators](https://www.postgresql.org/docs/current/functions-json.html) which gives flexibility when storing data inside a database column.
|
||||
Postgres supports storing and querying unstructured data.
|
||||
|
||||
PostgreSQL supports two types of JSON columns: `JSON` and `JSONB`.
|
||||
The recommended type is `JSONB` for almost all cases.
|
||||
When you use the `JSONB` format, the data is parsed when it's put into the database so it's faster when querying and also it can be indexed.
|
||||
## JSON vs JSONB
|
||||
|
||||
## Create a table with a JSON column
|
||||
Postgres supports two types of JSON columns: `json` (stored as a string) and `jsonb` (stored as a binary). The recommended type is `jsonb` for almost all cases.
|
||||
|
||||
- `json` stores an exact copy of the input text. Database functions must reparse the content on each execution.
|
||||
- `jsonb` stores database in a decomposed binary format. While this makes it slightly slower to input due to added conversion overhead, it is significantly faster to process, since no reparsing is needed.
|
||||
|
||||
## When to use JSON/JSONB
|
||||
|
||||
Generally you should use a `jsonb` column when you have data that is unstructured or has a variable schema. For example, if you wanted to store responses for various webhooks, you might not know the format of the response when creating the table. Instead, you could store the `payload` as a `jsonb` object in a single column.
|
||||
|
||||
Don't go overboard with `json/jsonb` columns. They are a useful tool, but most of the benefits of a relational database come from the ability to query and join structured data, and the referential integrity that brings.
|
||||
|
||||
## Create JSONB columns
|
||||
|
||||
`json/jsonb` is just another "data type" for Postgres columns. You can create a `jsonb` column in the same way you would create a `text` or `int` column:
|
||||
|
||||
<Tabs
|
||||
scrollable
|
||||
size="small"
|
||||
type="underlined"
|
||||
defaultActiveId="dashboard"
|
||||
defaultActiveId="sql"
|
||||
>
|
||||
<TabPanel id="dashboard" label="Dashboard">
|
||||
|
||||
1. Go to the [Table Editor](https://app.supabase.com/project/_/editor) page in the Dashboard.
|
||||
2. Click **New Table** and create a table called `books`.
|
||||
3. Include a primary key with the following properties:
|
||||
- Name: `id`
|
||||
- Type: `int8`
|
||||
- Default value: `Automatically generate as indentity`
|
||||
4. Click **Save**.
|
||||
5. Click **New Column** and add 3 columns with the following properties:
|
||||
- **title** column
|
||||
- Name: `title`
|
||||
- Type: `text`
|
||||
- **author** column
|
||||
- Name: `author`
|
||||
- Type: `text`
|
||||
- **metadata** column
|
||||
- Name: `metadata`
|
||||
- Type: `jsonb`
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="sql" label="SQL">
|
||||
|
||||
```sql
|
||||
@@ -52,32 +43,39 @@ create table books (
|
||||
);
|
||||
```
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="dashboard" label="Dashboard">
|
||||
|
||||
1. Go to the [Table Editor](https://app.supabase.com/project/_/editor) page in the Dashboard.
|
||||
2. Click **New Table** and create a table called `books`.
|
||||
3. Include a primary key with the following properties and click save:
|
||||
|
||||
- Name: `id`
|
||||
- Type: `int8`
|
||||
- Default value: `Automatically generate as indentity`
|
||||
- **title** column
|
||||
- Name: `title`
|
||||
- Type: `text`
|
||||
- **author** column
|
||||
- Name: `author`
|
||||
- Type: `text`
|
||||
- **metadata** column
|
||||
- Name: `metadata`
|
||||
- Type: `jsonb`
|
||||
|
||||
</TabPanel>
|
||||
</Tabs>
|
||||
|
||||
## Insert data into the table
|
||||
## Inserting JSON data
|
||||
|
||||
You can insert JSON data in the same way that you insert any other data. The data must be valid JSON.
|
||||
|
||||
<Tabs
|
||||
scrollable
|
||||
size="small"
|
||||
type="underlined"
|
||||
defaultActiveId="dashboard"
|
||||
defaultActiveId="sql"
|
||||
>
|
||||
<TabPanel id="dashboard" label="Dashboard">
|
||||
|
||||
1. Go to the [Table Editor](https://app.supabase.com/project/_/editor) page in the Dashboard.
|
||||
2. Select the `books` table in the sidebar.
|
||||
3. Click **+ Insert row** and add 5 rows with the following properties:
|
||||
|
||||
| id | title | author | metadata |
|
||||
| --- | ----------------------------------- | ---------------------- | --------------------------------------------------------------------------------------------------------------------- |
|
||||
| 1 | The Poky Little Puppy | Janette Sebring Lowrey | `json {"ages":[3,6],"price":5.95,"description":"Puppy is slower than other, bigger animals."}` |
|
||||
| 2 | The Tale of Peter Rabbit | Beatrix Potter | `json {"ages":[2,5],"price":4.49,"description":"Rabbit eats some vegetables."}` |
|
||||
| 3 | Tootle | Gertrude Crampton | `json {"ages":[2,5],"price":3.99,"description":"Little toy train has big dreams."}` |
|
||||
| 4 | Green Eggs and Ham | Dr. Seuss | `json {"ages":[4,8],"price":7.49,"description":"Sam has changing food preferences and eats unusually colored food."}` |
|
||||
| 5 | Harry Potter and the Goblet of Fire | J.K. Rowling | `json {"ages":[10,99],"price":24.95,"description":"Fourth year of school starts, big drama ensues."}` |
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="sql" label="SQL">
|
||||
|
||||
```sql
|
||||
@@ -111,6 +109,21 @@ values
|
||||
);
|
||||
```
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="dashboard" label="Dashboard">
|
||||
|
||||
1. Go to the [Table Editor](https://app.supabase.com/project/_/editor) page in the Dashboard.
|
||||
2. Select the `books` table in the sidebar.
|
||||
3. Click **+ Insert row** and add 5 rows with the following properties:
|
||||
|
||||
| id | title | author | metadata |
|
||||
| --- | ----------------------------------- | ---------------------- | --------------------------------------------------------------------------------------------------------------------- |
|
||||
| 1 | The Poky Little Puppy | Janette Sebring Lowrey | `json {"ages":[3,6],"price":5.95,"description":"Puppy is slower than other, bigger animals."}` |
|
||||
| 2 | The Tale of Peter Rabbit | Beatrix Potter | `json {"ages":[2,5],"price":4.49,"description":"Rabbit eats some vegetables."}` |
|
||||
| 3 | Tootle | Gertrude Crampton | `json {"ages":[2,5],"price":3.99,"description":"Little toy train has big dreams."}` |
|
||||
| 4 | Green Eggs and Ham | Dr. Seuss | `json {"ages":[4,8],"price":7.49,"description":"Sam has changing food preferences and eats unusually colored food."}` |
|
||||
| 5 | Harry Potter and the Goblet of Fire | J.K. Rowling | `json {"ages":[10,99],"price":24.95,"description":"Fourth year of school starts, big drama ensues."}` |
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
@@ -167,48 +180,11 @@ const { data, error } = await supabase.from('books').insert([
|
||||
</TabPanel>
|
||||
</Tabs>
|
||||
|
||||
## View the data
|
||||
## Query JSON data
|
||||
|
||||
<Tabs
|
||||
scrollable
|
||||
size="small"
|
||||
type="underlined"
|
||||
defaultActiveId="sql"
|
||||
>
|
||||
<TabPanel id="sql" label="SQL">
|
||||
Querying JSON data is similar to querying other data, with a few other features to access nested values.
|
||||
|
||||
```sql
|
||||
select *
|
||||
from books;
|
||||
```
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```js
|
||||
const { data, error } = await supabase.from('books').select('*')
|
||||
console.log(JSON.stringify(data, null, 2))
|
||||
```
|
||||
|
||||
</TabPanel>
|
||||
<TabPanel id="result" label="Result">
|
||||
|
||||
| id | title | author | metadata |
|
||||
| --- | ----------------------------------- | ---------------------- | --------------------------------------------------------------------------------------------------------------------- |
|
||||
| 1 | The Poky Little Puppy | Janette Sebring Lowrey | `json{"ages":[3,6],"price":5.95,"description":"Puppy is slower than other, bigger animals."}` |
|
||||
| 2 | The Tale of Peter Rabbit | Beatrix Potter | `json{"ages":[2,5],"price":4.49,"description":"Rabbit eats some vegetables."} ` |
|
||||
| 3 | Tootle | Gertrude Crampton | `json{"ages":[2,5],"price":3.99,"description":"Little toy train has big dreams."} ` |
|
||||
| 4 | Green Eggs and Ham | Dr. Seuss | `json{"ages":[4,8],"price":7.49,"description":"Sam has changing food preferences and eats unusually colored food."} ` |
|
||||
| 5 | Harry Potter and the Goblet of Fire | J.K. Rowling | `json{"ages":[10,99],"price":24.95,"description":"Fourth year of school starts, big drama ensues."} ` |
|
||||
|
||||
The data as it appears here has the `JSONB` fields in a different order than when inserted. As mentioned earlier, data is parsed as its inserted when using the JSONB format.
|
||||
|
||||
</TabPanel>
|
||||
</Tabs>
|
||||
|
||||
## Query the `JSONB` data
|
||||
|
||||
Select the title, description, price, and age range for each book.
|
||||
Postgres support a range of [JSON functions and operators](https://www.postgresql.org/docs/current/functions-json.html). For example, the `->` operator returns values as `jsonb` data. If you want the data returned as `text`, use the `->>` operator.
|
||||
|
||||
<Tabs
|
||||
scrollable
|
||||
@@ -221,7 +197,7 @@ Select the title, description, price, and age range for each book.
|
||||
```sql
|
||||
select
|
||||
title,
|
||||
metadata -> 'description' as description,
|
||||
metadata ->> 'description' as description, -- returned as text
|
||||
metadata -> 'price' as price,
|
||||
metadata -> 'ages' -> 0 as low_age,
|
||||
metadata -> 'ages' -> 1 as high_age
|
||||
@@ -232,12 +208,13 @@ from books;
|
||||
<TabPanel id="js" label="JavaScript">
|
||||
|
||||
```js
|
||||
const { data, error } = await supabase
|
||||
.from('books')
|
||||
.select(
|
||||
'title,description:metadata->description,price:metadata->price,low_age:metadata->ages->0,high_age:metadata->ages->1'
|
||||
)
|
||||
console.log(JSON.stringify(data, null, 2))
|
||||
const { data, error } = await supabase.from('books').select(`
|
||||
title,
|
||||
description: metadata->description,
|
||||
price: metadata->price,
|
||||
low_age: metadata->ages->0,
|
||||
high_age: metadata->ages->1
|
||||
`)
|
||||
```
|
||||
|
||||
</TabPanel>
|
||||
@@ -254,16 +231,42 @@ console.log(JSON.stringify(data, null, 2))
|
||||
</TabPanel>
|
||||
</Tabs>
|
||||
|
||||
Note that the `->` operator returns JSONB data. If you want TEXT/STRING data returned, use the `->>` operator.
|
||||
## Validating JSON data
|
||||
|
||||
- metadata -> 'description' (returns a JSON object)
|
||||
- metadata ->> 'description' (returns STRING/TEXT data)
|
||||
Supabase provides the [`pg_jsonschema` extension](/docs/guides/database/extensions/pg_jsonschema) that adds the ability to validate `json` and `jsonb` data types against [JSON Schema](https://json-schema.org/) documents.
|
||||
|
||||
Once you have enabled the extension, you can add a "check constraint" to your table to validate the JSON data:
|
||||
|
||||
```sql
|
||||
create table customers (
|
||||
id serial primary key,
|
||||
metadata json
|
||||
);
|
||||
|
||||
alter table customers
|
||||
add constriant check_metadata check (
|
||||
json_matches_schema(
|
||||
'{
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"tags": {
|
||||
"type": "array",
|
||||
"items": {
|
||||
"type": "string",
|
||||
"maxLength": 16
|
||||
}
|
||||
}
|
||||
}
|
||||
}',
|
||||
metadata
|
||||
)
|
||||
);
|
||||
```
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase JS Client](https://github.com/supabase/supabase-js)
|
||||
- [PostgreSQL: JSON Functions and Operators](https://www.postgresql.org/docs/12/functions-json.html)
|
||||
- [PostgreSQL JSON types](https://www.postgresql.org/docs/12/datatype-json.html)
|
||||
- [Postgres: JSON Functions and Operators](https://www.postgresql.org/docs/current/functions-json.html)
|
||||
- [Postgres JSON types](https://www.postgresql.org/docs/current/datatype-json.html)
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
|
||||
@@ -71,7 +71,7 @@ where team_id = 'NYM';
|
||||
```
|
||||
|
||||
```js
|
||||
const { data, error } = await supabase
|
||||
const { count, error } = await supabase
|
||||
.from('players')
|
||||
.select('*', { count: 'exact', head: true }) // exact, planned, or executed
|
||||
.eq('team_id', 'NYM')
|
||||
@@ -79,7 +79,7 @@ const { data, error } = await supabase
|
||||
|
||||
## Resources
|
||||
|
||||
- [Supabase Account - Free Tier OK](https://supabase.com)
|
||||
- [Supabase Account - Free Plan OK](https://supabase.com)
|
||||
- [Postgrest Operators](https://postgrest.org/en/stable/api.html#operators)
|
||||
- [Supabase API: JavaScript select](/docs/reference/javascript/select)
|
||||
- [Supabase API: JavaScript modifiers](/docs/reference/javascript/using-modifiers)
|
||||
|
||||
@@ -237,7 +237,7 @@ This loads data directly from a file into a table. There are several file format
|
||||
|
||||
For example, if you wanted to load a CSV file into your movies table:
|
||||
|
||||
```csv title=./movies.csv
|
||||
```text ./movies.csv
|
||||
"The Empire Strikes Back", "After the Rebels are brutally overpowered by the Empire on the ice planet Hoth, Luke Skywalker begins Jedi training with Yoda."
|
||||
"Return of the Jedi", "After a daring mission to rescue Han Solo from Jabba the Hutt, the Rebels dispatch to Endor to destroy the second Death Star."
|
||||
```
|
||||
@@ -345,7 +345,7 @@ create schema private;
|
||||
Now we can create tables inside the `private` schema:
|
||||
|
||||
```sql
|
||||
create table salaries (
|
||||
create table private.salaries (
|
||||
id bigint generated by default as identity primary key,
|
||||
salary bigint not null,
|
||||
actor_id bigint not null references public.actors
|
||||
|
||||
@@ -3,19 +3,15 @@ import Layout from '~/layouts/DefaultGuideLayout'
|
||||
export const meta = {
|
||||
id: 'vault',
|
||||
title: 'Vault',
|
||||
description: 'Use Supabase to store and serve files.',
|
||||
description:
|
||||
'Vault is a Postgres extension and accompanying Supabase UI that makes it safe and easy to store encrypted secrets.',
|
||||
subtitle: 'Managing secrets in Postgres.',
|
||||
sidebar_label: 'Overview',
|
||||
video: 'https://www.youtube.com/v/J9mTPY8rIXE',
|
||||
}
|
||||
|
||||
Supabase Vault provides encrypted secret storage and Encrypted Columns for Tables.
|
||||
|
||||
Vault is a Postgres extension and accompanying Supabase UI that makes it safe and easy to store encrypted secrets and other data in your database. This opens up a lot of possibilities to use Postgres in ways that go beyond what is available in a stock distribution.
|
||||
|
||||
From a product perspective, Supabase groups a number of related features under the “Vault banner”. Let's explore a few of these features.
|
||||
|
||||
## Secrets Management
|
||||
|
||||
Under the hood, the Vault is a table of Secrets and Encryption Keys that are stored using [Authenticated Encryption](https://en.wikipedia.org/wiki/Authenticated_encryption) on disk. They are then available in decrypted form through a Postgres view so that the secrets can be used by applications from SQL. Because the secrets are stored on disk encrypted and authenticated, any backups or replication streams also preserve this encryption in a way that can't be decrypted or forged.
|
||||
|
||||
Supabase provides a dashboard UI for the Vault that makes storing secrets easy. Click a button, type in your secret, and save. Optionally create your own keys you can use to encrypt your secret. Your secret will then be stored on disk encrypted using the specified key.
|
||||
@@ -31,79 +27,48 @@ Supabase provides a dashboard UI for the Vault that makes storing secrets easy.
|
||||
|
||||
There are two main parts to the Vault UI, Secrets and Encryption Keys:
|
||||
|
||||
- **Secrets:** Use the Vault to store Secrets - everything from Environment Variables to API Keys. You can use these Secrets anywhere in your database: Postgres [Functions](/docs/guides/database/functions), Triggers, and [Webhooks](/docs/guides/database/webhooks). From a SQL perspective, accessing secrets is as easy as querying a table (or in this case, a view). The underlying secrets tables will be stored in encrypted form.
|
||||
- **Encryption Keys:** These are keys used to encrypt data inside your database. You can create different Encryption Keys for different purposes, for example: one for encrypting user-data, and another for application-data. Each key is encrypted itself using a root encryption key that lives outside of the database. See **[Encryption key location](#encryption-key-location)** for more details.
|
||||
## Secrets
|
||||
|
||||
## Deep Dive on How The Vault works
|
||||
You can use the Vault to store secrets - everything from Environment Variables to API Keys. You can then use these secrets anywhere in your database: Postgres [Functions](/docs/guides/database/functions), Triggers, and [Webhooks](/docs/guides/database/webhooks). From a SQL perspective, accessing secrets is as easy as querying a table (or in this case, a view). The underlying secrets tables will be stored in encrypted form.
|
||||
|
||||
<div className="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/QHLPNDrdN2w"
|
||||
title="YouTube video player"
|
||||
frameborder="0"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowfullscreen
|
||||
></iframe>
|
||||
</div>
|
||||
## Encryption Keys
|
||||
|
||||
As we mentioned, the Vault uses pgsodium's Transparent Column Encryption (TCE) to store secrets in an authenticated encrypted form. There are some details around that you may be curious about, what does authenticated mean, and where are encryption keys store? This section explains those details.
|
||||
|
||||
### Authenticated Encryption with Associated Data
|
||||
|
||||
The first important feature of TCE is that it uses an [Authenticated Encryption with Associated Data](<https://en.wikipedia.org/wiki/Authenticated_encryption#Authenticated_encryption_with_associated_data_(AEAD)>) encryption algorithm (based on libsodium).
|
||||
|
||||
### Encryption key location
|
||||
|
||||
**Authenticated Encryption** means that in addition to the data being encrypted, it is also signed so that it cannot be forged. You can guarantee that the data was encrypted by someone you trust, which you wouldn't get with encryption alone. The decryption function verifies that the signature is valid _before decrypting the value_.
|
||||
|
||||
**Associated Data** means that you can include any other columns from the same row as part of the signature computation. This doesn't encrypt those other columns - rather it ensures that your encrypted value is only associated with columns from that row. If an attacker were to copy an encrypted value from another row to the current one, the signature would be rejected (assuming you used a unique column in the associated data).
|
||||
|
||||
Another important feature of pgsodium is that the encryption keys are never stored in the database alongside the encrypted data. Instead, only a **Key ID** is stored, which is a reference to the key that is only accessible outside of SQL. Even if an attacker can capture a dump of your entire database, they will see only encrypted data and key IDs, _never the raw key itself_.
|
||||
|
||||
This is an important safety precaution - there is little value in storing the encryption key in the database itself as this would be like locking your front door but leaving the key in the lock! Storing the key outside the database fixes this issue.
|
||||
|
||||
Where are the keys stored? Supabase creates and manages the root keys (from which all key IDs are derived) in our secured backend systems. We keep this root key safe and separate from your data. You remain in control of your keys - a separate API endpoint is available that you can use to access the key if you want to decrypt your data outside of Supabase.
|
||||
These are keys used to encrypt data inside your database. You can create different Encryption Keys for different purposes, for example: one for encrypting user-data, and another for application-data. Each key is encrypted itself using a root encryption key that lives outside of the database. See **[Encryption key location](#encryption-key-location)** for more details.
|
||||
|
||||
## Using the Vault
|
||||
|
||||
Using the vault is as simple as `INSERT`ing data into the
|
||||
`vault.secret` table.
|
||||
You can manage secrets and encryption keys from the UI or using SQL.
|
||||
|
||||
### Adding secrets
|
||||
|
||||
There is also a handy function for creating secrets called `vault.create_secret()`:
|
||||
|
||||
```sql
|
||||
postgres=> insert into vault.secrets (secret) values ('s3kre3t_k3y') returning *;
|
||||
-[ RECORD 1 ]-------------------------------------------------------------
|
||||
id | d91596b8-1047-446c-b9c0-66d98af6d001
|
||||
name |
|
||||
description |
|
||||
secret | S02eXS9BBY+kE3r621IS8beAytEEtj+dDHjs9/0AoMy7HTbog+ylxcS22A==
|
||||
key_id | 7f5ad44b-6bd5-4c99-9f68-4b6c7486f927
|
||||
nonce | \x3aa2e92f9808e496aa4163a59304b895
|
||||
created_at | 2022-12-14 02:29:21.3625+00
|
||||
updated_at | 2022-12-14 02:29:21.3625+00
|
||||
```
|
||||
|
||||
There is also a handy function for creating secrets called
|
||||
`vault.create_secret()`:
|
||||
|
||||
```sql
|
||||
postgres=> select vault.create_secret('another_s3kre3t');
|
||||
-[ RECORD 1 ]-+-------------------------------------
|
||||
create_secret | c9b00867-ca8b-44fc-a81d-d20b8169be17
|
||||
|
||||
select vault.create_secret('my_s3kre3t');
|
||||
```
|
||||
|
||||
The function returns the UUID of the new secret.
|
||||
|
||||
## Name and Description
|
||||
|
||||
Secrets can also have an optional _unique_ name, or an optional description. These are also arguments to `vault.create_secret()`:
|
||||
<details>
|
||||
<summary>Show Result</summary>
|
||||
|
||||
```sql
|
||||
postgres=> select vault.create_secret('another_s3kre3t', 'unique_name', 'This is the description');
|
||||
-[ RECORD 1 ]-+-------------------------------------
|
||||
create_secret | 7095d222-efe5-4cd5-b5c6-5755b451e223
|
||||
create_secret | c9b00867-ca8b-44fc-a81d-d20b8169be17
|
||||
```
|
||||
|
||||
postgres=> select * from vault.secrets where id = '7095d222-efe5-4cd5-b5c6-5755b451e223';
|
||||
</details>
|
||||
|
||||
Secrets can also have an optional _unique_ name and an optional description. These are also arguments to `vault.create_secret()`:
|
||||
|
||||
```sql
|
||||
select vault.create_secret('another_s3kre3t', 'unique_name', 'This is the description');
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>Show Result</summary>
|
||||
|
||||
```sql
|
||||
-[ RECORD 1 ]-----------------------------------------------------------------
|
||||
id | 7095d222-efe5-4cd5-b5c6-5755b451e223
|
||||
name | unique_name
|
||||
@@ -115,12 +80,49 @@ created_at | 2022-12-14 02:34:23.85159+00
|
||||
updated_at | 2022-12-14 02:34:23.85159+00
|
||||
```
|
||||
|
||||
## Querying Data from the Vault
|
||||
</details>
|
||||
|
||||
Alternatively, you can create a secret by `insert`ing data into the `vault.secret` table:
|
||||
|
||||
{/* prettier-ignore */}
|
||||
```sql
|
||||
insert into vault.secrets (secret)
|
||||
values ('s3kre3t_k3y') returning *;
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>Show Result</summary>
|
||||
|
||||
```sql
|
||||
-[ RECORD 1 ]-------------------------------------------------------------
|
||||
id | d91596b8-1047-446c-b9c0-66d98af6d001
|
||||
name |
|
||||
description |
|
||||
secret | S02eXS9BBY+kE3r621IS8beAytEEtj+dDHjs9/0AoMy7HTbog+ylxcS22A==
|
||||
key_id | 7f5ad44b-6bd5-4c99-9f68-4b6c7486f927
|
||||
nonce | \x3aa2e92f9808e496aa4163a59304b895
|
||||
created_at | 2022-12-14 02:29:21.3625+00
|
||||
updated_at | 2022-12-14 02:29:21.3625+00
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
### Viewing secrets
|
||||
|
||||
If you look in the `vault.secrets` table, you will see that your data is stored encrypted. To decrypt the data, there is an automatically created view `vault.decrypted_secrets`. This view will decrypt secret data on the fly:
|
||||
|
||||
{/* prettier-ignore */}
|
||||
```sql
|
||||
select *
|
||||
from vault.decrypted_secrets
|
||||
order by created_at desc
|
||||
limit 3;
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>Show Result</summary>
|
||||
|
||||
```sql
|
||||
postgres=> select * from vault.decrypted_secrets order by created_at desc limit 3;
|
||||
-[ RECORD 1 ]----+-----------------------------------------------------------------
|
||||
id | 7095d222-efe5-4cd5-b5c6-5755b451e223
|
||||
name | unique_name
|
||||
@@ -153,17 +155,30 @@ created_at | 2022-12-14 02:29:21.3625+00
|
||||
updated_at | 2022-12-14 02:29:21.3625+00
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
Notice how this view has a `decrypted_secret` column that contains the decrypted secrets. Views are not stored on disk, they are only run at query time, so the secret remains encrypted on disk, and in any backup dumps or replication streams.
|
||||
|
||||
You should ensure that you protect access to this view with the appropriate SQL privilege settings at all times, as anyone that has access to the view has access to decrypted secrets.
|
||||
|
||||
## Updating Secrets
|
||||
### Updating Secrets
|
||||
|
||||
A secret can be updated with the `vault.update_secret()` function, this function makes updating secrets easy, just provide the secret UUID as the first argument, and then an updated secret, updated optional unique name, or updated description:
|
||||
|
||||
```sql
|
||||
postgres=> select vault.update_secret('7095d222-efe5-4cd5-b5c6-5755b451e223', 'n3w_upd@ted_s3kret',
|
||||
'updated_unique_name', 'This is the updated description');
|
||||
select
|
||||
vault.update_secret(
|
||||
'7095d222-efe5-4cd5-b5c6-5755b451e223',
|
||||
'n3w_upd@ted_s3kret',
|
||||
'updated_unique_name',
|
||||
'This is the updated description'
|
||||
);
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>Show Result</summary>
|
||||
|
||||
```sql
|
||||
-[ RECORD 1 ]-+-
|
||||
update_secret |
|
||||
|
||||
@@ -180,36 +195,64 @@ created_at | 2022-12-14 02:34:23.85159+00
|
||||
updated_at | 2022-12-14 02:51:13.938396+00
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
## Deep Dive on How The Vault works
|
||||
|
||||
<div className="video-container">
|
||||
<iframe
|
||||
src="https://www.youtube-nocookie.com/embed/QHLPNDrdN2w"
|
||||
title="YouTube video player"
|
||||
frameborder="0"
|
||||
allow="accelerometer; autoplay; clipboard-write; encrypted-media; gyroscope; picture-in-picture"
|
||||
allowfullscreen
|
||||
></iframe>
|
||||
</div>
|
||||
|
||||
As we mentioned, the Vault uses pgsodium's Transparent Column Encryption (TCE) to store secrets in an authenticated encrypted form. There are some details around that you may be curious about, what does authenticated mean, and where are encryption keys store? This section explains those details.
|
||||
|
||||
### Authenticated Encryption with Associated Data
|
||||
|
||||
The first important feature of TCE is that it uses an [Authenticated Encryption with Associated Data](<https://en.wikipedia.org/wiki/Authenticated_encryption#Authenticated_encryption_with_associated_data_(AEAD)>) encryption algorithm (based on libsodium).
|
||||
|
||||
### Encryption key location
|
||||
|
||||
**Authenticated Encryption** means that in addition to the data being encrypted, it is also signed so that it cannot be forged. You can guarantee that the data was encrypted by someone you trust, which you wouldn't get with encryption alone. The decryption function verifies that the signature is valid _before decrypting the value_.
|
||||
|
||||
**Associated Data** means that you can include any other columns from the same row as part of the signature computation. This doesn't encrypt those other columns - rather it ensures that your encrypted value is only associated with columns from that row. If an attacker were to copy an encrypted value from another row to the current one, the signature would be rejected (assuming you used a unique column in the associated data).
|
||||
|
||||
Another important feature of pgsodium is that the encryption keys are never stored in the database alongside the encrypted data. Instead, only a **Key ID** is stored, which is a reference to the key that is only accessible outside of SQL. Even if an attacker can capture a dump of your entire database, they will see only encrypted data and key IDs, _never the raw key itself_.
|
||||
|
||||
This is an important safety precaution - there is little value in storing the encryption key in the database itself as this would be like locking your front door but leaving the key in the lock! Storing the key outside the database fixes this issue.
|
||||
|
||||
Where are the keys stored? Supabase creates and manages the root keys (from which all key IDs are derived) in our secured backend systems. We keep this root key safe and separate from your data. You remain in control of your keys - a separate API endpoint is available that you can use to access the key if you want to decrypt your data outside of Supabase.
|
||||
|
||||
## Internal Details
|
||||
|
||||
To encrypt data, you need a _key id_. You can use the default key id created automatically for every project, or create your own key ids Using the `pgsodium.create_key()` function. Key ids are used to internally derive the encryption key used to encrypt secrets in the vault. Vault users typically do not have access to the key itself, only the key id.
|
||||
|
||||
Both `vault.create_secret()` and `vault.update_secret()` take an optional fourth `new_key_id` argument. This argument can be used to store a different key id for the secret instead of the default value.
|
||||
|
||||
{/* prettier-ignore */}
|
||||
```sql
|
||||
postgres=> select vault.create_secret('another_s3kre3t_key', 'another_unique_name',
|
||||
'This is another description', (pgsodium.create_key()).id);
|
||||
select vault.create_secret(
|
||||
'another_s3kre3t_key',
|
||||
'another_unique_name',
|
||||
'This is another description',
|
||||
(pgsodium.create_key()).id
|
||||
);
|
||||
```
|
||||
|
||||
Result:
|
||||
|
||||
```sh
|
||||
-[ RECORD 1 ]-+-------------------------------------
|
||||
create_secret | cec9e005-a44d-4b19-86e1-febf3cd40619
|
||||
```
|
||||
|
||||
Which roles should have access to the `vault.secrets` table should be carefully considered. There are two ways to grant access, the first is that the `postgres` user can explicitly grant access to the vault table itself.
|
||||
|
||||
## Turning off Statement Logging
|
||||
|
||||
When you insert secrets into the vault table with an INSERT statement, those statements get logged by default into the Supabase logs. Since this would mean your secrets are stored unencrypted in the logs, you should turn off statement logging while using the Vault.
|
||||
|
||||
While turning off statement logging does hinder you if you're used to looking at the logs to debug your application, it provides a much higher level of security by ensuring that your data does not leak out of the database and into the logs. This is especially critical with encrypted column data, because the statement logs will contain the _unencrypted_ secrets. If you _must_ store that data encrypted, then you _must_ turn off statement logging.
|
||||
|
||||
```sql
|
||||
alter system set statement_log = 'none';
|
||||
```
|
||||
|
||||
And then restart your project from the dashboard to enable that change.
|
||||
|
||||
In the future we are researching various ways to refine the way statement logging interacts with sensitive columns.
|
||||
|
||||
## See also
|
||||
### Resources
|
||||
|
||||
- Read more about Supabase Vault in the [blog post](https://supabase.com/blog/vault-now-in-beta)
|
||||
- [Supabase Vault on GitHub](https://github.com/supabase/vault)
|
||||
|
||||
@@ -116,12 +116,12 @@ export const examples = [
|
||||
{
|
||||
name: 'Hugging Face',
|
||||
description: `Access 100,000+ Machine Learning models.`,
|
||||
href: '/guides/functions/examples/huggingface-image-captioning',
|
||||
href: '/guides/ai/examples/huggingface-image-captioning',
|
||||
},
|
||||
{
|
||||
name: 'OpenAI',
|
||||
description: `Using OpenAI in Edge Functions.`,
|
||||
href: '/guides/functions/examples/openai',
|
||||
href: '/guides/ai/examples/openai',
|
||||
},
|
||||
{
|
||||
name: 'Stripe Webhooks',
|
||||
@@ -165,7 +165,7 @@ export const examples = [
|
||||
},
|
||||
{
|
||||
name: 'Rate Limiting',
|
||||
description: `Rate Limiting Egde Functions with Upstash Redis.`,
|
||||
description: `Rate Limiting Edge Functions with Upstash Redis.`,
|
||||
href: '/guides/functions/examples/rate-limiting',
|
||||
},
|
||||
]
|
||||
|
||||
@@ -19,7 +19,7 @@ By creating a supabase client with the auth context from the function, you can d
|
||||
1. Get the user object.
|
||||
2. Run queries in the context of the user with [Row Level Security (RLS)](/docs/guides/auth/row-level-security) policies enforced.
|
||||
|
||||
```js lines=14,17-19,22-23 title=supabase/functions/select-from-table-with-auth-rls/index.ts
|
||||
```js mark=14,17:19,22:23 supabase/functions/select-from-table-with-auth-rls/index.ts
|
||||
import { serve } from 'https://deno.land/std@0.177.0/http/server.ts'
|
||||
import { createClient } from 'https://esm.sh/@supabase/supabase-js@2'
|
||||
|
||||
|
||||
@@ -24,16 +24,25 @@ jobs:
|
||||
|
||||
env:
|
||||
SUPABASE_ACCESS_TOKEN: ${{ secrets.SUPABASE_ACCESS_TOKEN }}
|
||||
PROJECT_ID: zdtdtxajzydjqzuktnqx
|
||||
PROJECT_ID: your-project-id
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v3
|
||||
|
||||
- uses: supabase/setup-cli@v1
|
||||
with:
|
||||
version: 1.0.0
|
||||
version: latest
|
||||
|
||||
- run: supabase functions deploy your-function-name --project-ref $PROJECT_ID
|
||||
- run: supabase functions deploy --project-ref $PROJECT_ID
|
||||
```
|
||||
|
||||
Since Supabase CLI [v1.62.0](https://github.com/supabase/cli/releases/tag/v1.62.0) you can deploy all functions with a single command.
|
||||
|
||||
Individual function configuration like [JWT verification](/docs/reference/cli/config#functions.function_name.verify_jwt) and [import map location](/docs/reference/cli/config#functions.function_name.import_map) can be set via the `config.toml` file.
|
||||
|
||||
```toml
|
||||
[functions.hello-world]
|
||||
verify_jwt = false
|
||||
```
|
||||
|
||||
<div class="video-container">
|
||||
|
||||
@@ -40,9 +40,18 @@ jobs:
|
||||
|
||||
- uses: supabase/setup-cli@v1
|
||||
with:
|
||||
version: 1.0.0
|
||||
version: latest
|
||||
|
||||
- run: supabase functions deploy github-action-deploy --project-ref $PROJECT_ID
|
||||
- run: supabase functions deploy --project-ref $PROJECT_ID
|
||||
```
|
||||
|
||||
Since Supabase CLI [v1.62.0](https://github.com/supabase/cli/releases/tag/v1.62.0) you can deploy all functions with a single command.
|
||||
|
||||
Individual function configuration like [JWT verification](/docs/reference/cli/config#functions.function_name.verify_jwt) and [import map location](/docs/reference/cli/config#functions.function_name.import_map) can be set via the `config.toml` file.
|
||||
|
||||
```toml
|
||||
[functions.hello-world]
|
||||
verify_jwt = false
|
||||
```
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
@@ -26,7 +26,7 @@ Find the example on [GitHub](https://github.com/supabase/supabase/tree/master/ex
|
||||
|
||||
Get your database connection credentials from your [Supabase Dashboard](https://app.supabase.com/project/_/settings/database) and store them in an `.env` file:
|
||||
|
||||
```txt .env
|
||||
```bash .env
|
||||
DB_HOSTNAME=
|
||||
DB_PASSWORD=
|
||||
DB_SSL_CERT="-----BEGIN CERTIFICATE-----
|
||||
|
||||
@@ -41,6 +41,8 @@ This creates a function stub in your `supabase` folder at `./functions/hello-wor
|
||||
|
||||
## Deploy to production
|
||||
|
||||
### Deploy a specific function
|
||||
|
||||
```bash
|
||||
supabase functions deploy hello-world
|
||||
```
|
||||
@@ -56,6 +58,21 @@ If you want to use Edge Functions to handle webhooks (e.g. [Stripe payment webho
|
||||
|
||||
</Admonition>
|
||||
|
||||
### Deploy all functions
|
||||
|
||||
```bash
|
||||
supabase functions deploy
|
||||
```
|
||||
|
||||
Since Supabase CLI [v1.62.0](https://github.com/supabase/cli/releases/tag/v1.62.0) you can deploy all functions with a single command. This is useful for example when [deploying with GitHub Actions](/docs/guides/functions/cicd-workflow).
|
||||
|
||||
Individual function configuration like [JWT verification](/docs/reference/cli/config#functions.function_name.verify_jwt) and [import map location](/docs/reference/cli/config#functions.function_name.import_map) can be set via the `config.toml` file.
|
||||
|
||||
```toml
|
||||
[functions.hello-world]
|
||||
verify_jwt = false
|
||||
```
|
||||
|
||||
## Invoking remote functions
|
||||
|
||||
You can invoke Edge Functions using curl:
|
||||
@@ -115,7 +132,7 @@ In a given workspace (or workspace folder), sub-paths can be enabled for Deno, w
|
||||
|
||||
For example if you have a project like this:
|
||||
|
||||
```txt
|
||||
```
|
||||
project
|
||||
├── app
|
||||
└── supabase
|
||||
@@ -184,7 +201,7 @@ For use-cases which require low-latency we recommend [Edge Functions](/docs/guid
|
||||
|
||||
We recommend developing “fat functions”. This means that you should develop few large functions, rather than many small functions. One common pattern when developing Functions is that you need to share code between two or more Functions. To do this, you can store any shared code in a folder prefixed with an underscore (`_`). We recommend this folder structure:
|
||||
|
||||
```txt
|
||||
```bash
|
||||
└── supabase
|
||||
├── functions
|
||||
│ ├── import_map.json # A top-level import map to use across functions.
|
||||
|
||||
@@ -30,7 +30,7 @@ as TypeScript continued to evolve, would be breaking changes for existing code.
|
||||
## Mixing JavaScript and TypeScript
|
||||
|
||||
By default, Deno does not type check JavaScript. This can be changed, and is
|
||||
discussed further in [Configuring TypeScript in Deno](./configuration.md). Deno
|
||||
discussed further in [Configuring TypeScript in Deno](https://deno.com/manual/advanced/typescript/configuration). Deno
|
||||
does support JavaScript importing TypeScript and TypeScript importing
|
||||
JavaScript, in complex scenarios.
|
||||
|
||||
@@ -39,7 +39,7 @@ will "read" all the JavaScript in order to be able to evaluate how it might have
|
||||
an impact on the TypeScript types. The type checker will do the best it can to
|
||||
figure out what the types are of the JavaScript you import into TypeScript,
|
||||
including reading any JSDoc comments. Details of this are discussed in detail in
|
||||
the [Types and type declarations](./types.md) section.
|
||||
the [Types and type declarations](https://deno.com/manual/advanced/typescript/types) section.
|
||||
|
||||
## Type resolution
|
||||
|
||||
@@ -47,7 +47,7 @@ One of the core design principles of Deno is to avoid non-standard module
|
||||
resolution, and this applies to type resolution as well. If you want to utilize
|
||||
JavaScript that has type definitions (e.g. a `.d.ts` file), you have to
|
||||
explicitly tell Deno about this. The details of how this is accomplished are
|
||||
covered in the [Types and type declarations](https://deno.land/manual/advanced/typescript/types) section.
|
||||
covered in the [Types and type declarations](https://deno.com/manual/advanced/typescript/types) section.
|
||||
|
||||
export const Page = ({ children }) => <Layout meta={meta} children={children} />
|
||||
|
||||
|
||||
@@ -102,9 +102,9 @@ export const meta = {
|
||||
|
||||
export const useCases = [
|
||||
{
|
||||
title: 'OpenAI Vector Search',
|
||||
href: '/guides/getting-started/openai/vector-search',
|
||||
description: `Build your own custom ChatGPT with Next.js, OpenAI and pg_vector.`,
|
||||
title: 'AI, Vectors, and embeddings',
|
||||
href: '/docs/guides/ai#examples',
|
||||
description: `Build AI-enabled applications using our Vector toolkit.`,
|
||||
icon: '/docs/img/icons/openai_logo',
|
||||
},
|
||||
{
|
||||
|
||||
Loaded 100 of 596 files, more files were not shown because too many files have changed in this diff.
Show more
Reference in new issue
Block a user