Commit Graph
19 Commits
Author SHA1 Message Date
Rounak Datta 7688bf9182 WhatsApp document loader - update regex (#2776)
I was testing out the WhatsApp Document loader, and noticed that
sometimes the date is of the following format (notice the additional
underscore):
```
3/24/23, 1:54_PM - +91 99999 99999 joined using this group's invite link
3/24/23, 6:29_PM - +91 99999 99999: When are we starting then?
```

Wierdly, the underscore is visible in Vim, but not on editors like
VSCode. I presume it is some unusual character/line terminator.
Nevertheless, I think handling this edge case will make the document
loader more robust.
2023-04-13 09:48:32 -07:00
vowelparrot 2db9b7a45d Revert "Add Slack Directory Loader (#2835)" (#2839)
This reverts commit a6f767ae7a.

To fix the linting error.
2023-04-13 09:42:54 -07:00
vowelparrotandMikhail Dubov a6f767ae7a Add Slack Directory Loader (#2835)
Adds a loader for Slack Exports which can be a very valuable source of
    knowledge to use for internal QA bots and other use cases.

    ```py
    # Export data from your Slack Workspace first.
    from langchain.document_loaders import SLackDirectoryLoader

    SLACK_WORKSPACE_URL = "https://awesome.slack.com"

    loader = ("Slack_Exports", SLACK_WORKSPACE_URL)
    docs = loader.load()
```

---------

Co-authored-by: Mikhail Dubov <mikhail@chattermill.io>
2023-04-13 08:39:07 -07:00
vowelparrotand了空 709f26b69e Added bilibili loader (#2673) (#2724)
I've added a bilibili loader, bilibili is a very active video site in
China and I think we need this loader.

Example:
```python
from langchain.document_loaders.bilibili import BiliBiliLoader

loader = BiliBiliLoader(
       ["https://www.bilibili.com/video/BV1xt411o7Xu/",
       "https://www.bilibili.com/video/av330407025/"]
)
docs = loader.load()
```

Co-authored-by: 了空 <568250549@qq.com>
2023-04-11 10:40:32 -07:00
Chetanya Rastogi 50c511d75f Add new loader to load pdf as html content (#2607)
Adds a new pdf loader using the existing dependency on PDFMiner. 

The new loader can be helpful for chunking texts semantically into
sections as the output html content can be parsed via `BeautifulSoup` to
get more structured and rich information about font size, page numbers,
pdf headers/footers, etc. which may not be available otherwise with
other pdf loaders
2023-04-09 17:57:25 -07:00
e90d007db3 Harrison/msg files (#2375)
Co-authored-by: Sahil Masand <masand.sahil@gmail.com>
Co-authored-by: Sahil Masand <masands@cbh.com.au>
2023-04-04 06:48:34 -07:00
Kevin Huang e4cfaa5680 Introduces SeleniumURLLoader for JavaScript-Dependent Web Page Data Retrieval (#2291)
### Summary
This PR introduces a `SeleniumURLLoader` which, similar to
`UnstructuredURLLoader`, loads data from URLs. However, it utilizes
`selenium` to fetch page content, enabling it to work with
JavaScript-rendered pages. The `unstructured` library is also employed
for loading the HTML content.

### Testing
```bash
pip install selenium
pip install unstructured
```

```python
from langchain.document_loaders import SeleniumURLLoader

urls = [
    "https://www.youtube.com/watch?v=dQw4w9WgXcQ",
    "https://goo.gl/maps/NDSHwePEyaHMFGwh8"
]

loader = SeleniumURLLoader(urls=urls)
data = loader.load()
```
2023-04-02 14:05:00 -07:00
Harrison Chase e57b045402 bump version to 128 (#2236) 2023-03-31 11:16:21 -07:00
Harrison ChaseandJiří Moravčík 2eeaccf01c Harrison/apify (#2215)
Co-authored-by: Jiří Moravčík <jiri.moravcik@gmail.com>
2023-03-30 20:58:14 -07:00
Matt Robinson 3dfe1cf60e feat: document loader for epublications (#2202)
### Summary

Adds a new document loader for processing e-publications. Works with
`unstructured>=0.5.4`. You need to have
[`pandoc`](https://pandoc.org/installing.html) installed for this loader
to work.

### Testing

```python
from langchain.document_loaders import UnstructuredEPubLoader

loader = UnstructuredEPubLoader("winter-sports.epub", mode="elements")
data = loader.load()
data[0]
```
2023-03-30 20:45:31 -07:00
Max Caldwellandmaxtheman 3dc49a04a3 [Documents] Updated Figma docs and added example (#2172)
- Current docs are pointing to the wrong module, fixed
- Added some explanation on how to find the necessary parameters
- Added chat-based codegen example w/ retrievers

Picture of the new page:
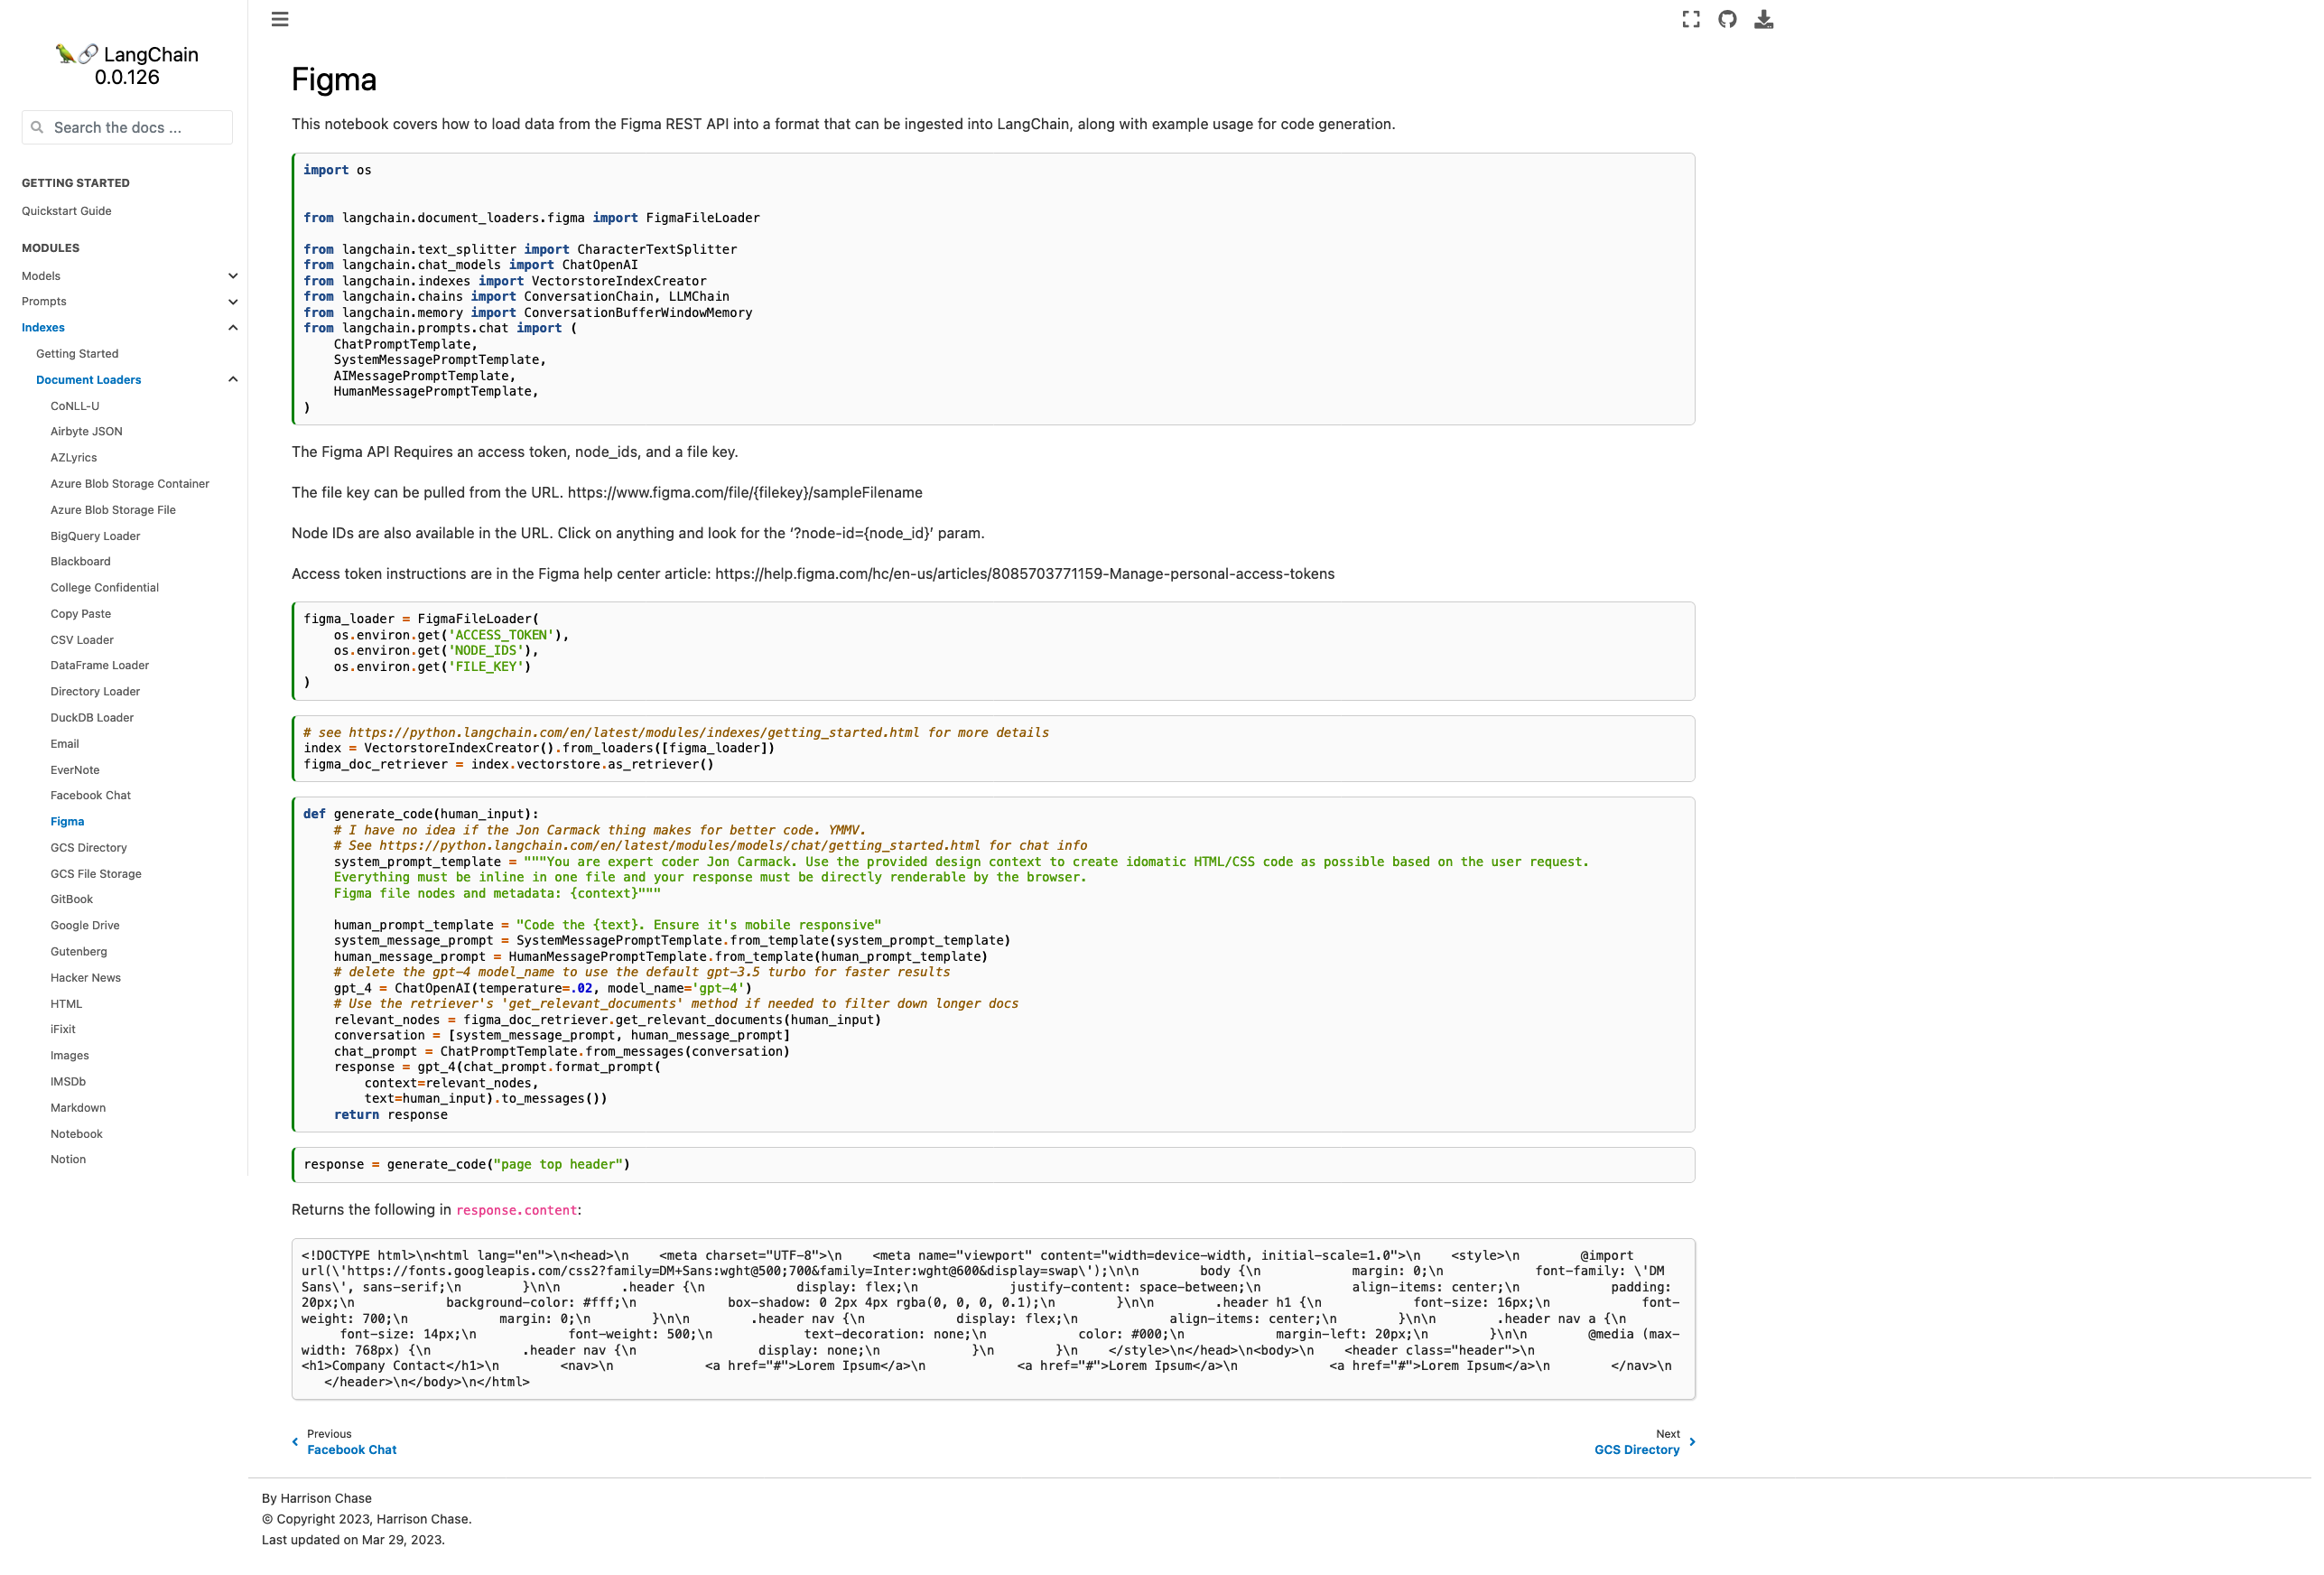
![Screenshot 2023-03-29 at 20-11-29 Figma — 🦜🔗 LangChain 0 0
126](https://user-images.githubusercontent.com/2172753/228719338-c7ec5b11-01c2-4378-952e-38bc809f217b.png)

Please let me know if you'd like any tweaks! I wasn't sure if the
example was too heavy for the page or not but decided "hey, I probably
would want to see it" and so included it.

Co-authored-by: maxtheman <max@maxs-mbp.lan>
2023-03-29 22:11:45 -07:00
Chase Adams b5449a866d docs: tiny fix on docs verbiage (#2124)
Changed `RecursiveCharaterTextSplitter` =>
`RecursiveCharacterTextSplitter`. GH's diff doesn't handle the long
string well.
2023-03-28 22:56:29 -07:00
Harrison Chaseandlu-cashmoney 410bf37fb8 Harrison/big query (#2100)
Co-authored-by: lu-cashmoney <lucas.corley@gmail.com>
2023-03-28 08:17:22 -07:00
Stéphane Busso 0bee219cb3 feat: Add Notion database document loader (#2056)
This PR adds Notion DB loader for langchain. 

It reads content from pages within a Notion Database. It uses the Notion
API to query the database and read the pages. It also reads the metadata
from the pages and stores it in the Document object.

2023-03-28 08:07:09 -07:00
Harrison ChaseandMoshe d5825bd3e8 Harrison/whatsapp loader (#2085)
Co-authored-by: Moshe <hello@moshemalka.me>
2023-03-27 23:43:45 -07:00
Harrison ChaseandTrent Hauck f74a1bebf5 Harrison/duckdb (#2064)
Co-authored-by: Trent Hauck <trent@trenthauck.com>
2023-03-27 19:51:34 -07:00
Harrison ChaseandDelip Rao 30e3b31b04 Harrison/document cleanup (#2062)
Co-authored-by: Delip Rao <delip@users.noreply.github.com>
2023-03-27 16:32:55 -07:00
Harrison ChaseandTim Asp a0cd6672aa Harrison/site map (#2061)
Co-authored-by: Tim Asp <707699+timothyasp@users.noreply.github.com>
2023-03-27 16:28:08 -07:00
Harrison ChaseandAnkush Gola 705431aecc big docs refactor (#1978)
Co-authored-by: Ankush Gola <ankush.gola@gmail.com>
2023-03-26 19:49:46 -07:00
